The most common vector database use cases are semantic search, retrieval-augmented generation (RAG), recommendation systems, chatbots and virtual assistants, anomaly detection, and multimodal search. Each use case depends on a vector database’s ability to retrieve results by meaning and similarity rather than exact keyword match. This fundamental capability separates vector search from traditional database queries.
This post covers what vector databases are, how they work, why each use case benefits from vector search specifically, and how to choose between a standalone vector database and a multi-model platform with native vector search built in.
What is a vector database?
A vector database is a specialized system for storing, managing, and querying data as high-dimensional vectors. Unlike relational databases that store structured data in rows and columns, or document databases that handle JSON, vector databases store mathematical representations of data called embeddings. They retrieve the most relevant results by measuring the distance between those embeddings.
An embedding model converts text, images, audio, and video into a list of numbers called a vector. These numbers encode the content’s semantic meaning. In vector space, “king” and “queen” are mathematically closer than “king” and “apple” because they share similar contexts. This positional relationship is what enables similarity-based retrieval.
Vector databases sit alongside transactional and analytical databases in a modern architecture. They provide the long-term memory and contextual retrieval AI models need, bridging the gap between raw enterprise data and the reasoning capabilities of large language models (LLMs).
For a deeper look at the architecture, see Vector Database Architecture: What Tech Buyers Should Evaluate.
How vector databases work
Embeddings and similarity search
Embeddings are vector representations generated by AI models (such as OpenAI’s text-embedding models or open-source equivalents from Hugging Face) that process data and transform it into a dense array of floating-point numbers. These numbers capture the data’s semantic essence rather than its literal content.
Similarity search measures the distance between a query vector and stored vectors. The closer the vectors are in multidimensional space, the more relevant the stored item is to the query. This allows a search for “automobile” to return results for “car” and “vehicle” because those concepts occupy similar positions in vector space, even without explicit synonym configuration.
Indexing and nearest-neighbor search
Searching millions or billions of vectors without an index is computationally prohibitive. Vector databases use specialized indexing algorithms such as Hierarchical Navigable Small World (HNSW) or Inverted File Index (IVF) to organize vectors for fast approximate nearest neighbor (ANN) search. These indexes let the system find the most relevant results quickly and accurately, even at massive scale.
How vector search differs from keyword search
Traditional keyword search relies on lexical matching. A search for “automobile” finds documents containing the string “automobile.” It misses documents about “cars” or “vehicles” unless synonym lists are manually maintained and updated.
Vector search retrieves results based on meaning. “Automobile” and “car” are semantically equivalent in vector space, so both appear in results regardless of exact string overlap. This shift from literal matching to semantic understanding is what makes vector databases essential for AI applications.
Why vector databases matter for AI applications
Semantic understanding vs. lexical matching
Lexical matching fails when user intent is ambiguous or when the query and source data use different vocabulary. In a customer support context, a user might describe a problem in nontechnical language while the solution is documented in technical terms. In that case, a keyword search would fail, but a vector search would succeed because it matches meaning, not strings. The practical result is faster resolution times and higher customer satisfaction without requiring users to learn technical vocabulary.
Scalability, performance, and real-time inference
Customer-facing AI applications require low latency. When a user interacts with a search bar or a chatbot, the results must appear in milliseconds. Traditional databases struggle to perform similarity calculations fast enough, but vector databases are engineered specifically for this query pattern. This allows them to deliver the high throughput and low latency real-time inference requires.
Connecting proprietary data to LLMs
An LLM trained on public data doesn’t know your company’s private documentation, current product specifications, or customer history. By storing proprietary data as vector embeddings in a vector database, organizations can supply an AI model with relevant, up-to-date context at inference time. This capability underpins RAG architecture and is essential for deploying AI that is specific to a given business domain.
Vector database use cases
Semantic search
Semantic search is one of the most common uses for vector databases. It lets organizations search large collections of internal documents, legal records, or product catalogs using everyday language, even when the wording differs from the source material. For example, a search for “contract cancellation policy” can surface a document titled “agreement termination procedures” because the two phrases have similar meanings.
The result is a more useful search experience. Employees can find relevant information faster, and customers can discover products that better match what they’re looking for. Semantic search is especially valuable when information is spread across diverse document collections and people use different terms to describe the same thing.
RAG
RAG is the primary driver of enterprise vector database adoption. In a RAG architecture, when a user submits a question to an AI model, the system first queries the vector database to retrieve the most semantically relevant internal documents. The system then passes those documents and the original question to the LLM, which generates a response grounded in the retrieved content rather than relying solely on training data.
The practical benefit is significant because the AI generates answers from your organization’s trusted data. This dramatically reduces hallucinations and ensures that responses reflect current, authorized information rather than the LLM’s potentially outdated training knowledge.
Recommendation systems
Vector databases are well-suited to finding “items like this.” By representing user behavior and product or content attributes as vectors, a recommendation system can find items that are semantically or behaviorally similar to what a user has previously engaged with. The system doesn’t require predefined rules or explicit taxonomies because it measures similarity directly in the embedding space.
Personalized recommendations drive engagement and revenue without the engineering overhead of maintaining complex rules engines as product catalogs and user behaviors evolve.
Chatbots and virtual assistants
Effective chatbots require context. Without access to prior conversation history or relevant reference material, a virtual assistant generates generic responses that fail to address specific user situations. Vector databases allow chatbots to retrieve contextually relevant support articles, prior conversation threads, or product documentation in real time. This produces responses that feel specific and personalized rather than scripted.
The business outcome is automated support that resolves issues, reduces the volume of tickets handled by human agents, and lowers support costs per interaction.
Anomaly and similarity detection
Because vector databases measure distance between data points, they identify outliers effectively. A financial transaction or network login pattern that is far from the established cluster of normal activity can be flagged as anomalous based on its vector distance from known-good examples. The same mechanism works in reverse for deduplication. In this case, the system identifies near-identical items in massive datasets by vector proximity, not by exact string comparison.
Fraud detection improves as the system continuously updates its model of normal behavior. This helps it adapt to changing attack patterns without relying on static rules that require manual maintenance.
Image, audio, and multimodal search
Vector databases can also power search across images, audio, and video in addition to text. With the right embedding models, users can find images by describing what they’re looking for in natural language, such as “red sports car on a beach,” or by uploading a similar image. This makes it much easier for organizations to search large digital asset libraries in ways that keyword-based systems can’t support effectively.
This capability opens new possibilities for digital asset management, content discovery, and any domain where rich media is the primary data format. Here’s an example of how you can build a multimodal AI app that turns an image into an embedding and retrieves visually similar results.
How do vector databases compare to traditional databases?
Vector databases and traditional databases optimize for different workloads and work best together rather than as alternatives. This table summarizes their key differences:
When to use a vector database vs. a traditional database
Vector databases are a good fit when an application needs to find information based on meaning rather than exact matches. This includes natural-language search, personalized recommendations, and RAG pipelines that retrieve relevant context for AI models.
Traditional databases are better suited to workloads that rely on structured queries, transactional integrity, access controls, and consistent performance for day-to-day operations.
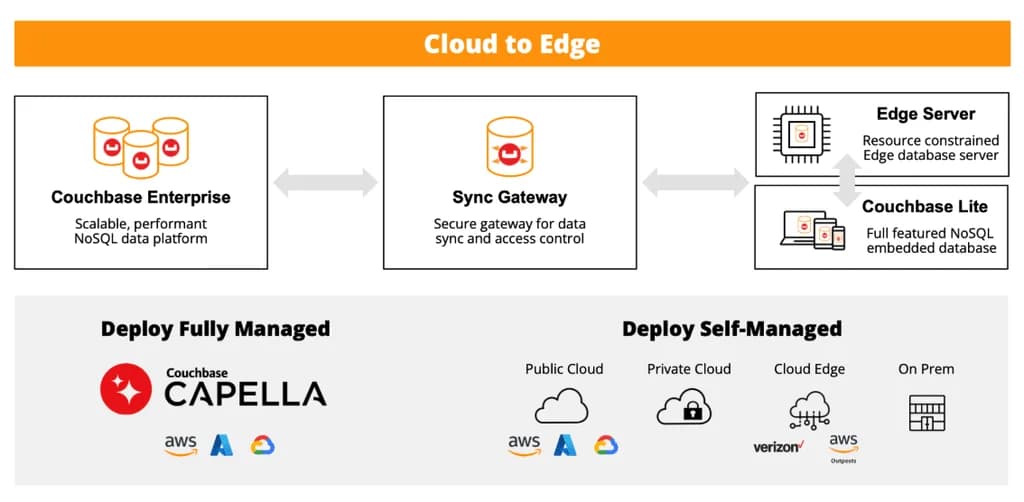
In many production AI applications, the best approach is to combine the two. A traditional database stores the application’s core data, while vector search helps AI systems find relevant information and deliver more context-aware experiences. Platforms like Couchbase bring these capabilities together, allowing teams to build AI applications without splitting their data across separate systems or sacrificing governance and scalability.
Architectural considerations for vector search
Data ingestion and embedding pipelines
Building a vector search capability requires a pipeline to convert raw data into vectors. This involves selecting an embedding model (such as OpenAI, Cohere, or Hugging Face) and automating the process so that new data is vectorized and indexed as it enters the system. The choice of embedding model has downstream consequences because different models produce vectors of different dimensionality, and changing models after ingestion requires re-embedding the entire dataset.
Latency, scale, and consistency requirements
Large vector datasets require significant memory and compute for indexing. Teams must evaluate whether a fully managed DBaaS solution handles the operational overhead of scaling, or whether regulatory compliance requires an on-premises deployment. At billion-vector scale, the performance characteristics of the indexing approach (HNSW vs. IVF) and the memory architecture of the database become significant variables.
Integration with application and AI stacks
Vector databases must integrate with orchestration frameworks such as LangChain or LlamaIndex and with the API layer the application uses. SDKs in languages the development team already uses, such as Python, JavaScript, and Java, are a practical prerequisite. Couchbase Vector Search integrates with both LangChain and LlamaIndex and provides SDKs across all major languages.
Key takeaways
1. Vector databases retrieve results by semantic similarity, not keyword match. This makes them essential for AI applications where user intent matters more than exact terminology.
2. RAG is the most common enterprise use case. Retrieval-augmented generation uses your proprietary data to ground LLM responses, reduce hallucinations, and improve accuracy.
3. Vector search applies to text, images, audio, and video equally. Any data type that can be embedded can be searched by similarity.
4. Vector databases complement rather than replace traditional databases. Production AI architectures use traditional databases for operational data with vector search for semantic retrieval.
5. Scalability at the index level determines production viability. HNSW and IVF indexes handle billion-scale similarity search efficiently. Without them, linear vector scan is impractical at production data volumes.
6. Real-time inference requires low-latency vector retrieval. User-facing applications need results in under 100 milliseconds, and this requirement shapes both index selection and infrastructure sizing.
7. Anomaly detection and deduplication are underused applications. Vector distance identifies outliers and near-duplicates in ways that keyword-based systems can’t. Applications include fraud detection, security monitoring, and data quality.
- Get Started With Couchbase Vector Search in 5 Minutes – Blog
- Vector Search – Products
- Supercharge Your RAG Application With Couchbase Vector Search and Unstructured.io – Blog
- Vector Database Architecture: What Tech Buyers Should Evaluate – Blog
- Building Smarter Agents: How Vector Search Drives Semantic Intelligence – Blog
- Vector Database vs. Graph Database: Differences and Similarities – Blog
FAQs
When should an organization add a vector database to its existing data stack? Add a vector database when building AI features that require handling unstructured data or retrieving context by meaning rather than exact keywords. Semantic search, recommendation engines, LLM-powered chatbots, and RAG pipelines are the clearest signals that vector search capability is needed.
What are the most common enterprise vector database use cases in production? The most common production use cases are RAG for powering internal knowledge bots and customer support agents, followed by semantic search for e-commerce and content platforms. Fraud and anomaly detection are growing rapidly as organizations recognize that vector distance is a more adaptive signal than static rules.
How do latency requirements vary across vector database use cases? User-facing applications such as search bars and chatbots require extremely low latency, typically under 100 milliseconds, to maintain an acceptable user experience. Background processes such as duplicate detection or batch recommendations can tolerate higher latency but often require higher throughput. Infrastructure sizing and index selection should match the latency requirements of the primary use case.
How do data freshness and update frequency affect vector-based applications? High-frequency updates challenge vector indexes, which may need rebuilding or partial updates as new data arrives. Applications relying on real-time data (live news, market data, sensor streams) require a vector database optimized for real-time ingestion and incremental index updates rather than batch rebuilds.
Can vector databases meet enterprise requirements for filtering, security, and access control? Yes. Enterprise-grade vector databases support filtered search, which combines semantic queries with metadata filters (for example, “find contracts similar to this one, but only from 2025”). They also support role-based access control and encryption. Couchbase vector search supports hybrid queries combining vector similarity, keyword matching, and structured metadata filters in a single SQL query.
What metrics measure the success of vector database deployments? The primary technical metric is Recall@K, which is how often the relevant item appears in the top K results. Query latency (response time at p95 and p99) measures production performance. For business outcomes, click-through rate for search results and deflection rate for support chatbots translate vector database performance into measurable impact.