The prompt is how you ask the question and the analysis is what comes back. However, I'd flip it: the prompt is where every analytical decision actually gets made. The AI is carrying out decisions you already made, whether or not you realize you were making them.
The prompt is how you ask the question and the analysis is what comes back. However, I'd flip it: the prompt is where every analytical decision actually gets made. The AI is carrying out decisions you already made, whether or not you realize you were making them.
When an engagement survey closes, an HR team is often left with a few hundred open-text comments and a question about what they add up to. The usual move is to hand the pile to AI and ask for the themes, and the AI returns a set of categories and counts that can look ready to show leadership. The counts often shape who gets coached and which policies get revisited. Whether they describe what employees actually wrote greatly depends on how the request was worded.
Vina Frederick is a Senior Performance Consultant at Ochsner Health, where she's building the Performance Center of Excellence across performance management, high-potential identification, and succession planning. Frederick built HR infrastructure across several Caribbean markets and three multinational organizations before moving into US healthcare. Her record includes closing succession gaps from 35% to 20% across more than 120 critical roles. She also led an AI-assisted thematic analysis of large-scale open-text employee feedback, with a method that keeps every finding traceable to the responses behind it.
"The prompt is how you ask the question and the analysis is what comes back. However, I'd flip it: the prompt is where every analytical decision actually gets made. The AI is carrying out decisions you already made, whether or not you realize you were making them," says Frederick. Her claim is that settling the prompt first gets an HR team a more accurate picture of what the comments actually say. Deciding what to do about it ultimately stays with the team.
A dozen hidden decisions
The case Frederick lays out begins with a survey of about 800 comments and a seven-word instruction: identify the comments raising concerns about management. Underneath that one sentence are roughly a dozen separate rulings about what counts as a management concern. The AI will settle each of them on its own and apply the same answer to every comment like it, reporting a single count at the end. "It feels like a single instruction when it's actually about a dozen decisions. You just made all of them without noticing it," observes Frederick.
Frederick raises a comment that complains about a policy the employee's own manager enforces but didn't write. A second comment says the manager is doing fine and faults a process set by someone else. A person reading all 800 by hand would stop at both and make a judgment call, writing it down if doing the work properly. "The AI decides on its own whether that counts as a management concern. And then it makes the same call for every comment that is similar to it, and it never tells you it made that at all," explains Frederick.
Unrequested patterns in AI output are becoming more common discoveries within HR teams. In BambooHR's Redesigning Work: AI's Performance Review report, 92% of HR professionals are piloting or planning AI agents across the HR lifecycle. Separately, 33% have noticed AI showing a pattern of demographic bias, and 36% have seen it favor resumes and cover letters drafted by the same model. In each case the AI set the standard itself, and the result arrived as a finding HR has to stand behind.
Write the codebook first
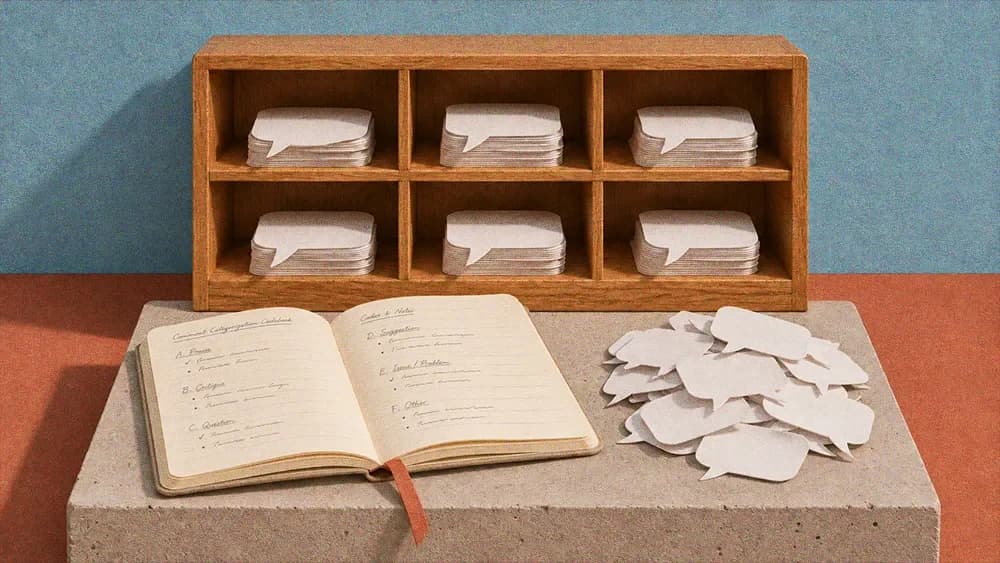
Frederick writes a "codebook" before she runs a prompt, a one-page document that names the categories for an analysis and describes each one in plain language. Tagging a comment with a category is called "coding" it, hence the name. Every decision in the analysis gets made on that page, ahead of the tool. "A codebook is basically a rule for sorting out comments," says Frederick. "Before you start, you'd write down exactly each category and what it means so that every comment gets sorted the same way."
Every category in the codebook carries a name, a definition of a sentence or two, and a note on what it leaves out. Frederick calls that note the part some people skip and the part that does most of the work, since it keeps a comment out of a category it only loosely fits. Two or three sample comments go in underneath, and she chooses those deliberately. "You pick the tricky one that sits right on the edge, not the obvious one," adds Frederick.
Overlapping categories get a rule of their own, and Frederick settles that one before any sorting begins. The whole document takes her about 20 minutes to write. Skipping it costs a team the ability to check whether the categories held, since a definition that lives only inside a prompt means whatever the AI takes it to mean. "If a comment fits two themes, does it count in both, or is it only in the main one?" asks Frederick. "Decide once at the start of everything."
Catching definition drift
A category definition can hold early in an analysis and cover slightly more or less by the end, especially across the thousands of comments Frederick's work can involve. The codebook text stays the same, but the AI's sorting moves, manifesting in what Frederick calls "definition drift." One of her own moved three times inside a single analysis before she caught it, and the count at the end still arrived looking settled. She found it by checking a sample of comments by hand.
Reading the comments one at a time won't necessarily find the flaw, because each one was sorted correctly under the definition as it stood when the AI reached it. Frederick checks the sorting instead, comparing what the AI did with the early comments against what it did with the late ones. She also runs a second AI tool over the results to check her prompts, and the final call stays with her. "Checking your examples isn't enough," notes Frederick. "You also have to check the categories in which you categorize all the comments and how you define those categories."
In the same BambooHR report, workers spend 36 minutes a day troubleshooting AI errors and reworking prompts. Frederick's two habits run to under an hour for a whole analysis: twenty minutes goes to writing the definitions down, and about half an hour to spot-checking a sample against where the AI filed them. She describes the up-front work as getting more out of the hours a team already spends. A number that turns out wrong does the most damage on a lean team. "It's never a choice between being careful and being fast, especially if you're a small team or a team of one," Frederick concludes. "Your credibility is the whole job."