As AI systems become more capable, researchers are increasingly asking a practical question: Can AI do more than help write code for computing systems? Specifically, can it actively participate in the design of complex computing systems and rapidly translate algorithms into silicon? New work in AI-driven chip design suggests the answer is yes. But a promising algorithm is only the beginning of a hardware design. Turning it into an efficient chip requires exploring how to organize computation, move data, and use limited hardware resources. Each choice opens up alternatives. Each alternative takes engineering effort to implement and evaluate.
AI agents can expand that exploration. Working together, they can propose architectural changes, write implementations, check correctness, and use synthesis results to decide what to try next. The obstacle is cost: the LLM tokenomics for hardware design and the cost-efficiency of design space exploration. A single search campaign can consume hundreds of millions of tokens, and applying the approach across many components and design revisions could require hundreds of such campaigns.
A new demonstration from IBM Research shows how open frontier models and efficient distributed inference can change the calculation. Using an agent factory to optimize hardware for quantum error correction, researchers achieved a 52-times speedup over the baseline design in high-level synthesis estimates for approximately $26 in inference cost. Under the same search budget, a proprietary frontier model configuration cost 11.5 times more than a configuration using open frontier models throughout — $299 versus $26, respectively. The proprietary configuration achieved higher speedup (204x), but the open-model configuration established a different result: Substantial hardware optimization can be achieved with a much smaller inference budget, along with the smallest area design.
That cost advantage creates an opportunity to apply automated exploration more widely, and to reinvest the savings in finding better designs.
The results also suggest that the practical value of AI-assisted chip design depends on more than the best design an agent can produce. It also depends on how much verified exploration an organization can afford. Model capability, the assignment of agent roles, and the infrastructure serving those models all shape the hardware improvements that are attainable within a real engineering budget. By combining open frontier models with llm-d’s low-cost distributed inference, IBM has demonstrated that AI agent factories can move beyond coding assistance and become active participants in hardware design, and they can do it affordably.
From generating code to exploring architectures
Hardware design remains one of the most expertise-intensive activities in computing. High Level Synthesis (HLS) raises the level of abstraction from register-transfer level (RTL), used in hardware design languages, to C or C++, but engineers must still make countless decisions about loop structure, parallelism, memory organization, dataflow, and synthesis directives. Those choices interact in complex ways. For example, performing more calculations simultaneously helps only if the memory system can supply their inputs. A design that runs faster may also require more hardware resources. Finding a useful balance requires repeated experiments, and the design space quickly becomes too large for humans to explore exhaustively.
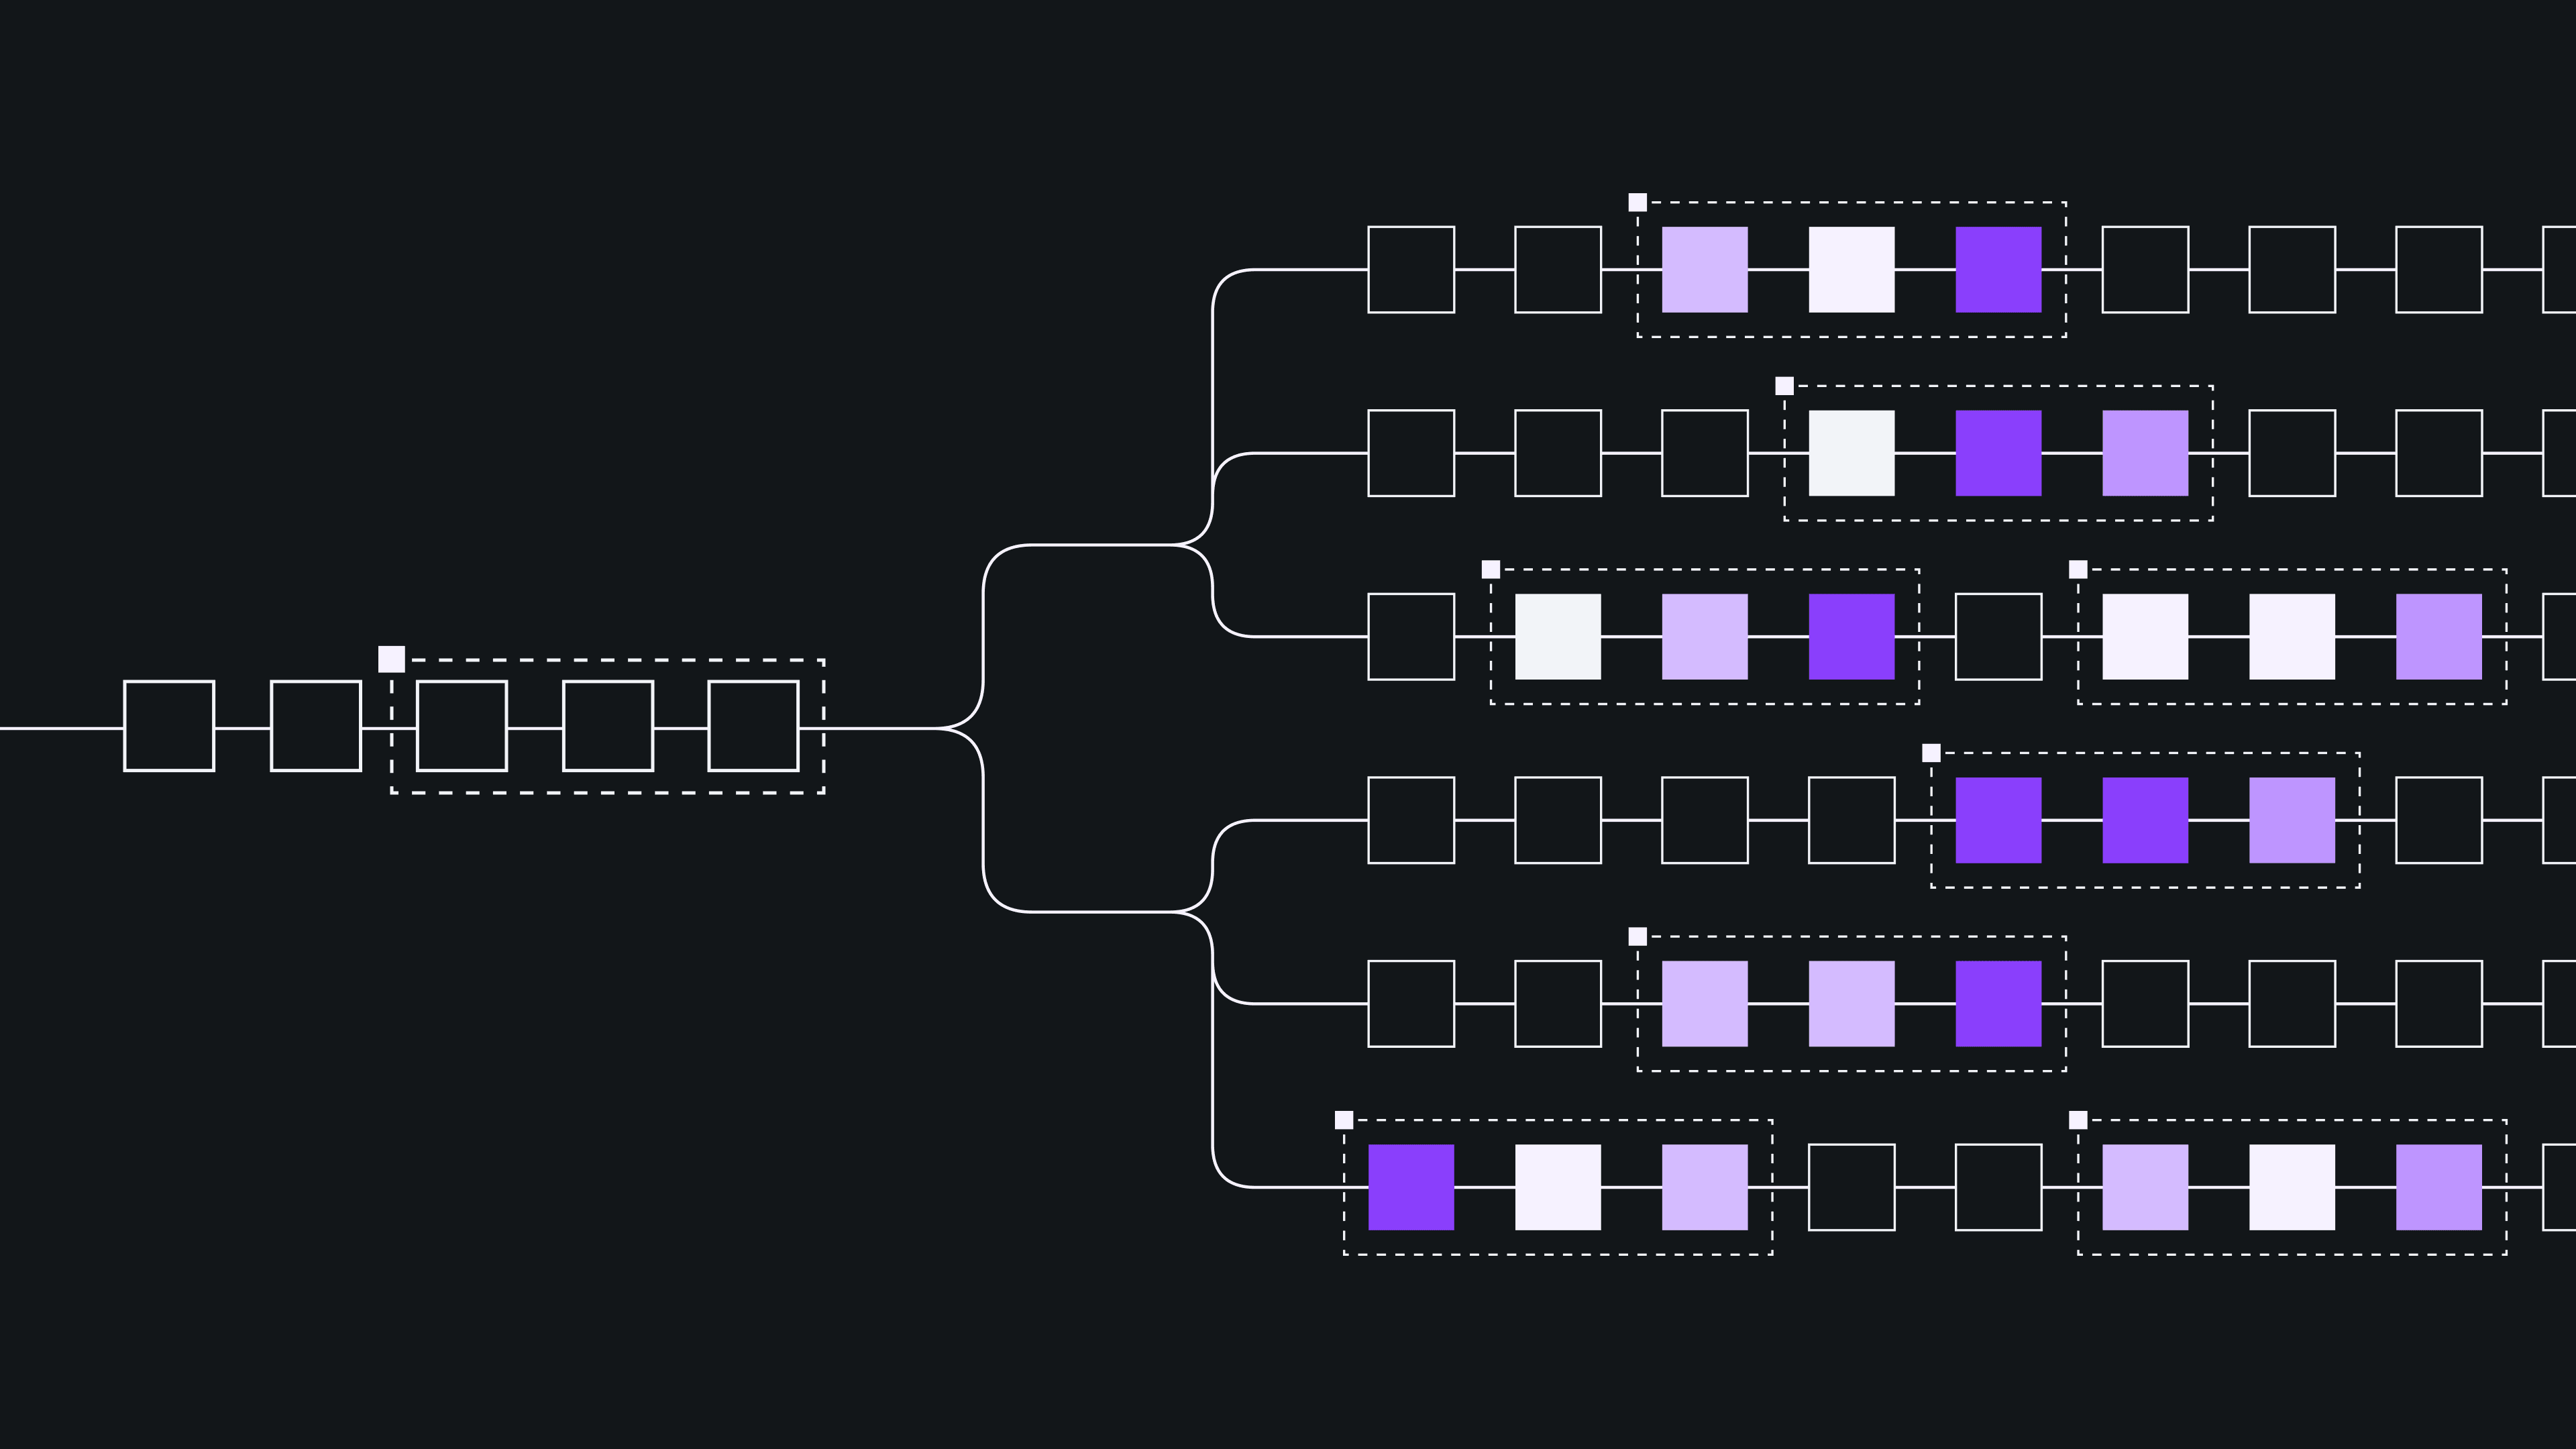
An ‘agent factory’ organizes that work. “An agent factory turns hardware optimization into a coordinated cycle of exploration: A coordinator agent directs parallel worker agents to develop and synthesize alternative designs within a defined search budget,” said Ruchir Puri, IBM fellow and IBM Research chief scientist.
When these agents are set to their task, they independently explore optimization strategies. “A verifier checks that the proposed improvements are valid, and the designs are ranked by latency and hardware resource use. Those results guide the next round of exploration, allowing the factory to refine its search as it discovers better designs,” added Puri. Rather than searching for a single solution, the factory investigates many possibilities in parallel, using synthesis feedback to guide future exploration.
In the new study, the coordinator planned the search and assigned optimization hypotheses to four parallel worker agents. The workers modified the decoder implementation, and correctness checks and HLS results provided feedback for subsequent rounds. Each configuration received a budget of 100 hypotheses.
The agents explored changes with architectural consequences. One transformation reorganized message storage so that the synthesis tool could identify independent memory accesses and execute more work in parallel. Another replaced sequential reductions with tree structures that exposed parallel computation. The value came from connecting code changes to their hardware effects through repeated evaluation.
A classical hardware challenge at the heart of quantum computing
The key question addressed in the new paper was whether this approach can be scaled cost-effectively using open frontier models and distributed inference infrastructure. To evaluate that idea, Puri and his team demonstrated the approach using Relay-BP, a quantum error correction decoding algorithm, for the [[144,12,12]] bivariate bicycle code.
Quantum error correction relies on classical computation. Measurements provide clues about errors affecting quantum information, and a decoder must interpret those clues and infer corrections. Doing that quickly, within practical hardware resource limits, is an essential part of building fault-tolerant quantum systems.
Relay-BP is a useful test because its repeated message passing is inherently parallel, but the baseline implementation's sparse graph representation and memory-access patterns make that parallelism difficult for HLS tools to exploit.
That also makes the decoder a demanding test of AI-driven hardware exploration because the agents must preserve the computation while changing how the hardware performs it.
What the same search budget buys
The researchers compared three configurations under the same 100-hypothesis budget: a proprietary frontier model as both coordinator and workers, an open frontier model in both roles, and a hybrid with a proprietary coordinator and open-model workers. The open model ran on premises through llm-d.
All three found verified hardware improvements, but they produced distinct tradeoffs. Open and hybrid searches found useful compact designs, while the proprietary configuration more effectively converted additional resources into parallelism and lower latency. Each configuration was evaluated in one search run, so these results characterize the observed searches rather than establish a universal model ranking.
The all-open search also used more tokens: approximately 241 million, compared with 216 million for the all-proprietary search. Its lower cost came from the economics of serving those tokens. This distinction matters for agent factories, where each hypothesis can involve many rounds of reasoning, coding, debugging, and interpreting tool results.
Why inference infrastructure matters
An agent factory repeatedly returns to much of the same information: source code, design constraints, earlier changes, and synthesis reports. Efficient serving can reuse computation associated with that shared context.
The study used llm-d, an open-source distributed inference framework, to support this workload. Its cache-aware routing directs requests toward servers holding reusable context. It also separates prompt processing from token generation, allowing the system to allocate resources to each independently. These capabilities help reduce repeated work and use accelerator capacity efficiently.
As enterprises seek to rein in rising inference costs and maintain control of their sensitive data, this latest demonstration showed that open-weight models deployed on-premises through llm-d’s distributed inference stack can dramatically lower serving costs while still discovering valuable hardware optimizations.
For the chip-design workload, the paper reports a prefix-cache hit rate of approximately 98% and a blended serving cost of about $0.11 per million tokens. The deployment served the factory alongside other agent workloads on shared infrastructure. Open weights also allowed the team to run the model on premises and retain control over the design artifacts processed by those agents.
The cost advantage therefore reflects the combination of an open model and an efficient serving system. Both contribute to making sustained exploration affordable.
What’s next: Turning lower cost into better designs
Lower inference cost creates room for additional search, but spending more does not automatically produce proportionate improvements. Extending the all-open campaign from 100 to 200 hypotheses increased its speedup from 52× to 60×. The gains continued, but they diminished.
The next step is to improve how the agent factory uses that additional budget. Future work will explore adaptive allocation of resources, a wider range of architectural hypotheses, and selective use of stronger models for difficult transformations or search coordination. The aim is to navigate the cost–quality tradeoff deliberately: deciding where additional reasoning, a different model, or a new architectural direction is most likely to improve the design.
Evaluation will also need to account for synthesis and verification costs alongside inference. Lowering one part of the workflow is most valuable when the complete process can support the additional exploration it enables.
AI for chip design connects two forms of progress into a reciprocal relationship: Better hardware enables more capable AI, and more capable AI can help engineers develop better hardware. Cost-efficient agent factories make that relationship more practical. By making each search more affordable, open models and distributed inference create room to test more ideas and, with better search strategies, turn that opportunity into better chips.