Today, we are introducing the fourth generation of our Cerebras System: CS-4. The fastest AI accelerator in the industry, and a new foundation for frontier AI. Built from three new Wafer Scale Engine 3 Turbo processors, CS-4 pairs a more powerful processor with a completely redesigned new rack and system. It delivers up to 30 times faster inference than GPU systems, better economics, and a simple path to deploy hyperscale capacity.
CS-4 is designed around a simple idea: the next leap in AI infrastructure cannot come from improving one component in isolation. Compute, power, cooling, and I/O have to move forward together. The result is a system built to generate fast tokens for highly interactive experiences, while also delivering the total token capacity that large-scale operators need.
That combination matters across the AI landscape:
- Developers want responsive reasoning and agentic applications at 30x speed.
- Data center operators want higher throughput per gigawatt (GW.)
- Neoclouds and hyperscalers need modular systems that can be quickly manufactured, installed, expanded, and upgraded at gigawatt scale.
CS-4 brings those priorities to life in one rack-scale platform.
Engineered for speed at scale
CS-4 achieves up to 30x better performance through coordinated innovation across the entire system. A faster wafer-to-wafer communication, high-density power delivery, and the modular Nexus rack-scale platform work as one architecture.
Up to 30x faster than GPUs
CS-4 sets a new record for the fastest inference available in production. Across the models shown below, CS-4 delivers tokens at speeds that GPU systems can’t come near, reaching up to 30 times faster inference.
Loading player...
That speed extends across the full spectrum of AI: from small, efficient models to the largest models in the world, demonstrating that greater model capability no longer has to come at the expense of speed.
Inference on CS-4 is up to 30x faster across the model set shown. Source: Artificial analysis and internal benchmarking (August 2026)
1,000 tokens per second for 10T models and beyond
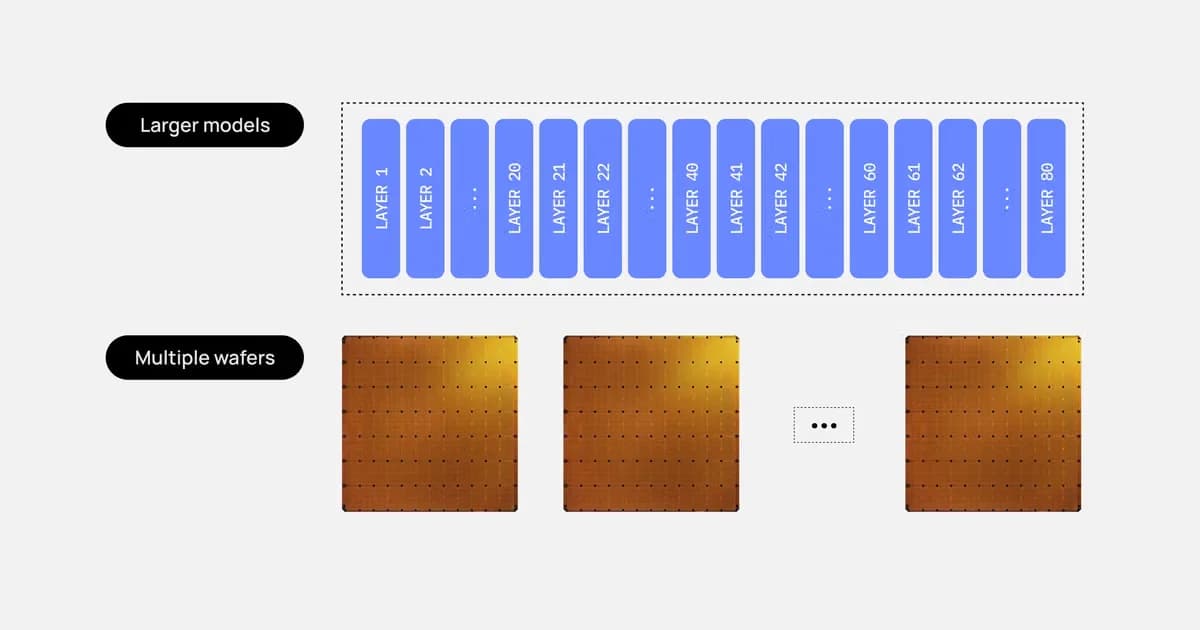
Serving massive models across multiple accelerators requires moving information between those processors quickly enough to preserve an interactive experience. CS-4 reduces wafer-to-wafer interconnect latency to as low as 2 microseconds. With this low-latency communication, CS-4 can deliver more than 1,000 tokens per second on models exceeding 10 trillion parameters.
Low-latency wafer-to-wafer communication preserves interactive decode performance as model size grows. Source: extrapolation from internal benchmarking (August 2026).
Higher ultrafast throughput
AI infrastructure has often forced operators to choose between two valuable outcomes: high interactivity for each user or high total throughput. CS-4 shifts that frontier. The CS-4 solution generates tokens up to 30 times faster than production GPU systems while delivering up to 10 times more throughput per watt than CS-3.
Because fast tokens are more valuable than slow tokens, the CS-4 delivers both higher-value tokens and more total tokens within a given power budget—enabling datacenters to be vastly more profitable. Users get a more responsive experience, while operators gain the capacity to serve more work.
The CS-4 solution delivers ultrafast inference where every millisecond matters and high aggregate output where every watt matters.
CS-4 expands the ultrafast inference frontier with up to 10x more token capacity and up to 2x faster performance than CS-3. Source: internal benchmarking and projections (August 2026).
Native support for disaggregated inference
CS-4 is designed to work as part of a heterogeneous AI infrastructure solution through native support for disaggregated inference – an approach that assigns the two major phases of inference to complementary compute platforms.
First, a purpose-built prefill engine processes the incoming prompt and prepares the model state. That state is then transferred to CS-4, where the system performs ultra-low-latency decoding and generates the response.
For operators, this architecture combines industry-leading Cerebras decode performance with the flexibility to pair CS-4 with complementary prefill platforms, including AMD Helios and AWS Trainium. Providers can use GPU or ASIC infrastructure for efficient prefill while using CS-4 for ultrafast decode, creating a heterogeneous inference system designed to deliver differentiated, high-speed services.
Disaggregated inference combines efficient prefill on a GPU or ASIC with ultrafast decode on Cerebras.
The Nexus rack-scale platform: a modular rack design to enable faster deployments
CS-4 is the first system built on the new Cerebras Nexus Platform Architecture. Nexus rethinks the rack around three foundational elements: compute, power, and I/O – bringing significant innovation to each.
Modularity changes how a rack-scale AI system moves from the factory to the data center. With 50 percent fewer components and self-contained assemblies for compute, power, and I/O, CS-4 supports faster manufacturing and rapid deployment. Instead of treating the rack as a tightly coupled collection of parts, Nexus turns it into a platform of purpose-built modules.
That platform approach also creates a cleaner path for upgrades, allowing innovation in one part of the system to reach customers without waiting for every other part to be redesigned. Nexus is built not only for CS-4, but for the future of faster cadence system-level progress.
Pluggable compute backpack design
At the center of Nexus is a fundamentally reimagined compute subsystem. CS-4 uses a rear-mounted Wafer-Scale Backpack that attaches vertically to the power array.
Each Wafer-Scale Backpack is a self-contained assembly that folds power conversion, direct liquid cooling, high-speed I/O, and control electronics into a compact, three-dimensional package built directly around the wafer.
By decoupling compute from the power supplies, the Wafer-Scale Backpack simplifies manufacturing and reduces deployment time from days to hours. Compared with the prior-generation system, the Wafer-Scale Backpack has 50% fewer components and uses 60% more automated manufacturing.
High-density power delivery
The Nexus Platform Architecture drives significant power delivery improvements. By moving power conversion 100 times closer to the processors compared to conventional GPU boards, CS-4 nearly eliminates board-level power loss. This enables the delivery of twice as much power to the WSE-3 Turbo, enabling higher operating frequencies and faster token generation.
Current reference for the integrated power-delivery assembly around the wafer.
A new modular I/O subsystem
CS-4 introduces a new programmable I/O subsystem that doubles I/O bandwidth while slashing latency. The Wafer I/O Module extends the fabric from the edges of the wafer and is designed to support both open ecosystem connectivity and the fastest direct connections between Cerebras systems.
Standards-based RoCE v2 RDMA over Ethernet provides a familiar way to connect CS-4 with existing infrastructure and with an ecosystem of heterogeneous systems. Direct Wafer Links provide for switch-free connections within and across racks. Together, these two modes give operators the flexibility to build heterogenous infrastructure, and scale massive CS-4 clusters to serve frontier AI models at more than 1,000 tokens per second.
The next-generation Wafer I/O interface extends a modular, programmable fabric from the wafer edges.
What comes next
The first CS-4 shipments begin this quarter. The fastest AI just got faster – with unmatched tokenomics and a system architecture built for hyperscale.