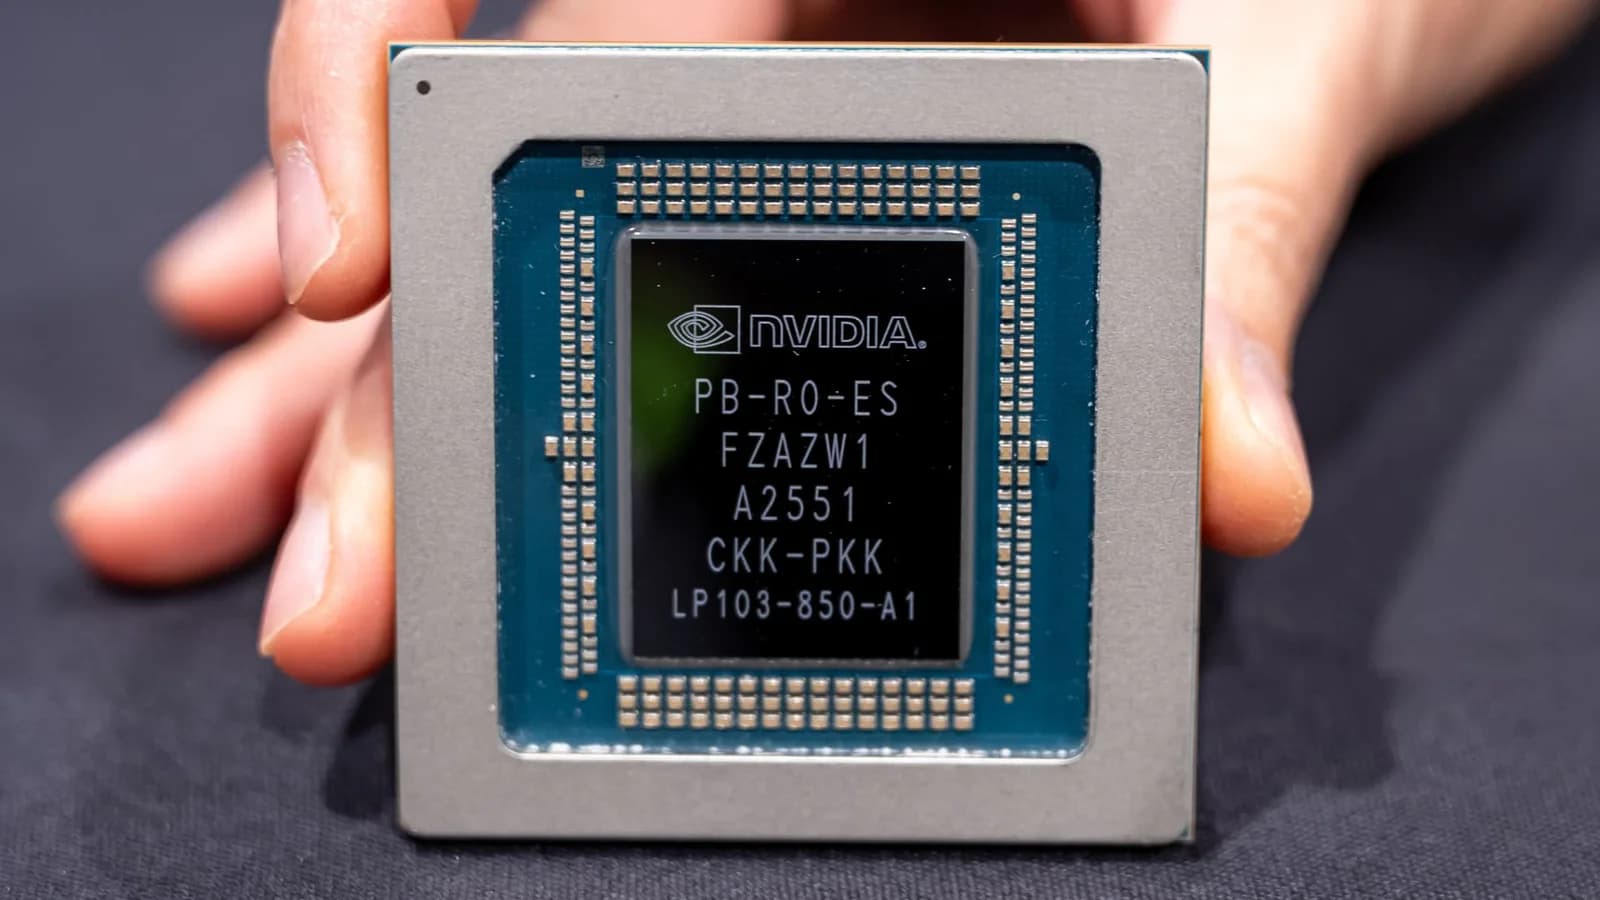
We are thrilled to announce that Groq will be among the first adopters of NVIDIA Groq 3 LPX, boosting inference token generation for NVIDIA Vera Rubin NVL72 which it will deploy to its purpose-built AI inference cloud. Groq is working with Dell Technologies to deploy NVIDIA Groq 3 LPX.
For Groq, this marks the next chapter for the company’s AI inference cloud, expanding it with NVIDIA Groq 3 LPX and Vera Rubin NVL72 to deliver responsive, large-scale AI capabilities to developers and enterprises worldwide.
Standout Performance
The extraordinary performance numbers NVIDIA published today are the clearest validation yet of the Vera Rubin platform. NVIDIA Groq 3 LPX extends the inference performance of Vera Rubin NVL72 by dramatically increasing the rate of token generation, providing premium user experiences for context-heavy workloads so agents can deliver value faster.
Key highlights include:
- Fastest performance featuring 3,400 output tokens per second running Gemma 4 31B with 100K token context, an open source agentic model, in Artificial Analysis benchmarking.
- Agentic tasks such as coding in minutes versus hours.
- 4x higher interactivity for latency-sensitive agentic AI workloads than the nearest alternative platform.
What this means for Groq customers
Groq is the only team with hands-on experience operating LPUs in production at scale. More than six million developers, Fortune 500 enterprises, and thousands of AI-native companies have built on GroqCloud, generating trillions of tokens every week across data centers in North America, Europe, the Middle East, and APAC. In August, Groq became an NVIDIA Cloud Partner to design, deploy, and operate accelerated computing to NVIDIA's own reference architecture and operational standards.
Together with Dell Technologies’ integrated infrastructure and global supply-chain capabilities, Groq’s global platform, APIs, and enterprise services will bring this next generation of inference infrastructure directly to customers.
When Groq brings NVIDIA Groq 3 LPX capacity online, it arrives on infrastructure already optimized for high-demand inference workloads. For enterprises and AI companies building the next generation of agents, Groq will provide one of the earliest paths to put NVIDIA Groq 3 LPX to work on real production workloads.
“We’re proud to be among the first to bring NVIDIA Groq 3 LPX to market, giving customers access to a new class of interactive AI inference accelerator,” said Sinclair Schuller, Chief Technology Officer of Groq. “Our customers expect Groq to be at the forefront of AI performance, and this platform represents a major advance for next-generation workloads. Together with Dell Technologies, we’re excited to deploy NVIDIA Groq 3 LPX and Vera Rubin NVL72 at scale and make this capability broadly available.”
“We’re proud to be among the first to bring NVIDIA Groq 3 LPX to market, giving customers access to a new class of interactive AI inference accelerator,” said Sinclair Schuller, Chief Technology Officer of Groq. “Our customers expect Groq to be at the forefront of AI performance, and this platform represents a major advance for next-generation workloads. Together with Dell Technologies, we’re excited to deploy NVIDIA Groq 3 LPX and Vera Rubin NVL72 at scale and make this capability broadly available.”
“Agentic AI requires more tokens, more responsiveness and scalable low cost economics,” said Dion Harris, senior director of HPC and AI factory solutions at NVIDIA. “NVIDIA Vera Rubin and Groq 3 LPX are purpose-built to deliver the low latency and high throughput these workloads require. Groq’s deep expertise operating LPUs through its global AI inference cloud will bring interactive AI inference to developers building the next generation of agentic applications.”
“Agentic AI requires more tokens, more responsiveness and scalable low cost economics,” said Dion Harris, senior director of HPC and AI factory solutions at NVIDIA. “NVIDIA Vera Rubin and Groq 3 LPX are purpose-built to deliver the low latency and high throughput these workloads require. Groq’s deep expertise operating LPUs through its global AI inference cloud will bring interactive AI inference to developers building the next generation of agentic applications.”
"Groq's inference cloud demands infrastructure built for speed and scale, and that's what Dell Technologies brings to the table,” said Arunkumar Narayanan, senior vice president, compute and networking, Dell Technologies. “We're helping bring NVIDIA Groq 3 LPX and Vera Rubin NVL72 online at scale, turning industry-leading performance into deployable infrastructure that customers can use today."
"Groq's inference cloud demands infrastructure built for speed and scale, and that's what Dell Technologies brings to the table,” said Arunkumar Narayanan, senior vice president, compute and networking, Dell Technologies. “We're helping bring NVIDIA Groq 3 LPX and Vera Rubin NVL72 online at scale, turning industry-leading performance into deployable infrastructure that customers can use today."
Media Contact
pr-media@groq.com