A manager and an analyst need different things from the same NVIDIA financial report. The manager wants an agent to read the report and answer questions. The analyst needs four values in a database to track revenue and earnings over time.
Document parsing converts a document into a machine-readable representation. Data extraction retrieves the fields an application needs. Both can return JSON (JavaScript Object Notation), so the file format alone doesn’t tell you which one to use.
We’ll use NVIDIA’s second-quarter fiscal 2027 financial results to work through both. The tutorials repository has the source document, extraction schemas, and ground-truth values.
When to use parsing, extraction, or both
Parsing converts a Portable Document Format (PDF) file, Word document, spreadsheet, or image into Markdown, HTML (Hypertext Markup Language), JSON, or Chunks. The output represents the document’s content and structure. In Datalab, this operation is called Convert.
Extraction returns values for the fields named in an Extraction Schema. You define the field names, types, and descriptions in JSON Schema format. In Datalab, this operation is called Extract.
The manager needs the report’s prose and tables so the agent can answer questions that may change. The analyst needs selected values with consistent names and units. The application can validate those values before storing them in a database.
An invoice processing application can extract the invoice number, date, and amount, then route discrepancies for review. A dashboard with a document question-answering feature needs both: extraction supplies the metrics, and parsing supplies the surrounding content.
Convert a PDF to Markdown
The Datalab Convert API can return the report as Markdown. Save the report as NVIDIA-financial-results.pdf beside your script. With the Python SDK (Software Development Kit) installed and DATALAB_API_KEY set in your environment:
The Markdown includes the report’s heading, financial tables, and commentary. An agent can read that content to answer questions about the report. The Quickstart guide covers SDK setup.
Define the fields to extract
The analyst needs four fields for the current reported quarter:
- Quarter end date.
- Revenue in millions of US dollars (USD).
- Diluted earnings per share under Generally Accepted Accounting Principles (GAAP).
- Non-GAAP diluted earnings per share.
The summary tables on page 1 use the same row labels for GAAP and non-GAAP results. Neither summary table states the quarter end date. Source: .
The report has several plausible answers to a vague request for “earnings per share.” The Extraction Schema needs to distinguish GAAP from non-GAAP, diluted from basic, and the current quarter from other periods. Revenue also needs a unit: the headline rounds to billions, while the table gives an exact amount in millions.
Save this Extraction Schema as schema.json:
The field names include the period, accounting basis, and units. The descriptions tell the model which nearby values to exclude. required names the fields the object must contain, and additionalProperties: false disallows undeclared properties in that object. Neither constraint proves that an extracted value is correct.
Here, earnings per share (EPS) fields use numbers so the application can calculate with them. The date uses a string with a date format. Keep the Extraction Schema as simple as the data permits; these four scalar fields don’t need nested objects.
The extraction documentation has more examples and a schema generation option. Review generated field descriptions against the application’s requirements before using them.
Extract the values and inspect the citations
Read schema.json and submit it with the report. Set extraction_mode="balanced" to request field metadata and verification. The separate mode option controls conversion; here we set it to "accurate".
In the sample run, the requested values were:
The saved output also has citation and metadata keys. Those keys are API annotations added alongside the requested values; select your declared fields when validating the business object against the Extraction Schema or writing it to a database.
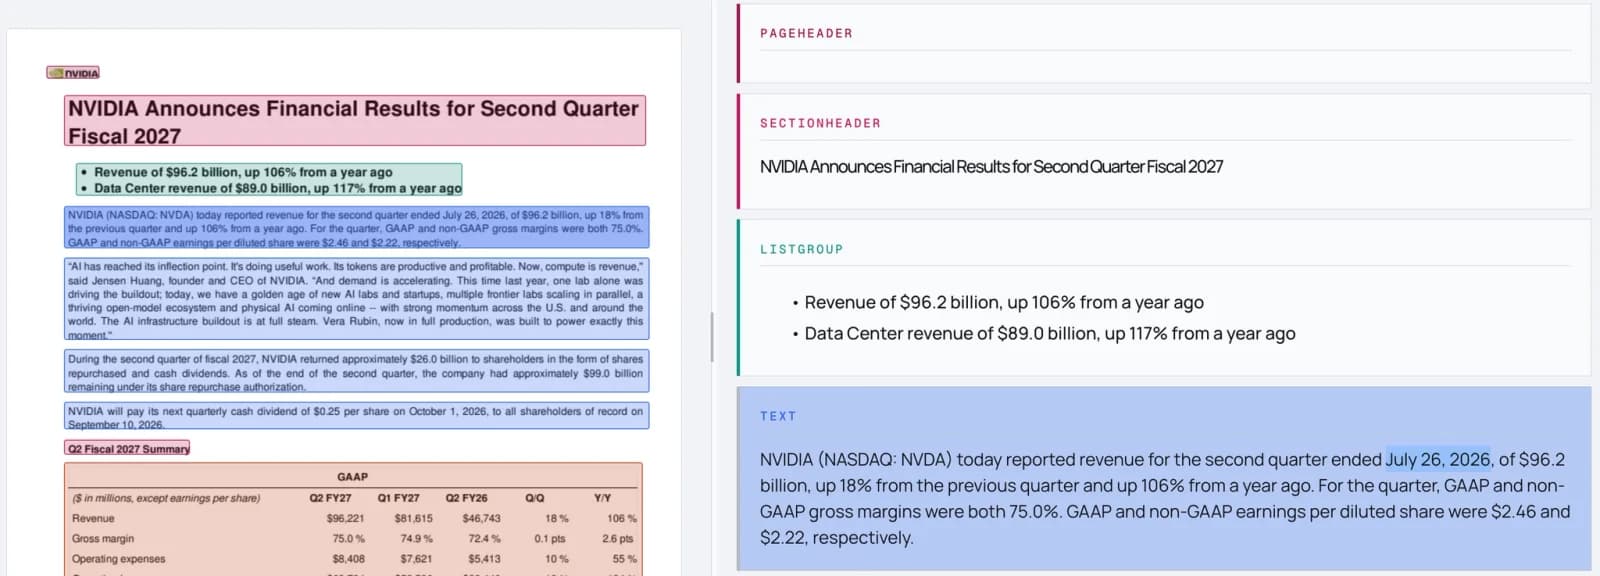
The quarter end date isn’t in either summary table. The model found it in the report’s opening paragraph. This excerpt from the saved response shows the supporting Block and verification result:
The citation /page/0/Text/3 identifies a text Block on the first page. Block identifiers use zero-based page and Block indices. The screenshot shows that Block with the date highlighted:
The source page and converted Blocks in Datalab’s document viewer. Layout boxes and the date highlight are Datalab output.
In balanced and accurate Extraction Modes, EXTRACTED means the value was found in or derived from the document. NOT_RESOLVABLE means the document doesn’t contain or imply the requested value, and the value is returned as null.
A citation locates supporting content. Verification checks the extracted value against the document and field description. A missing verification result or a status other than PASS needs review in a workflow that requires verification. A passing result still needs to match the application’s intended meaning.
An ambiguous description can pass verification
Suppose the analyst wants non-GAAP diluted earnings per share, and we give the model this Extraction Schema:
The description specifies the second quarter of fiscal year 2027, but it doesn’t specify the accounting basis. In the sample run, extraction returned the GAAP value of $2.46 and verification passed. The feedback explicitly identified it as GAAP:
The value is supported by the document and fits the description we supplied. It fails the analyst’s requirement because we left “non-GAAP” out of the description.
Changing the description to “Non-GAAP diluted earnings per share for Q2 FY27 from the financial summary tables, in USD per share” returned $2.22 in the sample run. The verification feedback cited the non-GAAP table at /page/0/Table/9 and the opening paragraph.
Use the descriptive field name quarter_non_gaap_diluted_eps_usd as well. A reviewer can identify its accounting basis and units without having to infer what eps means.
Evaluate extraction against ground truth
To measure whether extraction meets the analyst’s requirement, compare the values against independently checked answers. Omni Extract Bench has a deterministic scorer and a prediction harness for this.
The sample compares two Extraction Schemas on the same document. Both ask for the four fields above. The vague version calls the non-GAAP field diluted_eps_usd and omits “non-GAAP” from its description. The precise version uses quarter_non_gaap_diluted_eps_usd and the description in schema.json.
Use this folder structure for the following scripts:
Save schema.json as schemas/nvidia_q2_fy27.json. For the vague version, replace the non-GAAP field’s name with diluted_eps_usd in both properties and required, and use the ambiguous description above. Keep the other three fields unchanged.
Save these expected values as gold/nvidia_q2_fy27.json:
For gold/nvidia_q2_fy27_vague.json, use the same values and rename quarter_non_gaap_diluted_eps_usd to diluted_eps_usd. Its expected value stays 2.22, because that is the analyst’s requirement. The scorer pairs object fields by key, so each ground-truth file must use its Extraction Schema’s field names.
With the omni-extract-bench[harness] package installed, save this as predict.py. It submits both Extraction Schemas and saves the predictions:
The harness’s mode option selects the Extraction Mode for its Datalab adapter. This differs from the SDK’s separate mode and extraction_mode options.
Save this as score.py to score the saved predictions without another API call:
Run python eval/predict.py, then python eval/score.py.
In the sample run, the vague Extraction Schema returned the GAAP value for the field intended to hold non-GAAP earnings. Three fields matched, and the scorer labeled that field misread:
The precise Extraction Schema returned all four expected values:
These are results for four fields in one document, not an estimate of accuracy across financial reports. Model output can vary between runs. The example shows how a ground-truth comparison can catch a mismatch that passed verification.
The scoring specification defines the matching rules. Our Omni Extract Bench post describes the broader benchmark, and the dataset is on Hugging Face.
Frequently asked questions
What’s the difference between parsing and data extraction?
Parsing represents a document’s content in another format. Extraction returns selected values under field names defined in an Extraction Schema. Both can return JSON; parsing’s JSON describes the document’s structure, while extraction’s JSON contains the requested fields and any API annotations.
Do I need both?
Use both when your application needs selected values and the surrounding document content. For example, a dashboard can use extracted revenue fields for charts and converted text for questions about the report.
Does optical character recognition count as parsing?
Optical character recognition (OCR) reads text from images. Document parsing also reconstructs content such as reading order and table structure. Datalab uses OCR as part of conversion.
Does passing verification mean an extraction is correct?
A value can pass verification while failing the application’s requirement if the field description is ambiguous. Check citations and verification metadata, and evaluate the requested fields against independently checked expected values.
What do extraction evaluations measure?
They compare predicted values with ground truth. The results can expose incorrect values, missing fields, and descriptions that don’t express the application’s requirements.
To run the NVIDIA example, start with the document, Extraction Schemas, and ground-truth files in the tutorials repository.
Casey Bates is the founder and CTO of ThinkFox AI, where he builds agentic AI tools and teaches teams to use them.