The last item sells in store. The website still takes orders. The AI assistant recommends same-day pickup. One product. Three versions of reality.
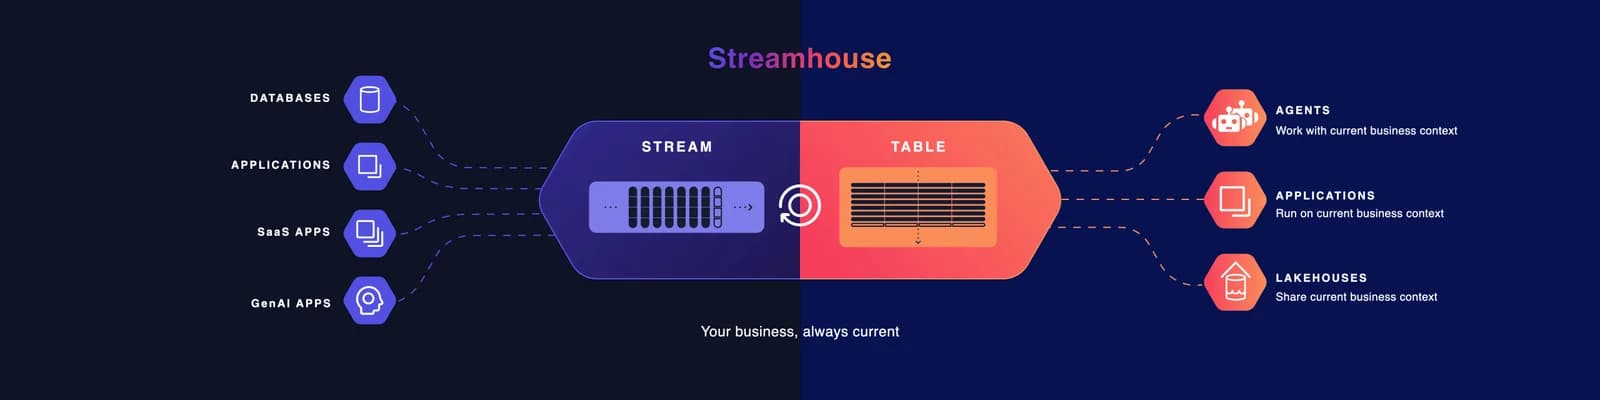
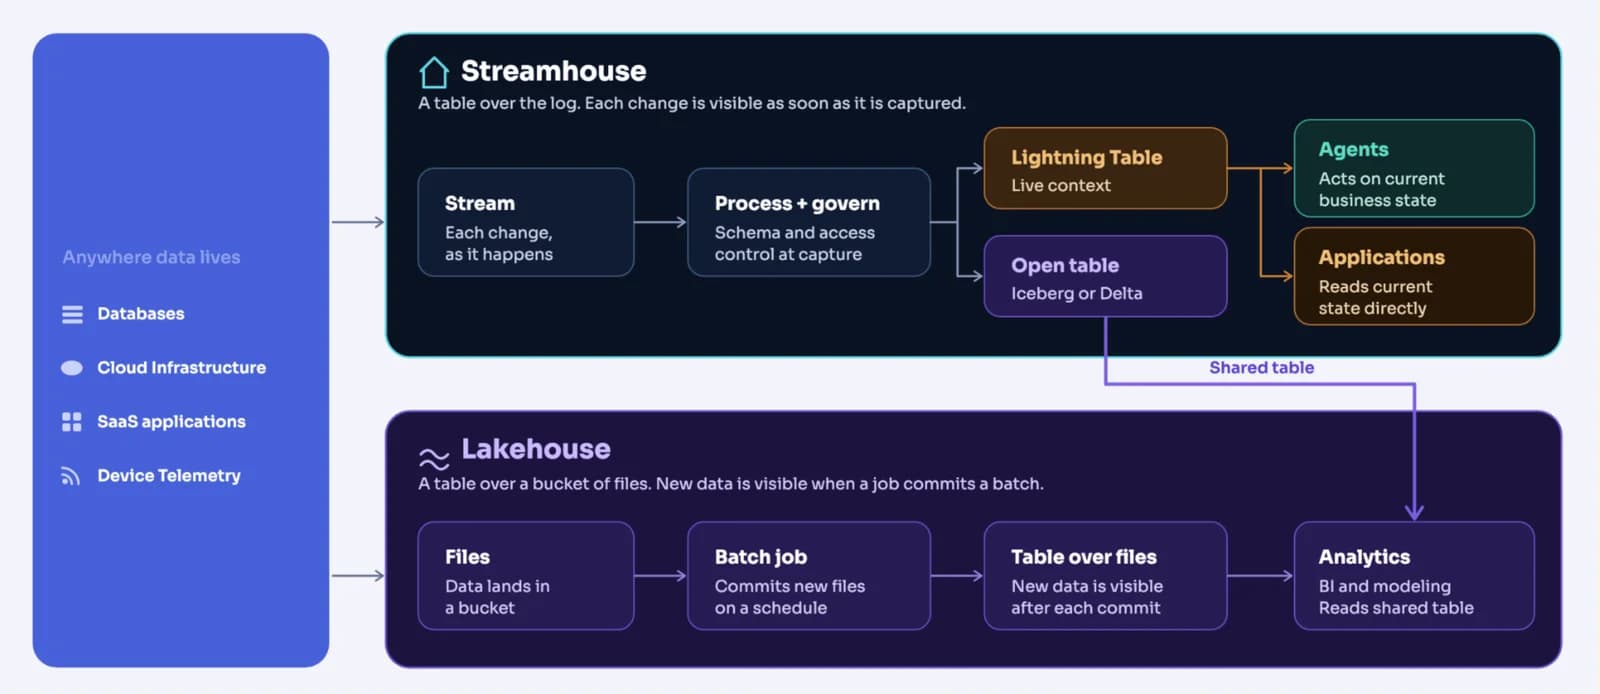
A Streamhouse keeps agents, applications, and analytics working from the same current business context. Confluent’s Data Streaming Platform (DSP) provides the most complete, performant, and open foundation for building a Streamhouse – and this quarter, that foundation gets even more powerful. Query joins Stream, Connect, Process, and Govern as the fifth DSP pillar, helping teams continuously capture, process, govern, and serve trusted, always-fresh state of the business wherever decisions happen. At the center of Query is Lightning Tables, which turn Kafka streams into a real-time state of the business, so agents and applications can query what’s true now in milliseconds – no extra database or ETL.
That same foundation brings AI closer to live business operations. With Managed Model Inference now generally available, teams can get started faster with zero configuration and more easily build AI on streaming data. Together with Confluent Gateway and Tableflow enhancements, the innovation extends across every DSP pillar to make building a Streamhouse easier, more resilient, and cost-effective. Here’s the latest across AI, Confluent Cloud (CC), Confluent Platform (CP), and WarpStream in Q4’26.
Confluent helps you build a complete Streamhouse with AI, Stream, Connect, Process, Govern, Query, and WarpStream.
Key Product Updates
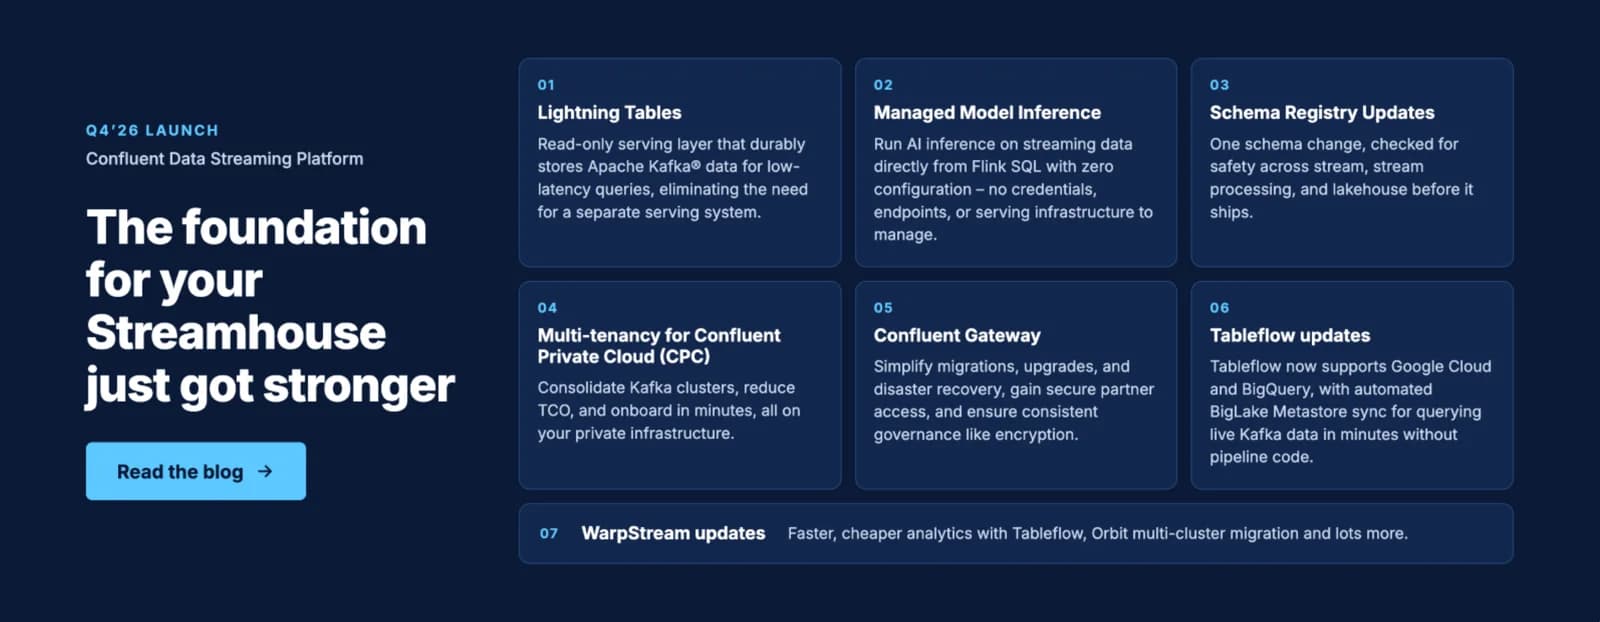
Six innovations lead this release, fulfilling DSP’s promise as the complete, performant, and open foundation a Streamhouse needs.
- Lightning Tables: Lightning Tables is a fully managed, read-only serving layer that makes Kafka data queryable with low latency and high concurrency – giving agents, applications, and analytics engines fresh business context without a separate serving database.
Lightning Tables: Lightning Tables is a fully managed, read-only serving layer that makes Kafka data queryable with low latency and high concurrency – giving agents, applications, and analytics engines fresh business context without a separate serving database.
- Managed Model Inference: Zero-configuration capability for calling supported AI and ML models from Flink SQL, enabling real-time inference without managing credentials, endpoints, or serving infrastructure.
Managed Model Inference: Zero-configuration capability for calling supported AI and ML models from Flink SQL, enabling real-time inference without managing credentials, endpoints, or serving infrastructure.
- Schema Registry Updates: Schema Registry is evolving into the foundational trust layer for your entire Streamhouse, ensuring Kafka, Flink, and the lakehouse all speak the exact same language. With new SQL-style logical schemas and proactive compatibility checks, it guarantees end-to-end pipeline safety by catching and preventing downstream breaks long before your code ever ships.
Schema Registry Updates: Schema Registry is evolving into the foundational trust layer for your entire Streamhouse, ensuring Kafka, Flink, and the lakehouse all speak the exact same language. With new SQL-style logical schemas and proactive compatibility checks, it guarantees end-to-end pipeline safety by catching and preventing downstream breaks long before your code ever ships.
- Multi-tenancy for Confluent Private Cloud (CPC): Consolidate Kafka clusters, reduce TCO, and onboard in minutes, all on your private infrastructure. Safely host many isolated Logical Kafka Clusters (LKC) on one Physical Kafka Cluster (PKC). Each LKC tenant has its own bootstrap URL, topics, consumer groups, RBAC, quotas and observability.
Multi-tenancy for Confluent Private Cloud (CPC): Consolidate Kafka clusters, reduce TCO, and onboard in minutes, all on your private infrastructure. Safely host many isolated Logical Kafka Clusters (LKC) on one Physical Kafka Cluster (PKC). Each LKC tenant has its own bootstrap URL, topics, consumer groups, RBAC, quotas and observability.
- Confluent Gateway: Simplify migrations, upgrades, and disaster recovery, gain secure partner access, and ensure consistent governance like encryption. Access Confluent Gateway SKU across Confluent Platform, Confluent Private Cloud and Confluent Cloud.
Confluent Gateway: Simplify migrations, upgrades, and disaster recovery, gain secure partner access, and ensure consistent governance like encryption. Access Confluent Gateway SKU across Confluent Platform, Confluent Private Cloud and Confluent Cloud.
- Tableflow updates: Tableflow now supports Google Cloud and BigQuery, with automated BigLake Metastore sync for querying live Kafka data in minutes without pipeline code.
Tableflow updates: Tableflow now supports Google Cloud and BigQuery, with automated BigLake Metastore sync for querying live Kafka data in minutes without pipeline code.
AI: Real-Time Context for Agents and Natural-Language Access to Confluent
Confluent Intelligence helps teams build AI on live streaming data while AI tools help you build faster and bring Confluent capabilities into the AI assistants already in use. This quarter’s updates strengthen the production foundation for real-time AI.
Confluent Intelligence updates:
- Managed Model Inference: Zero configuration allows you to run inference from Flink SQL against supported models hosted by cloud service providers (CSPs), with no credentials or configuration to set up. This is now generally available for LLMs and embedding models in Amazon Bedrock, Vertex AI, and Azure OpenAI. Managed inference abstracts away serving layers, credentials, and hardware management.
Managed Model Inference: Zero configuration allows you to run inference from Flink SQL against supported models hosted by cloud service providers (CSPs), with no credentials or configuration to set up. This is now generally available for LLMs and embedding models in Amazon Bedrock, Vertex AI, and Azure OpenAI. Managed inference abstracts away serving layers, credentials, and hardware management.
- Real-Time Context Engine: Generally available, it serves fresh context to AI agents through MCP as an access pattern for Lightning Tables. Updates includes BYOK using the customer-managed key used by the Kafka cluster, OAuth via Confluent Cloud sign-in or enterprise SSO, and metrics API visibility into storage bytes, bytes scanned, and CCU minutes, and support for backward-compatible schema changes.
Real-Time Context Engine: Generally available, it serves fresh context to AI agents through MCP as an access pattern for Lightning Tables. Updates includes BYOK using the customer-managed key used by the Kafka cluster, OAuth via Confluent Cloud sign-in or enterprise SSO, and metrics API visibility into storage bytes, bytes scanned, and CCU minutes, and support for backward-compatible schema changes.
AI Tools: Build, operate, and query in natural language
- Managed MCP servers: Generally available for use with AI assistants, Confluent's MCP servers teams explore environments and clusters, inspect topics and schemas, debug, and query. New Flink SQL tools can create, list, read, and delete statements; debug statements; retrieve metrics; and look up table structure. OAuth provides one Confluent Cloud sign-in - with no API key - across global and regional MCP servers and the Real-Time Context Engine. These AI tools are free for Confluent Cloud users working with assistants such as Claude, Cursor, and Copilot.
Managed MCP servers: Generally available for use with AI assistants, Confluent's MCP servers teams explore environments and clusters, inspect topics and schemas, debug, and query. New Flink SQL tools can create, list, read, and delete statements; debug statements; retrieve metrics; and look up table structure. OAuth provides one Confluent Cloud sign-in - with no API key - across global and regional MCP servers and the Real-Time Context Engine. These AI tools are free for Confluent Cloud users working with assistants such as Claude, Cursor, and Copilot.
- Confluent Skills: Generally available as complementary coding-assistant plugins - not MCP tools - these guided workflows help developers design, build, and debug Kafka Streams applications. The Confluent Tuning Advisor inspects Kafka configurations and recommends tuning changes without applying them.
Confluent Skills: Generally available as complementary coding-assistant plugins - not MCP tools - these guided workflows help developers design, build, and debug Kafka Streams applications. The Confluent Tuning Advisor inspects Kafka configurations and recommends tuning changes without applying them.
- Confluent Assistant: Directly in Confluent Cloud—no MCP or third-party AI assistant needed—this helps you troubleshoot fully managed connectors that have entered a FAILED state with a runtime error. It diagnoses the root cause, recommends a solution, and with explicit user consent, applies the fix and verifies the connector returns to a RUNNING state.
Confluent Assistant: Directly in Confluent Cloud—no MCP or third-party AI assistant needed—this helps you troubleshoot fully managed connectors that have entered a FAILED state with a runtime error. It diagnoses the root cause, recommends a solution, and with explicit user consent, applies the fix and verifies the connector returns to a RUNNING state.
Confluent Platform for Apache Flink AI Updates:
Confluent Intelligence on-prem AI models serving in CP Flink (Open Preview) enables you to run specialized AI models on-prem in Confluent Platform for Apache Flink (CP Flink) without data ever leaving your environment. Teams can enable production-grade, ultra-lightweight specialized AI models from a curated catalog in Confluent Manager for Apache Flink (CMF), starting with three IBM Granite Time Series Foundation models (TTM-R3, FlowState, and PatchTST-FM). These models need no pre-training and run on CPU alone, so they can be applied immediately to any time series. Enable use cases such as real-time forecasting and anomaly detection with ease. Invoke them through two new Flink SQL functions, AI_FORECAST and AI_DETECT_ANOMALIES, or in natural language through the SQL Assistant notebook. Future releases will expand the model catalog.
Confluent Assistant (NL2SQL) (Open Preview) brings a conversational, notebook-style experience to Confluent Platform for Apache Flink (CP Flink), that allows you to query real-time Flink data using natural language; no SQL experience required. Users can ask business questions about real-time streaming data in plain English, and SQL Assistant generates the corresponding Flink SQL, while keeping the underlying SQL visible and controllable. The query and results appear together in the conversation, giving users an approachable way to explore live data. Users can ask follow-up questions, continue an investigation with context from earlier exchanges, and ask the SQL Assistant to explain the SQL or results. Experienced SQL users can also review and edit generated statements or write their own SQL in the same notebook-like interface. Every statement remains visible and runnable through the existing Flink SQL execution path.
Stream
Stream is the foundation of the Streamhouse, serving as a durable multi-consumer record of every business change that applications, agents, and analytics systems can all read at their own pace. A single order event might update inventory, trigger fulfillment, inform fraud controls, and feed an AI agent, and the producer shouldn’t have to coordinate any of them. A Streamhouse feeds live applications and AI agents, so the stream beneath it must be easy to adopt, control, monitor, and quick to recover. This quarter, Confluent delivers on every one. On Confluent Cloud, you can recover from outages seamlessly, migrate one topic at a time to reduce multi-team coordination, and find platform capabilities faster. On private infrastructure, multi-tenancy in Confluent Private Cloud lets platform teams run Kafka as a shared service without choosing between isolation and efficiency.
Automatic Failover
Automatic Failover is a fully managed active/passive disaster recovery (DR) capability for Kafka in Confluent Cloud. By pairing primary and secondary clusters, it allows operators to easily trigger automatic failover for mission-critical workloads. Clients are automatically redirected without endpoint changes or workload restarts, while replication seamlessly reverses for failback, eliminating complex operational toil and delivering low RTO/RPO.
Zero Cut Topic Migration with KCP
Topic-based migration gives platform teams a controlled, incremental path for moving Kafka workloads to Confluent. Supported by a single gateway endpoint and KCP orchestration, it removes application team coordination from the critical path. This allows teams to migrate and validate workloads in manageable batches based on business priorities, drastically minimizing the blast radius and overall migration risk.
New Kafka clients for Rust, Python, .NET, JavaScript and C/C++
Confluent is introducing the next generation of non-Java Kafka clients that will maintain feature parity with the Java client shipped in Apache Kafka. These clients are built on a shared Rust core derived from the Java reference implementation, delivering new Kafka capabilities within weeks of Java availability. They offer idiomatic APIs, improved performance, and reliability.
New navigation and information architecture
The redesigned Confluent Cloud navigation helps users find resources faster by making core objects immediately accessible, and full Data Streaming Platform capabilities easier to discover. It includes an environment switcher that defaults to your last-used workspace and cleanly separates admin controls in the main menu from personal preferences in the user profile. This streamlined, scalable structure reduces clicks and ensures a clear home for future platform expansions.
Apache Kafka 4.4 Now Available: Faster Kafka Streams Recovery, Expanded Queues, and Operational Hardening
The Apache Software Foundation is releasing Apache Kafka 4.4, delivering 30 community-driven improvements to Apache Kafka. The release is led by a change that cuts Kafka Streams recovery from minutes to seconds, and by two of the most requested additions to Queues for Kafka.
Multi-Tenancy for Confluent Private Cloud
Multi-Tenancy for Confluent Private Cloud enables teams to safely host many isolated logical clusters (LKCs) on one physical Kafka cluster (PKC). Each LKC tenant is a logical slice of the PKC and has its own bootstrap URL, topics, consumer groups, RBAC, quotas, and observability. With multi-tenancy, your teams can consolidate Kafka clusters, lower TCO and onboard in minutes, all on your private infrastructure. For the tenant, there is no visibility into other tenants' data or the underlying tenancy mechanism, and it feels like a dedicated cluster. Broker-enforced quotas help protect tenants from noisy neighbors.
Confluent Control Center (C3) Innovations
- Multi-Tenancy for CPC: Control Center is evolving to make private Kafka environments even easier to operate. C3 now natively supports CPC multi-tenancy.
Multi-Tenancy for CPC: Control Center is evolving to make private Kafka environments even easier to operate. C3 now natively supports CPC multi-tenancy.
- Dark Mode: Control center now offers light, dark or system themes, and you can switch between them at any time. Dark mode is easier on the eyes during long, and the default light experience is unchanged.
Dark Mode: Control center now offers light, dark or system themes, and you can switch between them at any time. Dark mode is easier on the eyes during long, and the default light experience is unchanged.
- Bring your own Prometheus: Control Center can now connect to your existing Prometheus deployment, so it no longer has to install and operate its own bundled Prometheus. Teams that already run a scalable, highly available Prometheus can point Control Center at it. That lets them monitor large Kafka deployments on the Prometheus setup you already trust, at no extra cost. It works for both Confluent for Kubernetes and Ansible deployments.
Bring your own Prometheus: Control Center can now connect to your existing Prometheus deployment, so it no longer has to install and operate its own bundled Prometheus. Teams that already run a scalable, highly available Prometheus can point Control Center at it. That lets them monitor large Kafka deployments on the Prometheus setup you already trust, at no extra cost. It works for both Confluent for Kubernetes and Ansible deployments.
Security Updates
- Advanced Security Add-On (LA): Advanced Security is an organization-level Confluent Cloud add-on that brings together all advanced enterprise security controls into one package, across all products (e.g., Kafka, Flink, Tableflow) and independent of cluster tier. Rather than managing security capabilities individually, customers get a more consistent security posture across their Confluent Cloud organization with less operational overhead. Features currently included in Advanced Security Add-on include: SCIM, BYOK, Higher IAM-related limits, Access Transparency in audit logs.
Advanced Security Add-On (LA): Advanced Security is an organization-level Confluent Cloud add-on that brings together all advanced enterprise security controls into one package, across all products (e.g., Kafka, Flink, Tableflow) and independent of cluster tier. Rather than managing security capabilities individually, customers get a more consistent security posture across their Confluent Cloud organization with less operational overhead. Features currently included in Advanced Security Add-on include: SCIM, BYOK, Higher IAM-related limits, Access Transparency in audit logs.
- Access Transparency: Access Transparency lets security and compliance teams track when and why Confluent personnel access Kafka message content on dedicated clusters across AWS, Azure, and GCP. These detailed events, including timestamps, affected clusters, and access reasons, are easily reviewable through your existing logging integrations and the Audit Log Monitoring UI.
Access Transparency: Access Transparency lets security and compliance teams track when and why Confluent personnel access Kafka message content on dedicated clusters across AWS, Azure, and GCP. These detailed events, including timestamps, affected clusters, and access reasons, are easily reviewable through your existing logging integrations and the Audit Log Monitoring UI.
Process
Stream processing turns raw data into actionable business insights to feed real-time context. Apache Flink® handles this workload upstream (Shift Left) closer to the source, so applications and AI agents read unified results while reducing ETL costs by 40–60%. This release introduces enterprise security, performance, and flexibility enhancements in Confluent Cloud for Apache Flink, along with AI capabilities in open preview for Confluent Platform.
BYOK for Enterprise Clusters (LA)
Integrate customer-managed encryption keys (AWS KMS, Azure Key Vault, GCP KMS) to encrypt Flink state and transient data at rest, enforcing strict data sovereignty and key revocation policies across processing clusters.
CSFLE and CSPE Support
Flink SQL can now seamlessly process Kafka records encrypted with Client-Side Field-Level Encryption and Payload Encryption. Governed by RBAC, only authorized principals with read permissions on Key Encryption Keys (KEKs) access cleartext.
Streaming Bootstrap with Batch Execution (OP)
This new hybrid execution mode automatically runs historical catch-up queries using high-throughput batch operators before transitioning to low-latency streaming. This accelerates backfills by 1.3x–1.5x while lowering CFU consumption.
dbt Support for Materialized Tables, Tableflow, Snapshot Queries, and OAuth
The Flink dbt adapter now manages Materialized Tables, orchestrates Tableflow Iceberg syncs, executes point-in-time Snapshot Queries, and authenticates via OAuth, enabling data engineering teams to build real-time pipelines using familiar declarative workflows.
Unlimited State Storage on AWS (LA)
By decoupling state storage from compute via cloud object storage, Flink removes the 500 GB per-statement limit. Stateful joins and aggregations can now scale to multi-terabyte datasets while reducing recovery and rescaling times to seconds.
Data Plane Statement SLA
Confluent now offers a financially backed uptime and availability SLA for Flink statement execution, guaranteeing processing availability and reliability for mission-critical streaming applications.
Query
The newest pillar, Query, is the serving layer: It makes the current state of the business directly usable, in whatever form each consumer needs. Lightning Tables give applications low-latency SQL access to continuously maintained data, while the Real-Time Context Engine serves live business context to AI agents over MCP. Tableflow turns streams into Apache Iceberg or Delta Lake tables for lakehouse engines; Snapshot Queries run ad hoc SQL across live and historical data, and Streaming Queries push results out as they change. Because these are different ways of serving the same stream of changes, teams can support applications, agents, and analytics without building a separate data pipeline for each.
Lightning Tables
Lightning Tables is a managed, read-only serving layer that durably materializes Kafka data into queryable tables. It gives applications and agents low-latency access to current business state - without separate ETL pipelines, databases, or caches - and is generally available on AWS.
- Data freshness at scale: Changes are available for serving within hundreds of milliseconds; queries return in 10–100 ms at 1,000+ queries per second.
Data freshness at scale: Changes are available for serving within hundreds of milliseconds; queries return in 10–100 ms at 1,000+ queries per second.
- Multiple ways to query: Use SQL or API access directly, or expose fresh context to AI agents through the Real-Time Context Engine via MCP.
Multiple ways to query: Use SQL or API access directly, or expose fresh context to AI agents through the Real-Time Context Engine via MCP.
- Production controls: Lightning Tables supports BYOK, backward-compatible schema evolution, usage and performance metrics.
Production controls: Lightning Tables supports BYOK, backward-compatible schema evolution, usage and performance metrics.
For example, a logistics company can combine vehicle telemetry, weather, traffic, and parcel data to answer, “What’s happening across our drivers and vehicles?” against a current view of operations – rather than stitching together separate, potentially stale systems.
That gives teams one continuously updated view of business state to serve applications, agents, and analytics.
Tableflow
Google Cloud Platform (GCP) and BigQuery (BQ) Integration
Tableflow on Google Cloud Platform (GCP) offers general availability (GA) and complete feature parity with AWS and Azure across all GCP regions supporting Confluent Cloud Flink. Tableflow materializes Kafka topics into open table formats—Apache Iceberg and Delta Lake—eliminating custom pipeline engineering and schema overhead.
Architecturally, organizations can store tables using Confluent Managed Storage (CMS) or Bring Your Own Storage (BYOS) with customer-owned Google Cloud Storage (GCS) buckets in single-region or dual-region configurations aligned with the cluster region. This release introduces native catalog synchronization with Google BigLake Metastore (BLMS), alongside Databricks Unity Catalog and Snowflake Open Catalog. As data streams, Tableflow writes Iceberg and Delta tables to GCS and asynchronously registers them in BLMS, ensuring immediate discoverability. Standard SQL queries in Google BigQuery execute directly against streaming data without manual DDL or table registration.