AI detectors look for statistical patterns, signal-level artifacts, embedded markers, and inconsistencies that may indicate content was generated or manipulated by artificial intelligence.
For text, those signals may include unusually predictable word choices, repeated structures, or stylistic patterns. Image, video, and audio detectors examine different evidence, such as frequency artifacts, inconsistent frames, synthetic speech signatures, or missing camera and recording characteristics.
However, detectors do not directly “see” that AI created something. They calculate how closely a file resembles examples of authentic or synthetic content encountered during development.
A meta-analysis of 56 studies involving 86,155 participants found an overall human deepfake detection accuracy of 55.54%, with confidence intervals crossing chance-level performance. More recent research reinforces the need to treat detection ability as context-dependent.
A 2026 meta-analysis focused specifically on deepfake faces, covering 36 studies and 13,197 participants, found 56.1% accuracy, while intervention studies involving training or feedback reached 62.2%.
This article explains what AI detectors look for across text, images, video, and audio, how the main detection techniques work, what current research says about accuracy, and how to evaluate a detector without mistaking a probability score for proof.
Key Takeaways
- AI detectors look for patterns associated with generated or manipulated content, not definitive proof of authorship.
- Text detectors may evaluate token predictability, writing complexity, repetition, syntax, embeddings, and embedded watermarks.
- Image, video, and audio detectors analyze pixels, frames, frequencies, timing, noise, metadata, and generator-specific artifacts.
- A detector that performs well on familiar benchmark data may perform worse against new generators or real-world media.
- Accuracy alone can hide serious false-positive or false-negative problems.
- Detection works best alongside provenance, watermarking, source verification, identity controls, and human review.
AI detectors look for measurable differences between content produced by generative systems and content created or recorded through conventional processes.
The exact evidence depends on the content type:
Different generators leave different patterns. Those patterns may change when content is cropped, paraphrased, translated, compressed, filtered, screen-recorded, or played through one device and recorded through another.
A 2025 survey in Computational Linguistics groups AI-text detection into statistics-based detection, neural detection, watermarking, and human-assisted approaches. A 2026 cross-modality survey similarly categorizes visual deepfake detectors into forensic, data-driven, fingerprint-based, and hybrid methods, while audio detectors use handcrafted or learned signal features.
How Do AI Detectors Work?
Most AI detectors follow five broad stages.
1. The Content Is Prepared for Analysis
The detector first converts the submitted content into a format its model can process.
For text, this may involve dividing the passage into tokens, sentences, or numerical embeddings.
For other media, the detector may:
- Convert audio into waveforms or spectrograms
- Extract individual video frames
- Divide an image into patches
- Standardize resolution or sample rate
- Separate audio and visual tracks
- Read metadata or provenance records
This preparation makes inputs more consistent, but it may also remove useful evidence if implemented poorly.
2. The Detector Extracts Features
The system identifies measurable characteristics associated with authentic or synthetic content.
Some features are chosen by researchers, such as sentence length, image noise, or spectral energy. Others are learned automatically by neural networks trained on labeled examples.
A detector usually needs multiple features because one isolated clue is rarely reliable.
3. A Model Compares the Features
The extracted features are passed to a statistical model, neural classifier, or hybrid detection system.
The model compares the input with patterns learned from authentic and generated samples. Instead of finding one decisive giveaway, it combines several signals into a prediction.
4. The Detector Produces a Score or Label
The result may appear as:
- A probability score
- A confidence score
- An “AI-generated” or “human-created” label
- A real-or-fake verdict
- Suspicious sentences
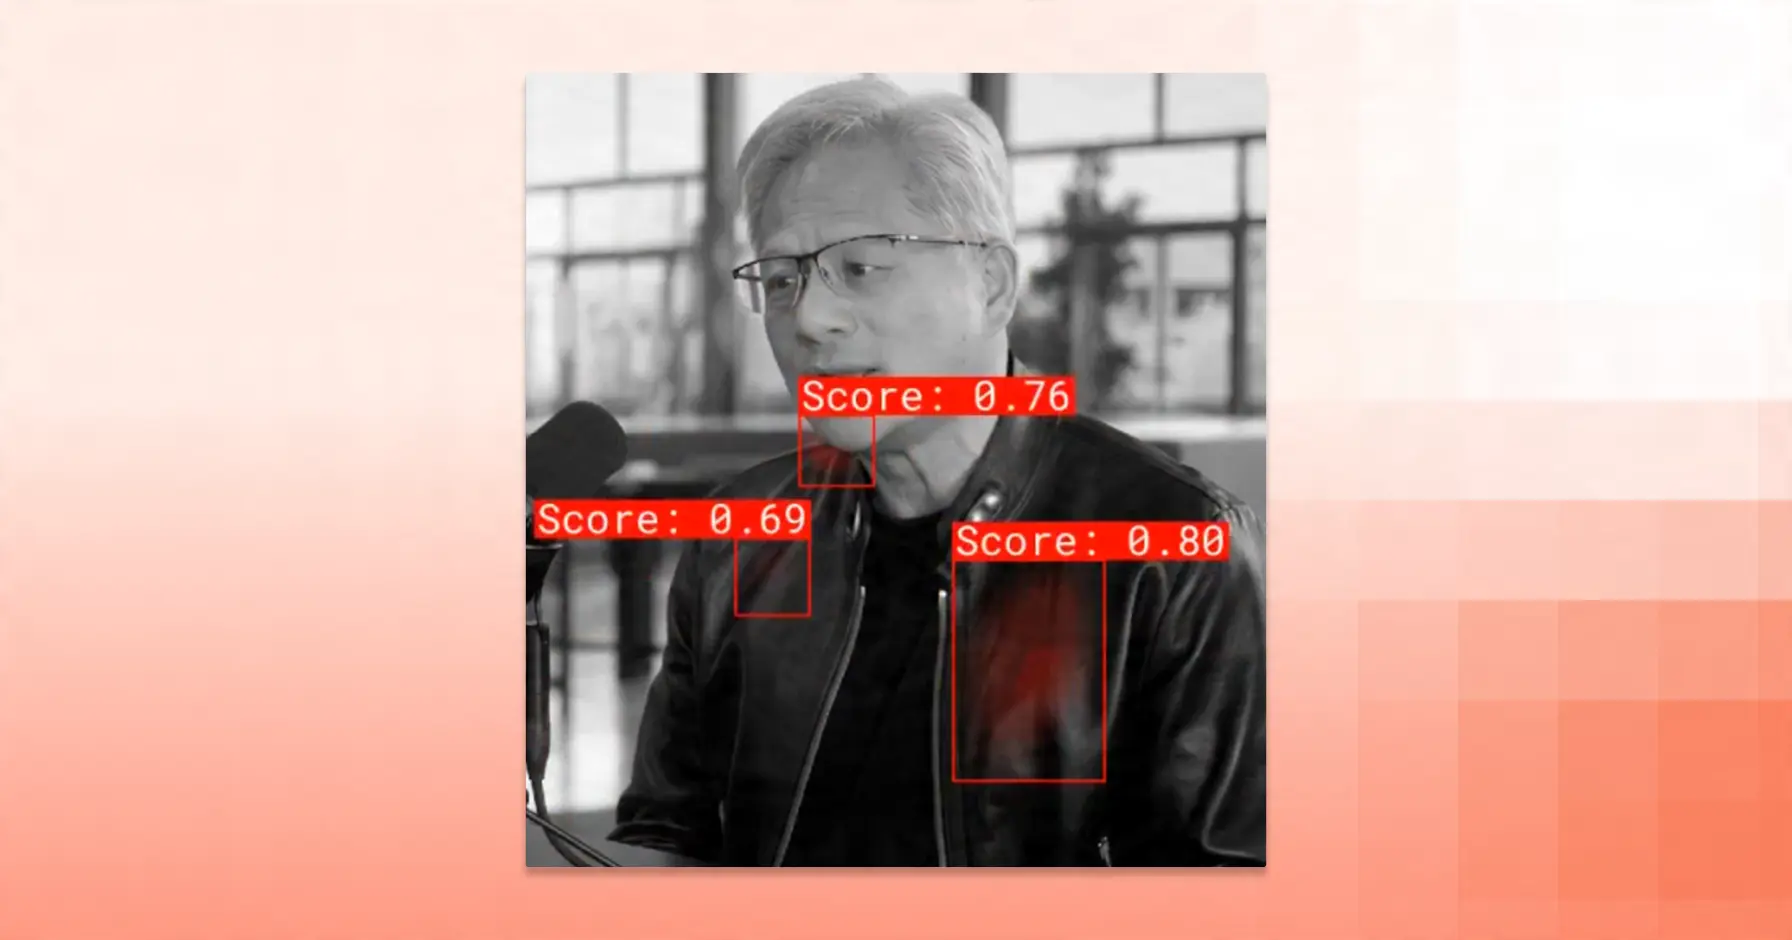
- Highlighted image regions
- Flagged audio segments
- Suspicious video frames
- An explanation of detected artifacts
The label depends on the detector’s threshold. A file receiving a score of 0.72 may be labeled synthetic at a 0.70 threshold but authentic at a 0.80 threshold.
5. The Result Enters a Decision Workflow
A responsible detection workflow does not end with the score.
The result may trigger:
- Human review
- Source verification
- Additional identity checks
- Watermark verification
- Provenance inspection
- A request for the original file
- A temporary hold on a high-risk action
- Analysis by another independent system
This final stage determines whether detection becomes a useful security signal or an unreliable automated judgment.
What Do AI Text Detectors Look For?
AI text detectors primarily look for statistical and stylistic patterns associated with large language model output.
The phrase “AI detector” is often used online to mean an AI-writing detector, so understanding text detection is essential before expanding into deepfake media.
Token Predictability and Perplexity
Large language models generate text by predicting which token is likely to come next.
A detector may evaluate how predictable those choices appear. One related measurement is perplexity, which describes how surprising a sequence is to a language model.
Lower-perplexity text follows patterns the model expects more strongly. Higher-perplexity text contains less predictable choices.
This does not mean:
- Low perplexity proves AI involvement
- High perplexity proves human authorship
- Humans always write unpredictably
- AI always selects the most likely word
Clear technical writing, translated content, standardized business copy, and writing by non-native speakers may also be statistically predictable.
Sentence Variation and “Burstiness”
Some detectors examine variation in:
- Sentence length
- Sentence structure
- Paragraph length
- Vocabulary
- Punctuation
- Grammatical complexity
- Transitions
- Writing rhythm
“Burstiness” is an informal term frequently used to describe changes in sentence length or complexity.
Although variation may contribute to a detector’s decision, burstiness is not a universal measurement used by every system. It should not be treated as a reliable standalone test.
Repetition and Formulaic Structures
AI-generated passages may contain repeated ideas, transitions, sentence templates, or paragraph structures.
Detectors may learn patterns such as:
- Repeated conclusion statements
- Uniform paragraph lengths
- Predictable list structures
- Excessively balanced sentences
- Similar wording across sections
- Frequent generic transitions
These are weak signals by themselves. Human writers use templates and repeated terminology in academic, legal, technical, and corporate writing.
Stylometric Features
Stylometry measures writing style through features such as:
- Average word length
- Vocabulary diversity
- Function-word usage
- Part-of-speech patterns
- Readability
- Punctuation habits
- Syntactic complexity
- Frequency of specific constructions
A supervised classifier may learn combinations of these features from labeled human and AI-generated samples.
The limitation is that style can reflect a writer’s education, language background, profession, assignment, or editing process rather than whether AI was involved.
Embeddings and Neural Classification
Some detectors represent the entire passage as a numerical embedding.
A neural classifier then estimates whether the representation resembles human-written or machine-generated samples in its training data.
This approach can capture relationships that simple grammar or perplexity measurements miss. However, it can still struggle when the text comes from:
- A model absent from the training set
- A new subject domain
- A different language
- A highly edited AI draft
- An unusual human writing style
- A mixture of human and AI contributions
Model-Specific Signatures
A detector may learn recurring patterns associated with a particular language model or model family.
This can produce strong results when the tested content comes from a familiar generator. It may also create poor generalization when the content comes from an unseen model or a different decoding strategy.
The RAID benchmark contains more than 6 million generations across 11 models, eight domains, 11 adversarial transformations, and four decoding strategies. Its evaluation of eight open-source and four closed-source detectors found that performance could be disrupted by unfamiliar generators, sampling variations, repetition penalties, and transformed text.
Embedded Text Watermarks
Text watermarking modifies the token-selection process while the model generates a response.
Instead of evaluating style after generation, the detector checks whether the sequence contains a statistical pattern deliberately embedded by the generating system.
Google DeepMind explains that SynthID for text adjusts token probabilities to create an imperceptible watermark. Detection works better on longer, varied responses and may become less confident after extensive rewriting or translation. It is also less effective for short factual answers where the generator has fewer valid token choices.
Watermark detection answers a narrower question than a general classifier: whether the content contains a compatible watermark, not whether any AI system could have produced it.
What Research Reveals About AI Text Detectors
Several studies demonstrate why a text detector’s score requires context.
Current AI Text Detectors Still Have Important Reliability Gaps
A 2025 NAACL study evaluated seven popular detection approaches across previously unseen domains, language models, and prompting-based evasion strategies. In some settings, the true-positive rate at a 1% false-positive rate fell as low as 0%, showing how difficult it can be to maintain both high detection sensitivity and a low false-positive rate when the input differs from a detector's original evaluation data.
Another 2025 ACL study evaluated 12 state-of-the-art detectors using a 15,000-sample dataset of human writing refined with varying amounts of AI assistance. The researchers found that detectors frequently flagged even minimally AI-polished text as AI-generated and struggled to distinguish between different levels of AI involvement.
AI Text Detector Bias Varies Across Systems and Writing Populations
A 2026 ACL study assessed 16 machine-generated text detection systems across gender, race and ethnicity, English-language learner (ELL) status, and economic status.
Although biases were inconsistent across systems, the researchers found that ELL essays were more likely to be classified as machine-generated and that non-White ELL essays were disproportionately classified as machine-generated relative to their White counterparts.
However, a separate 2026 EACL study revisiting non-native-speaker bias in Czech found no systematic bias across three detector families and found that contemporary detectors could operate without relying on perplexity.
Together, these results suggest that fairness should be evaluated for the specific detector, language, domain, and user population rather than assumed from one benchmark.
Style Changes Can Cause Major Performance Loss
A 2025 COLING study found that text classifiers were highly sensitive to writing style and complexity. In some conditions, detector performance degraded to the level of a random classifier.
The researchers also found a tendency to misclassify easier-to-read content, reinforcing the concern that writing simplicity may be mistaken for AI generation.
Benchmark Performance Does Not Transfer Uniformly
NIST’s 2024 text-to-text pilot found substantial variation between generators and discriminators. Some generators deceived most detectors, while some detector systems identified content from nearly all evaluated generators.
This means statements such as “AI detectors work” or “AI detectors do not work” are both too broad. Performance depends on the specific detector-generator pairing and evaluation conditions.
What Do AI Image Detectors Look For?
Image detectors examine visible content, raw pixel behavior, frequency information, metadata, and embedded authenticity signals.
Common evidence includes:
- Texture irregularities: Skin, hair, fabric, foliage, reflections, or backgrounds may contain repeated or statistically unusual patterns.
- Frequency artifacts: Image generators can leave patterns in spatial frequencies that are difficult to see directly.
- Noise inconsistencies: Camera-captured images contain sensor and processing noise that may differ from generated content.
- Lighting conflicts: Shadows, reflections, highlights, and light direction may not agree across the image.
- Geometric inconsistencies: Facial landmarks, object boundaries, perspective, or symmetry may behave unusually.
- Local synthesis evidence: An authentic image may contain a smaller region created through inpainting or generative editing.
- Generator fingerprints: Specific model architectures may leave recurring statistical patterns.
- Metadata: Capture device, software, modification history, and timestamps may support an investigation.
- Watermarks: A detector may search for an invisible mark embedded by a participating generator.
- Content provenance: A system may validate signed records describing where the asset originated and how it changed.
Visible mistakes such as distorted hands are becoming less useful as generators improve. Detection increasingly depends on signal-level analysis rather than a checklist of obvious visual errors.
Why Cropping and Editing Matter
A July 2026 Reuters test examined Meta’s preview watermark-verification tool for images created with Muse Image.
The tool verified all 40 original images, but failed to verify 55% after the images were cropped to approximately one-third to one-half of their original size.
This was a test of Meta’s embedded Content Seal watermark, not every kind of AI image detector. It demonstrates that watermark verification and forensic classification have different failure modes. A heavy crop may remove or weaken an embedded signal even when the remaining image is still synthetic.
What Do Video AI Detectors Look For?
Video detectors analyze both individual frames and changes between frames. They may look for:
- Facial boundaries that shift over time
- Inconsistent identity features
- Unnatural eye, mouth, or head movement
- Lip movements that do not match speech
- Changes in skin texture between frames
- Lighting or shadows that move incorrectly
- Background objects that appear or disappear
- Motion-blur inconsistencies
- Repeated frames or temporal patterns
- Differences between the audio and video tracks
- Generator-specific spatial or temporal artifacts
A single frame may appear authentic while the movement across several frames reveals manipulation.
Video detection therefore commonly combines:
- Spatial analysis: Examining the contents of each frame
- Temporal analysis: Examining consistency and movement across frames
- Audio-visual analysis: Comparing speech sounds with lip movement and identity signals
Real-World Video Is Harder Than Clean Benchmark Data
The Deepfake-Eval-2024 benchmark collected in-the-wild content circulated across 88 websites and 52 languages. It included 45 hours of video, 56.5 hours of audio, and 1,975 images.
Compared with performance on earlier academic benchmarks, the evaluated open-source detectors experienced AUC decreases of:
- 50% for video
- 48% for audio
- 45% for images
The study does not prove that all commercial or newly trained detectors lose the same amount. It demonstrates how strongly performance can change when systems encounter current, real-world content rather than familiar laboratory datasets.
What Do Audio AI Detectors Look For?
Audio deepfake detectors examine the waveform, frequency spectrum, timing, and speech-production characteristics.
Common signals include:
- Spectral artifacts: Synthetic speech systems may produce frequency patterns that differ from recorded speech.
- Phase behavior: Relationships between components of the signal may contain generation artifacts.
- Vocoder fingerprints: The component that converts model output into an audio waveform may leave recurring signatures.
- Temporal consistency: Features may change unnaturally across consecutive audio segments.
- Prosody: Rhythm, stress, pitch, intonation, and pauses may differ statistically from authentic speech.
- Breathing and mouth sounds: Natural non-speech events may be missing, duplicated, or inconsistent.
- Background continuity: Room tone or environmental noise may change unexpectedly.
- Replay signals: Audio played through a speaker and recorded again contains acoustic and device characteristics absent from the original file.
- Codec behavior: Telephone, conferencing, streaming, and social-media compression can alter useful detection signals.
- Partial manipulation: Only selected words or portions of a recording may have been synthesized.
A person may hear natural-sounding speech while a detector identifies patterns in the frequency or timing data. The reverse can also happen: authentic but compressed, noisy, or unusual speech may trigger an incorrect result.
What a Current Independent Audio Benchmark Shows
Podonos updated its 2026 audio deepfake detection benchmark, evaluating 23 detection systems against 4,524 audio clips balanced evenly between authentic and synthetic audio.
The benchmark included:
- 23 detection systems from commercial vendors and open-weight model developers
- Six audio formats: MP3, WAV, FLAC, OGG, M4A, and WebM
- Authentic audio from VCTK, LJSpeech, and LibriTTS-360
- Private ground-truth labels to help reduce benchmark tuning
Resemble AI’s DETECT-World achieved 99.47% accuracy, with a 0.4% false-negative rate and a 0.7% false-positive rate in the latest evaluation.
How Multimodal AI Detection Combines Evidence
Multimodal detection examines more than one media type within the same file or workflow.
For example, a video-verification system may analyze:
- Whether the face contains generative artifacts
- Whether the voice contains synthetic speech signals
- Whether lip movements match the spoken audio
- Whether the same identity remains consistent
- Whether the file contains valid provenance
- Whether portions of the media appear elsewhere online
- Whether the content was replayed or injected
- Whether the person appears physically present
A coordinated deepfake may combine authentic background footage, an altered face, synthetic speech, and fabricated identity documents. Running unrelated detectors independently may miss the relationship between those elements.
Multimodal detection is therefore particularly relevant toidentity verification and KYC, live meetings, remote recruitment, financial approvals, and evidence review.
Which AI Detection Techniques Are Used?
AI detectors use different approaches depending on the content type and deployment goal.
Detection estimates whether content contains synthetic patterns. Watermarking checks for a deliberately embedded signal. Provenance validates statements about origin and editing history.
How Accurate Are AI Detectors?
There is no responsible single-number answer.
Accuracy depends on:
- The detector being used
- The content modality
- The generating model
- Whether that generator appeared in training data
- The language or subject domain
- Sample length
- Audio and image quality
- Compression and editing
- Class balance
- The decision threshold
- The benchmark dataset
- Whether the test is in-domain or out-of-distribution
- Whether the content is entirely synthetic or partly edited
A detector can achieve strong results on one benchmark while failing against a new generator, language, codec, or platform transformation.
Current Research Snapshot
Why Accuracy Alone Can Be Misleading
Overall accuracy is the percentage of correct classifications. It can hide how the detector makes mistakes.
Imagine that only 1% of submitted files are synthetic. A detector that labels every file authentic would achieve 99% accuracy while catching none of the synthetic content.
Organizations should therefore examine more than one metric.
NIST’s text-discriminator evaluation uses metrics including AUC, equal error rate, true-positive rate at a defined false-positive rate, and Bayes risk. This reflects why standardized evaluations do not rely on overall accuracy alone.
Why Can AI Detector Results Be Wrong?
False positives occur when authentic content is classified as synthetic. False negatives occur when generated or manipulated content is classified as authentic.
Several conditions can cause these errors.
The Generator Was Not Represented in Training
A detector may recognize familiar generator families but miss artifacts from a new or substantially different system.
This is the generalization problem: the detector learned its development environment without learning features that transfer reliably to future content.
The Content Was Transformed
Cropping, paraphrasing, translation, compression, filtering, resampling, transcription, screenshots, screen recording, and re-recording can alter the evidence a detector expects.
Many transformations are routine rather than malicious. Social networks, conferencing systems, and messaging apps automatically process uploaded content.
The Sample Is Too Short
A short paragraph, one-second audio clip, low-resolution image, or isolated video frame may not contain enough evidence for a stable result.
Google DeepMind notes that its text watermarking method works better with longer, varied responses because short factual answers provide fewer opportunities to embed a detectable pattern.
Human and AI Contributions Are Mixed
A person may revise an AI draft extensively. A real photograph may contain one generated region. A video may use authentic visuals with synthetic audio.
A binary “human or AI” label may not describe these mixed cases accurately. Segment-level or region-level analysis is more useful.
The Threshold Does Not Match the Risk
Lowering a threshold may catch more synthetic content while increasing false positives.
Raising it may reduce false alerts while allowing more manipulated content through.
There is no universally correct threshold. The appropriate setting depends on the cost of each error.
The Benchmark Is Not Representative
A detector evaluated on clean English essays may behave differently on student work, legal writing, social posts, or translated content.
An audio detector evaluated on studio recordings may behave differently with telephone codecs, noisy calls, or replayed audio.
The Detector Relies on a Fragile Signal
A watermark detector may fail when the watermark is damaged. A fingerprint detector may fail against a new model. A forensic detector may confuse compression with manipulation.
This is why layered verification is more reliable than dependence on one signal.
How to Evaluate an AI Detector Before Deployment
Organizations should evaluate a detector as part of a risk-control workflow, not as a standalone percentage.
1. Define the Decision It Will Support
Clarify what happens after a file is flagged.
Possible actions include:
- Sending content to a reviewer
- Requesting another identity factor
- Pausing a payment
- Escalating a meeting alert
- Rejecting an uploaded file
- Labeling public content
- Opening a fraud investigation
The higher the consequence, the stronger the evidence and review process should be.
2. Build a Representative Test Set
Testing data should reflect production conditions, including:
- Relevant languages
- Real user populations
- File formats
- Devices
- Microphones and cameras
- Codecs
- Background noise
- Compression levels
- Content lengths
- Known generators
- Unfamiliar generators
- Mixed human and AI content
- Partially manipulated media
- Routine platform transformations
Vendor demonstrations are not a substitute for representative testing.
3. Measure Both Types of Error
Decide whether false positives or false negatives are more expensive. For example:
4. Test New and Transformed Content
- Cropping
- Resizing
- Noise