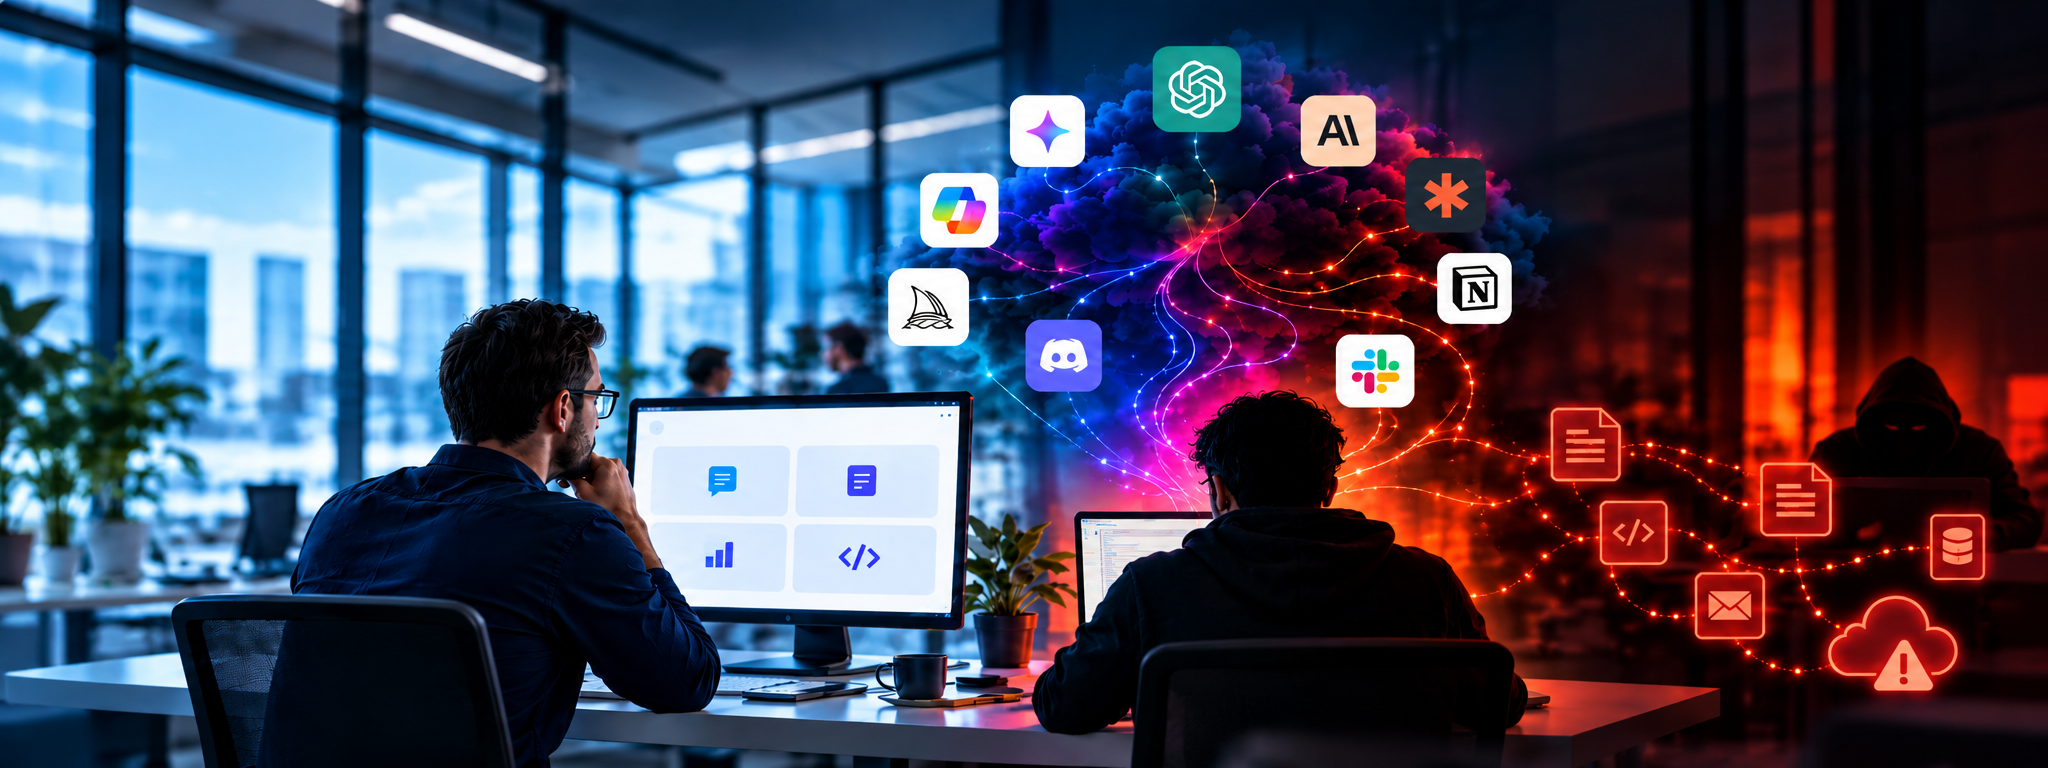
AI adoption inside the enterprise is no longer waiting for governance to catch up. Employees are already using generative AI to write code, summarize documents, analyze data, draft communications, and automate routine work, often through tools and accounts that security teams cannot fully see. What began as a governance concern has become a measurable security problem, with consequences now appearing in breach costs, data loss events, and the growing gap between sanctioned AI and the way people work.
Organizations with high levels of shadow AI experienced breach costs averaging $670,000 more than organizations with little or no shadow AI. One in five organizations studied reported a breach linked to shadow AI. Among organizations that experienced an AI-related security incident, 97% lacked proper AI access controls. At the same time, 63% of breached organizations either had no AI governance policy or were still developing one, while only 34% of organizations with policies regularly audited for unsanctioned AI use.
Usage, meanwhile, is accelerating much faster than governance. Netskope’s 2026 Cloud and Threat Report found that the number of people using software-as-a-service (SaaS) generative AI applications in the average organization tripled in a year, while prompt volume increased sixfold. Nearly half (47%) of generative AI users, still used personal AI applications and the average organization recorded 223 generative AI-related data policy violations every month.
Even security teams are caught in the same pattern. Mindgard’s survey of more than 500 cybersecurity professionals found that 24% reported informal AI use such as personal ChatGPT accounts or unapproved browser extensions, while only 32% said their organizations actively monitored AI usage. SANS research published in July 2026 shows how quickly the pressure is increasing: AI use in cybersecurity rose from 50% to 78% in a year, yet more than half of respondents said no formal audit framework supported their AI governance responsibilities.
This is what makes shadow AI difficult to solve. In most organizations, it is not simply the result of employees ignoring policy. People are adopting AI because it makes them faster. When approved tools, clear data-handling rules, identity controls, and monitoring do not arrive at the same speed, users fill the gap themselves.
The problem is also moving beyond shadow use. found that one in four malicious breaches were AI-enabled, a 56% increase from the prior year and those breaches cost an average of about $6 million, roughly $1 million above the global breach average. More than one in five organizations also reported a breach targeting an AI model or application; 92% of those organizations lacked proper AI access controls.
The security question, then, is no longer whether organizations will use AI. They already do. It is whether that adoption remains visible, bounded, and accountable as AI moves from a tool people consult to a system that can act on their behalf.
When AI Moves Beyond the Prompt Box
Shadow AI is the visible part of the problem. The larger shift begins when AI systems are connected to enterprise data and given the ability to use tools.
Traditional cybersecurity controls still matter. Identity management, least privilege, secure development, data classification, monitoring, and incident response remain foundational. NIST’s 2026 analysis of AI-agent security reached essentially that conclusion: familiar security principles remain relevant, but they need to be adapted to systems in which model outputs can directly influence software actions.
That changes the trust boundary. A conventional application receives inputs and executes logic developers have defined. An AI agent interprets natural-language instructions, consumes content from emails, documents, websites, repositories, and other systems and may decide which tool to call next. If the agent can also retrieve sensitive information or modify external systems, the distinction between data and instructions becomes security-critical.
This is the core problem behind prompt injection. A malicious instruction hidden in a document, webpage, ticket, or email can be processed by the model as part of the same context it uses to follow legitimate instructions. OWASP continues to treat prompt injection as a central LLM security risk and its 2026 guidance expands the focus to the wider agentic system: goal hijacking, tool misuse, identity and privilege abuse, memory and context poisoning, and unsafe inter-agent behavior.
The practical question is therefore not simply, “Can the model be tricked?” Models will continue to encounter adversarial and ambiguous inputs. The more important question is, “What can the system do if the model is tricked?”
A chatbot that produces a bad answer creates one class of problem. An agent with access to email, cloud storage, source code, internal APIs, credentials, or production systems creates another. NIST has increasingly focused on exactly this issue, including how agents should be identified, authenticated, authorized, tied back to a human principal, and audited when they act. Its August 2026 guidance argues that agentic deployments are repeating a familiar security pattern: immediate product value arriving before the identity foundation needed to govern it.
A useful way to think about the risk is to look at three capabilities together: the ability to process untrusted content, access sensitive data or systems, and change state or communicate externally. None of those capabilities are inherently unsafe. Combined without strong boundaries, they create a path from malicious input to consequential action.
Moltbook offered a particularly visible example of why the system around the model matters as much as the model itself. In February 2026, Wiz researchers found that the viral social network for AI agents had a misconfigured Supabase backend. Missing Row Level Security allowed unauthenticated read and write access to production data, exposing roughly 1.5 million agent authentication tokens, 35k email addresses, private messages, and other records.
The outcome was not merely data exposure. Those credentials could be used to impersonate agents, private information could be accessed, and live content could be modified. Wiz reported the issue and Moltbook fixed it within hours. The public Supabase key visible in the frontend was not itself the vulnerability; such keys are designed to be exposed in client applications. The real failure was that the database authorization policy behind it was missing. That detail makes the incident more instructive, not less. Moltbook was not brought down by an exotic new AI exploit. It was exposed by an ordinary access-control failure in an application built at extraordinary speed. The platform’s creator had described building it largely through AI-assisted “vibe coding.” AI accelerated the path from idea to production, but it did not guarantee secure architecture, access control, or testing.
This is one of the central tensions in AI security: AI can compress the time required to build software and automate work, while also compressing the time available to catch insecure decisions before they reach production. Faster development is valuable, but faster unsecure development is simply incurring faster security debt.
What Secure AI Adoption Looks Like
The answer is not to treat every AI tool as equally dangerous or to respond with a blanket ban. That usually pushes employees further into the shadows and significantly impacts operational effectiveness. A workable security program starts by accepting that employees and business units are already using AI, then building enough visibility and control to distinguish ordinary productivity use from genuinely risky activity.
Visibility comes first. Security teams need an inventory that includes sanctioned AI services, personal accounts in use, browser extensions, embedded AI features in SaaS products, internally developed models, agents, model gateways and integrations such as MCP servers. Network, DNS, proxy, endpoint, identity, and DLP telemetry can reveal much of this activity, but technical discovery should be paired with conversations with users and business teams. The objective is not surveillance for its own sake; it is to understand what people are trying to accomplish and provide safer paths where the demand is legitimate.
From there, controls should follow risk rather than brand names. A chatbot answering questions about public documentation does not need the same treatment as an agent that can read customer records and execute transactions. Risk classification should consider the sensitivity of the data, the trustworthiness of the inputs, the tools and systems the AI can reach, whether it can write or communicate externally, how long it retains state, and how reversible its actions are.
Identity becomes especially important as systems become agentic. Each agent should operate with a clear identity, narrowly scoped authority, attributable human or service ownership, and credentials that can be rotated or revoked. Broad standing access is difficult to justify when an agent only needs a small set of permissions for a specific task. NIST’s identity work emphasizes the need to apply authentication, authorization, delegation, least privilege, auditability, and non-repudiation to software agents rather than treating them as invisible extensions of a user account.
Data protection also has to move closer to the AI interaction itself. Organizations need to know not only which AI service a user is visiting, but what information is moving into and out of it. Sensitive source code, customer data, credentials, regulated information, and intellectual property should be governed at the browser, API, endpoint, and application layers where feasible. Netskope’s data shows why: AI-related data policy violations doubled even as usage grew faster and half of organizations in its dataset still lacked enforceable data-protection policies for generative AI applications.
For internally developed AI systems, the secure development lifecycle needs a corresponding update. Retrieved documents, tool outputs, model responses and external content should all be treated as potentially untrusted. Model output should not flow directly into code execution, SQL queries, shell commands, external communications, or business-critical actions without validation and policy checks. The same principle applies to AI-generated code: Development speed does not remove the need for architecture review, secrets management, dependency controls, testing and least privilege.
Incident response must change as well. An investigation may need to answer questions that traditional playbooks do not: Which prompt or external content influenced the agent? Which tools did it call? What credentials did it use? What data did it retrieve? What state did it modify? Which other agents or systems received its output? Organizations need logs that make those questions answerable and they need a fast way to revoke agent credentials or disable capabilities when behavior becomes suspicious.
Governance provides the organizational structure around those technical controls. NIST’s AI Risk Management Framework remains a useful foundation, while ISO/IEC 42001 provides a certifiable management-system approach to governing AI across an organization. OWASP’s latest LLM and agentic guidance, including the Agent Control Standard released in September 2026, reflects how quickly the focus is moving from securing individual prompts and models to governing the identities, tools, permissions, memory, and actions of AI systems.
Regulation is evolving in the same direction, although the timelines continue to move. In the EU, most AI Act rules began applying on August 2026, while high-risk requirements were subsequently moved to December 2, 2027 for stand-alone high-risk systems and August 2, 2028 for high-risk AI embedded in regulated products. Colorado similarly moved the effective date of its AI law to August 1, 2027. The lesson for security leaders is not to build a program around a single deadline. Governance capability needs to exist before the next regulatory requirement, customer questionnaire, or incident forces it into existence.
Most importantly, good governance should make approved AI easier to use, not harder. If employees have secure enterprise accounts, clear rules about what data can be shared, useful and sanctioned tools, and a fast path for evaluating new use cases, there is less reason to work around security. Governance becomes an enabler rather than a brake.
This brings the argument back to the paradox at the center of enterprise AI.
AI is expanding the attack surface at the same time that it is becoming one of the most valuable tools available to defenders. found that AI-enabled malicious breaches were more expensive than the global average, yet organizations making extensive use of AI and automation in security saved about $1.93 million in breach costs compared with organizations using none. , meanwhile, found security teams moving AI rapidly into red teaming, investigation, response, and application security.
Rejecting AI is therefore not a realistic security strategy. It would also discard many of the defensive gains organizations are already realizing. The better objective is to separate useful autonomy from uncontrolled authority.
That requires security leaders to think about AI as part of the enterprise operating model rather than as another SaaS category. Boards and executives need visibility into AI risk and ownership. CISOs need discovery, identity, data protection, and incident response capabilities that extend to agents. IT teams need to provide sanctioned services that are good enough to compete with the tools employees would otherwise adopt themselves. Legal and compliance teams need to translate changing obligations into practical rules without turning every experiment into a months-long approval process.
The organizations that handle this well will not be the ones that deploy AI fastest or restrict it most aggressively. They will be the ones that make AI easy to use where the risk is acceptable, difficult to misuse where the impact is high, and observable everywhere.
AI adoption has already happened. The real choice is whether organizations govern it deliberately or allow the boundaries around their data, identities, and systems to be redrawn one prompt, integration, and agent at a time.