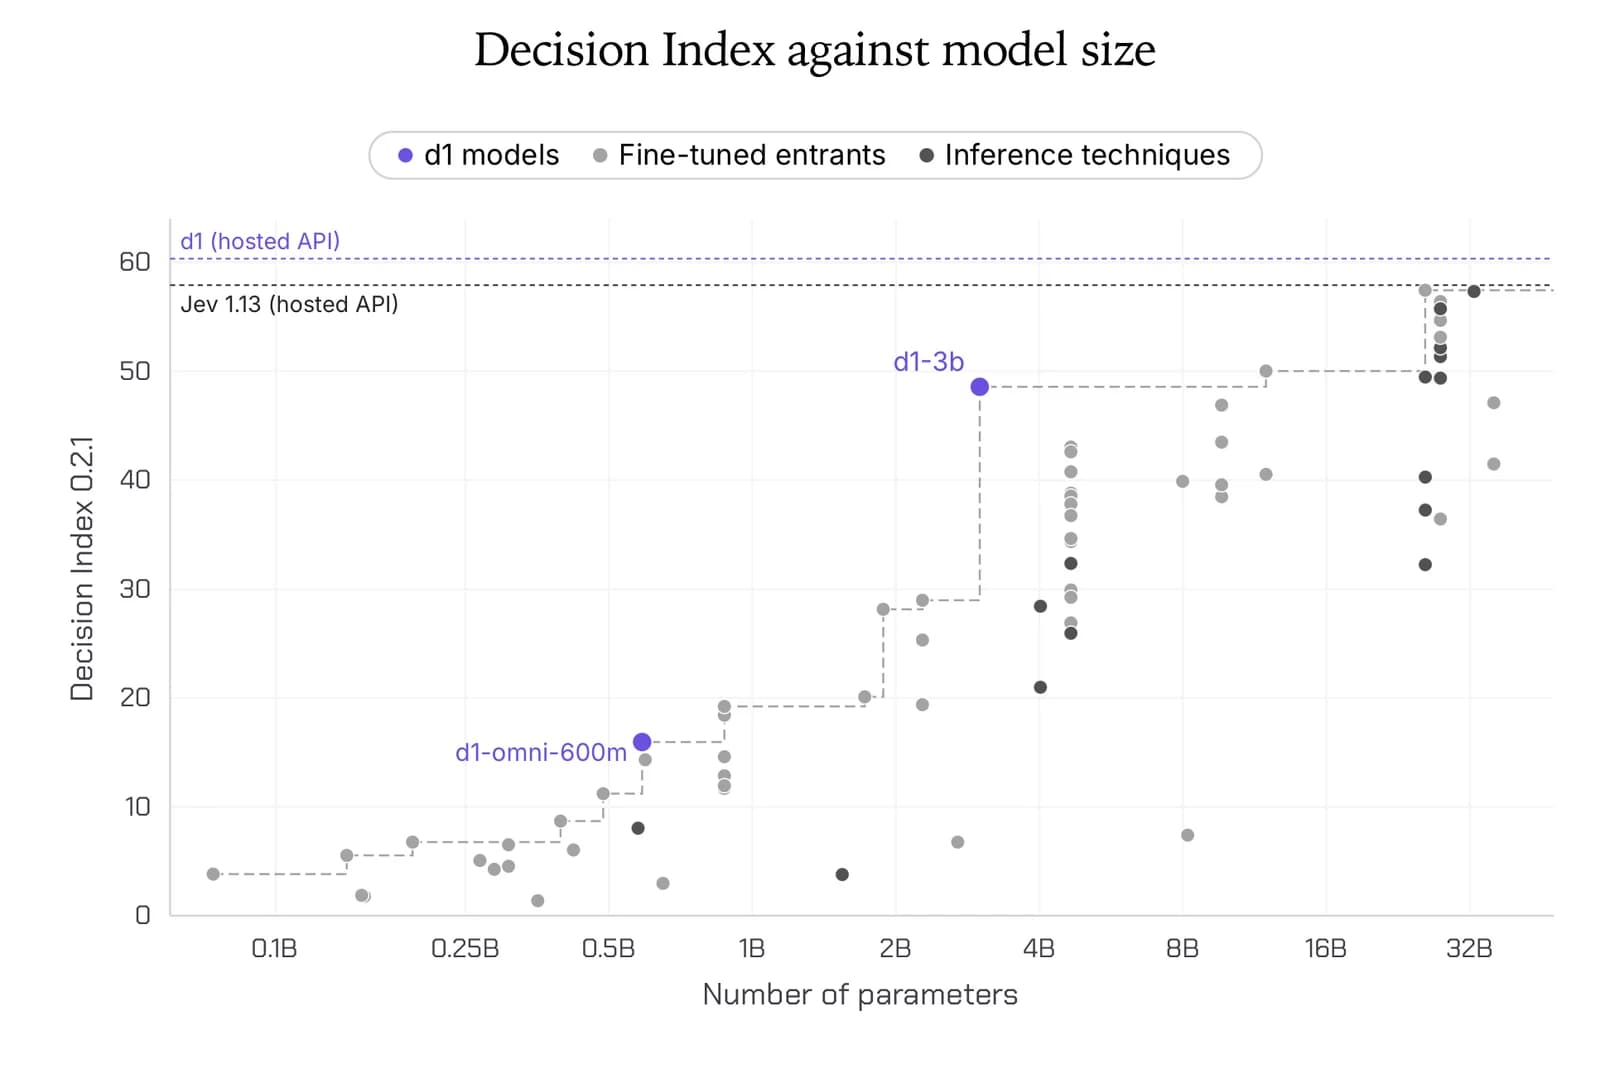
Today, we release two open decision models in our d1 decision model family: d1-3B and d1-omni-600M (experimental).
- Best decision model under 10B on the Decision Index 0.2.1: d1-3B scores 48.57, ahead of every 4B and 9B model and of Decider 35B-A3B (47.11).
- Multimodal: d1-3B supports text and images, while d1-omni-600M supports text and images or text and audio
- Fast: d1-3B answers a question in 16 ms on an NVIDIA Jetson AGX Thor, 26 ms on a Jetson AGX Orin, and 50ms on a Jetson Orin Nano
How we built decision models for the edge
These open d1 decision models are built on our Liquid Foundation Models (LFMs). Unlike our generative models, decision models don’t produce tokens but answer in a single forward pass.
d1-3B and d1-omni-600M are trained from two very different backbones:
- d1-3B is trained from LFM2.5-VL-3B, our latest VLM, which is decoder-only. It accepts text and images as inputs.
- d1-omni-600M is trained from LFM2.5-Encoder-350M, a bidirectional encoder. It adds vision and audio encoders to handle all three modalities. It accepts either text and image, or text and audio as inputs. This model is currently in an early research release and is undergoing further development.
Benchmark results
We benchmarked d1-3B and d1-omni-600M on seven public datasets spanning reading comprehension, toxicity detection, intent classification, medical QA, and cross-lingual understanding. d1-3B achieves a mean score of 82.9, the highest in the table and above Decider 4B. d1-omni-600M scores 78.4, surpassing Decider 2B (77.1) with only a quarter of the parameters.
We validated that d1-3B retains the vision capabilities of its LFM2.5-VL-3B backbone on standard vision benchmarks, and that d1-omni-600M handles all three modalities. We do not report any vision or audio benchmarks, as the Decision Index v0.3 includes only a private vision split and audio decision benchmarks are currently an open problem.
Speed
In collaboration with NVIDIA, we evaluated d1-3B on the NVIDIA stack across NVIDIA GeForce RTX 4090, NVIDIA Jetson AGX Thor, Jetson AGX Orin 64 GB, and Jetson Orin Nano. Since d1-omni-600M is an early research release, we don’t report any speed numbers for it in this release.
Edge inference. d1-3B answers a single question in under 50 ms on every measured device. Three questions take only 1.3x the time of one, with the AGX Thor going from 16 ms to 20 ms.
GPU inference. On GPU, d1-3B answers a question in under 10 ms and processes a 384px image in under 18 ms on both platforms.
How to use open d1 decision models
Reach for d1 decision models when you need fast, structured decisions, including multimodal inputs. d1-3B delivers the highest decision quality at its size, while d1-omni-600M fits where footprint matters.
Install the dependencies (requires transformers>=5.14):
These model ship their own code, so load it with trust_remote_code=True:
For brevity, we only include the example for d1-3B. See the d1-omni-600M model card for instructions on how to run it.
Get Started with open d1 decision models
Both decision models are open-weight and available on Hugging Face today:
- Download: d1-3B and d1-omni-600M on Hugging Face.
- Try: run the demos in our System One Arcade Hugging Face Space.
We can't wait to see what you build.
Citation
If you use this work, please cite the release blog: