Dev48
Language
  • About
  • Services
  • Industries
  • Technologies
  • Articles
  • Contacts
Book a call
    Home/Articles/Expanding our enterprise inference capacity with ibm cloud and nvidia
Dev48
info@dev48.org+375 29 320-40-96WhatsApp@isky_by

© 2026 · All rights reserved.

Expanding our enterprise inference capacity with IBM Cloud and NVIDIA

Source: Together AI•October 6, 2026 at 08:30 PM

Expanding our enterprise inference capacity with IBM Cloud and NVIDIA

Enterprises can now run open models at production scale on a dedicated B300 inference cluster, built by Together AI, IBM Cloud, and NVIDIA

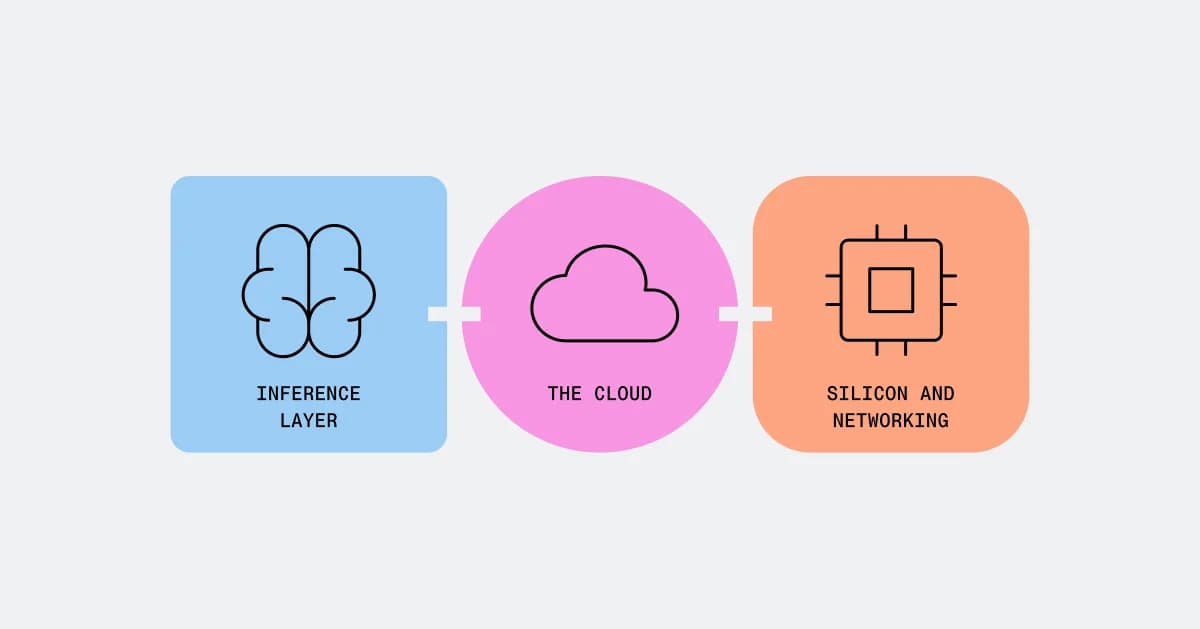
We’re excited to share that Together AI is working with IBM and NVIDIA to scale enterprise-grade AI inference, starting with a large cluster of NVIDIA B300 GPUs on IBM Cloud backed by NVIDIA Spectrum-X Ethernet networking. It's the first dedicated, large-scale inference cluster of its kind on IBM Cloud, and we're the first customer running on it.

What's actually happening

  • The infrastructure: A dedicated NVIDIA B300 GPU cluster, purpose-built for inference, running on IBM Cloud.
  • The model: We operate the inference layer, IBM provides the cloud, NVIDIA delivers the silicon and networking.
  • The trajectory: We're planning for the future as token demand goes parabolic

Why it matters

We started Together AI because we believe the future of AI shouldn't be owned by a handful of closed labs. That bet is paying off faster than even we expected: Hundreds of trillions of tokens served per month to over a million developers, and demand keeps climbing.

Enterprises and AI-native companies choose open models for two simple reasons: their sovereign data stays theirs and they get frontier-level performance at a fraction of closed-model cost. The bigger the usage, the better that math looks.

With this collaboration:

  • NVIDIA brings the silicon — B300 GPUs and Spectrum-X Ethernet networking engineered for high-throughput inference.
  • IBM brings decades of running mission-critical infrastructure for the world's largest enterprises.
  • Together AI brings the inference platform — the fastest, most efficient way to run open models in production, hardened by some of the most demanding AI workloads on the planet.

Put those together and the result is simple: enterprise-grade inference at massive scale – more production grade tokens, with the reliability, security and guardrails enterprises have come to expect.

Open-source AI has to run everywhere, at scale, as fast and reliably as anything closed. We have spent the last few years making sure it can and this collaboration is a big step toward exactly that.
← All articles

What this article says

More in AI & Machine Learning

All →
Data Processing Incidents on Inference Providers
OpenRouter

Data Processing Incidents on Inference Providers

Orchestrator: One API for frontier and open-weight models
Perplexity

Orchestrator: One API for frontier and open-weight models

Gemini 4 Hydrogen: What xhigh Buys for 6x the Bill
OrcaRouter

Gemini 4 Hydrogen: What xhigh Buys for 6x the Bill

Gemini 4 Neon Video: An Artifact Export, Not a Generation
OrcaRouter

Gemini 4 Neon Video: An Artifact Export, Not a Generation

Security event: Prompt leakage for requests in June and July of 2026
Together AI

Security event: Prompt leakage for requests in June and July of 2026

Qwen4 Max is live on Together AI
Together AI

Qwen4 Max is live on Together AI

More from Together AI

Security event: Prompt leakage for requests in June and July of 2026
Together AI

Security event: Prompt leakage for requests in June and July of 2026

Qwen4 Max is live on Together AI
Together AI

Qwen4 Max is live on Together AI

Qwen3 TTS is now available on Together AI
Together AI

Qwen3 TTS is now available on Together AI

Tencent Hy4 is live on Together AI
Together AI

Tencent Hy4 is live on Together AI

Introducing Together Storage Accelerator: fast, free data caching for your GPU cluster
Together AI

Introducing Together Storage Accelerator: fast, free data caching for your GPU cluster

Last year we built megakernels. This year we deleted them: The road to Together Compiler
Together AI

Last year we built megakernels. This year we deleted them: The road to Together Compiler