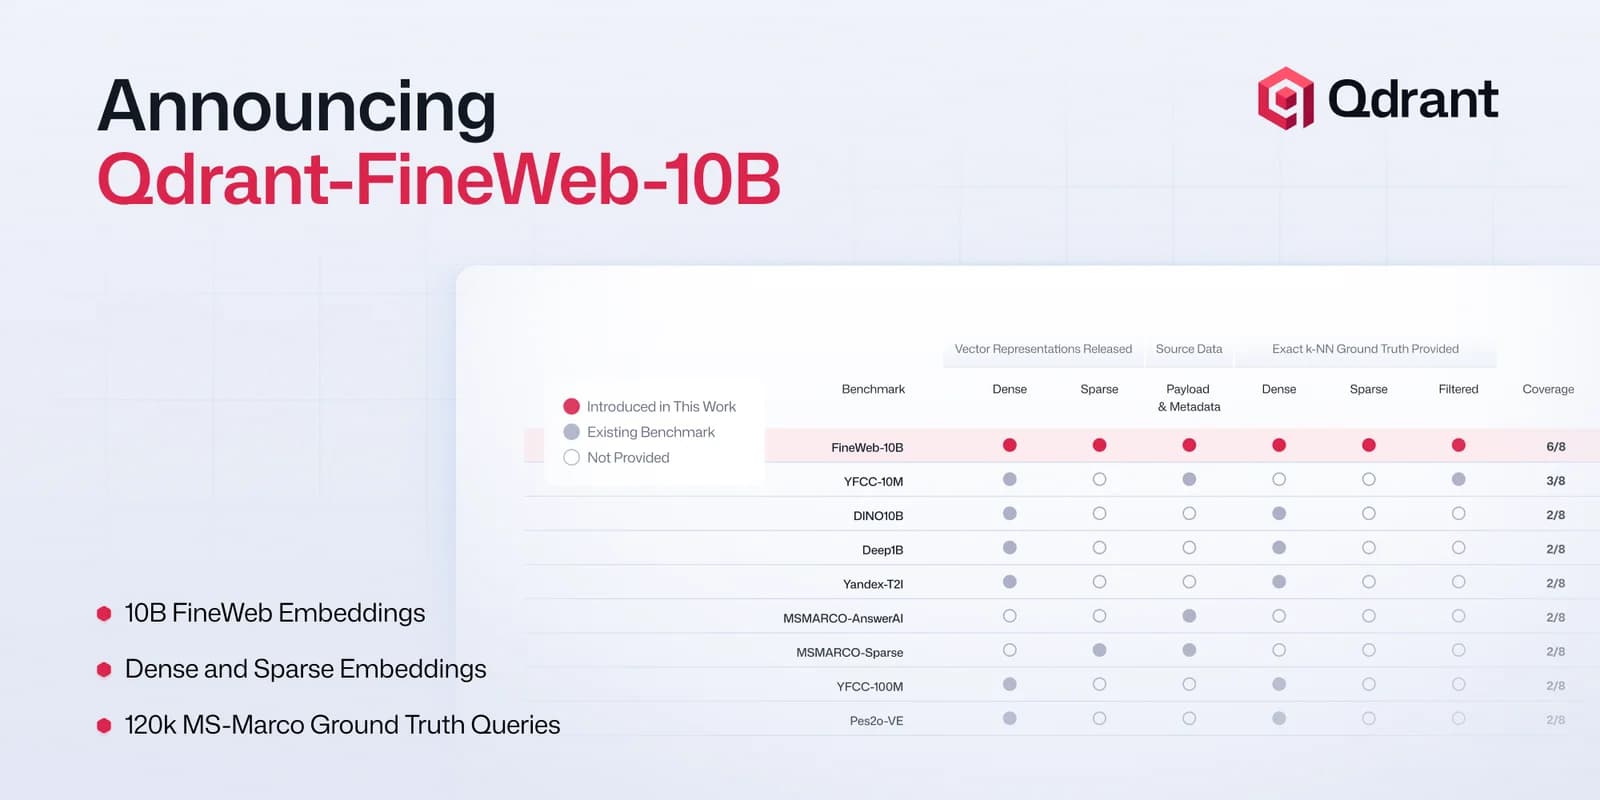
Real world vector search workloads are increasingly large and complex. Enterprises are not using vector search to occasionally search through a couple of PDF files. They are indexing and searching billions of vectors at thousands of requests per second (RPS) and sub 50ms tail latency. Large enterprises also can’t tolerate faulty assumptions.
Too many benchmarks use gated, proprietary managed services. And even worse, the data is synthetic, the queries are hidden, and the engines are locked behind paywalls.
These benchmarks show a 90% recall @ 10 on a purely synthetic RAG benchmark for a production claim. But for an e-commerce or marketplace company feeding top 1000+ results into a second-stage reranker, it’s not good enough. Engineers within the world’s leading search teams demand reproducibility, 95%+ recall, large retrieval depth, high throughput, and sub 100-ms p99 latency. And so do we.
Why hasn’t this problem already been solved? Because generating benchmark datasets at billion-scale is incredibly challenging, and calculating exact ground truth queries requires vast compute and potentially quadrillions of brute-force distance computations.
But we like hard problems. So we went after it.
In partnership with Vultr, we absorbed the economics of extreme-scale embedding generation and brute-force KNN to provide the scientific and engineering communities with a new standard of search benchmarking datasets: Qdrant-FineWeb-10B.
This behemoth of a dataset contains ~25 TiB of vector data alone, consisting of dense and sparse vectors generated from gte-multilingual-base. Then, using our GPU-native benchmarking engine, we computed the exact top-1000 ground truth for 120,000 dense, sparse, and filtered queries - over a quadrillion distance computations across the full 10B document corpus.
Because the industry currently lacks datasets that translate well to multimodal formats and complex filtering, we are also releasing PubMed-Multi-Vector and Coyo-Vector-Embeddings. These datasets provide the community with the dense, sparse, and multimodal representations that actually reflect modern production architectures.
To ensure these datasets aren’t just another proprietary vendor claim, we are open-sourcing the tooling that we used. Supernova is our high-performance, distributed benchmarking framework designed to make massive-scale dataset generation and brute-force ground-truthing accessible, reproducible and even more cost-effective.
The era of relying on 1-million vector datasets, production hearsay, and synthetic approximations is over. Here is the real data, the real ground truth, and the open-source infrastructure you need to run it yourself.
Qdrant-FineWeb-10B: Benchmarking at Internet Scale
Qdrant-FineWeb-10B represents the core of this release. It is the largest open-source vector search benchmark available to the community, comprising 24.47 TB of vectors and 28.66 TB of source text and metadata.
Created in collaboration with Vultr using gte-multilingual-base on Hugging Face’s FineWeb corpus, we utilized Supernova to compute exact top-1000 brute-force ground-truth nearest neighbors for 100,000 queries across the entire 10-billion vector space. Taken together, this amounted to over one quadrillion distance calculations run in parallel on GPU-accelerated hardware.
To showcase Supernova’s versatility across modalities and provide further assets to the community, we used Supernova to generate two additional open datasets:
- PubMed-Multi-Vector: Designed to benchmark hybrid retrieval methods with corpus variables held constant. It generates dense, sparse, and ColBERT-style multi-vector representations over the exact same text corpus, accumulating over 8.37 billion multi-vector tokens across nearly 35 TB of data.
- Coyo-Vector-Embedding: Focuses on multimodal retrieval, leveraging a 2048-dimensional vision-language encoder (Qwen3-VL-Embedding-2B) to project image-caption pairs from the LLaVA dataset into a unified shared embedding space. This represents a highly-modern workload that leverages state of the art embedding generation and model architectures.
We plan to continue to release more datasets for the community.
Supernova: The Open-Source Benchmarking Engine
We didn’t want to stop at releasing a static dataset. We built Supernova as a free, fully open-source framework so that the broader community can generate, manipulate, ground-truth, and benchmark internet-scale datasets on their own infrastructure, without relying on Qdrant or any third-party stack.
automates the four core phases of building and running a vector search benchmark: 1) embedding generation, 2) brute-force ground-truth calculation, 3) database loading, and 4) evaluation benchmarking.
Each phase is driven by a specialized module configured entirely via YAML files and designed for massively parallel execution:
- nova-embed (Modular Embedding Pipeline): Unifies disparate backends (SentenceTransformers, FastEmbed, OpenAI APIs) and storage systems (Hugging Face, S3, Cloudflare R2). It operates statelessly without a central database—each worker uses its rank and world size to partition input data independently, achieving linear scaling across cloud and HPC environments.
- nova-bf (GPU-Native Ground Truth): Computes exact brute-force top-$k$ nearest neighbors across dense, sparse, and multi-vector representations without running out of memory. It streams data partitions from remote storage, uses custom fused GPU kernels for late-interaction scoring, and evaluates filters early on the CPU to prune irrelevant rows before GPU transfer.
- nova-load & nova-storm (Ingestion & Stress Testing): Handle downstream evaluation across backends such as Qdrant, Milvus, and Elasticsearch. nova-load drives parallel ingestion to test write throughput, while nova-storm runs search workloads to track QPS, latency distributions ($p_{50}, p_{95}, p_{99}$), build times, and recall accuracy against nova-bf ground truth.
Overview of the Supernova framework: a standardized pipeline for vector search benchmarking. Each module is designed to scale linearly across cloud and HPC environments, enabling reproducible benchmarking at internet scale.
Distributed Compute with SkyPilot
To scale compute seamlessly across distributed infrastructure, Supernova integrates nova-dist, a controller-only module built on SkyPilot that handles cluster provisioning, job scheduling, fault tolerance, and cloud abstraction. Rather than hardcoding infrastructure logic into individual pipeline modules, nova-dist decouples job execution from hardware management. This allows nova-embed, nova-bf, nova-load, and nova-storm to scale linearly across AWS, GCP, Azure, Kubernetes, and Slurm HPC clusters using identical YAML configurations—massively parallelizing workloads across hundreds of GPUs without manual infrastructure overhead.
Acknowledgements
We extend our sincere thanks to Vultr for providing the raw compute infrastructure to generate the initial FineWeb-10B embeddings, as well as the SkyPilot and Hugging Face teams for building open-source foundation tools that enable operating at this scale.