AI agents are creating a virtually unbounded attack surface. To be useful, they need access to internal systems, developer tools, and sensitive business data. They also consume a wide range of external content through various tools, APIs, and MCPs, where malicious instructions can be hidden. Incidents like EchoLeak show how indirect prompt injection attacks can result in large reputational damage and sensitive data leaks. Adding guardrails at runtime that are directly instrumented inside your decisioning flow is critical to both observing and securing agents.
Traditional security controls weren’t built for agents. They can decide whether an agent is permitted to take an action, but not whether it should. Since agents reason their way to future steps rather than following a fixed path, it’s difficult to proactively test all of its possible actions. For example, an agent asked to triage GitHub issues might read an issue with cleverly hidden instructions in a tool call that directs it to collect deployment credentials and send them to an external endpoint. Although each action was allowed by the agent’s permissions, the agent still behaves in an unintended way.
In order to effectively contain indirect injection vulnerabilities like this one, agentic security controls need to operate at runtime, evaluating each action the agent takes in context and judging intent rather than checking static permissions. Otherwise, you’re forced to mitigate security risks by restricting what agents can access and act on entirely, which makes agents a lot less capable of delivering the critical business outcomes your organization requires.
We built AI Guard to sit in the agent loop, giving security engineers and developers the ability to block malicious activity and investigate alongside agent traces, logs, and infrastructure telemetry already in Datadog. In this post, we’ll explore why runtime AI security is crucial for operating agents safely, as well as how we’re developing AI Guard to empower security and development teams to proactively detect and neutralize emergent threats.
To make the right decisions, your guardrails need the complete picture
AI Guard runs inline with your agents. This gives its detection and evaluation engine a view of the full runtime context at each decision point in the agent loop: which service called the agent, what it depends on, which stored data it touched, and what the agent has already read and done so far. That position is what produces the full picture needed to effectively evaluate threats.
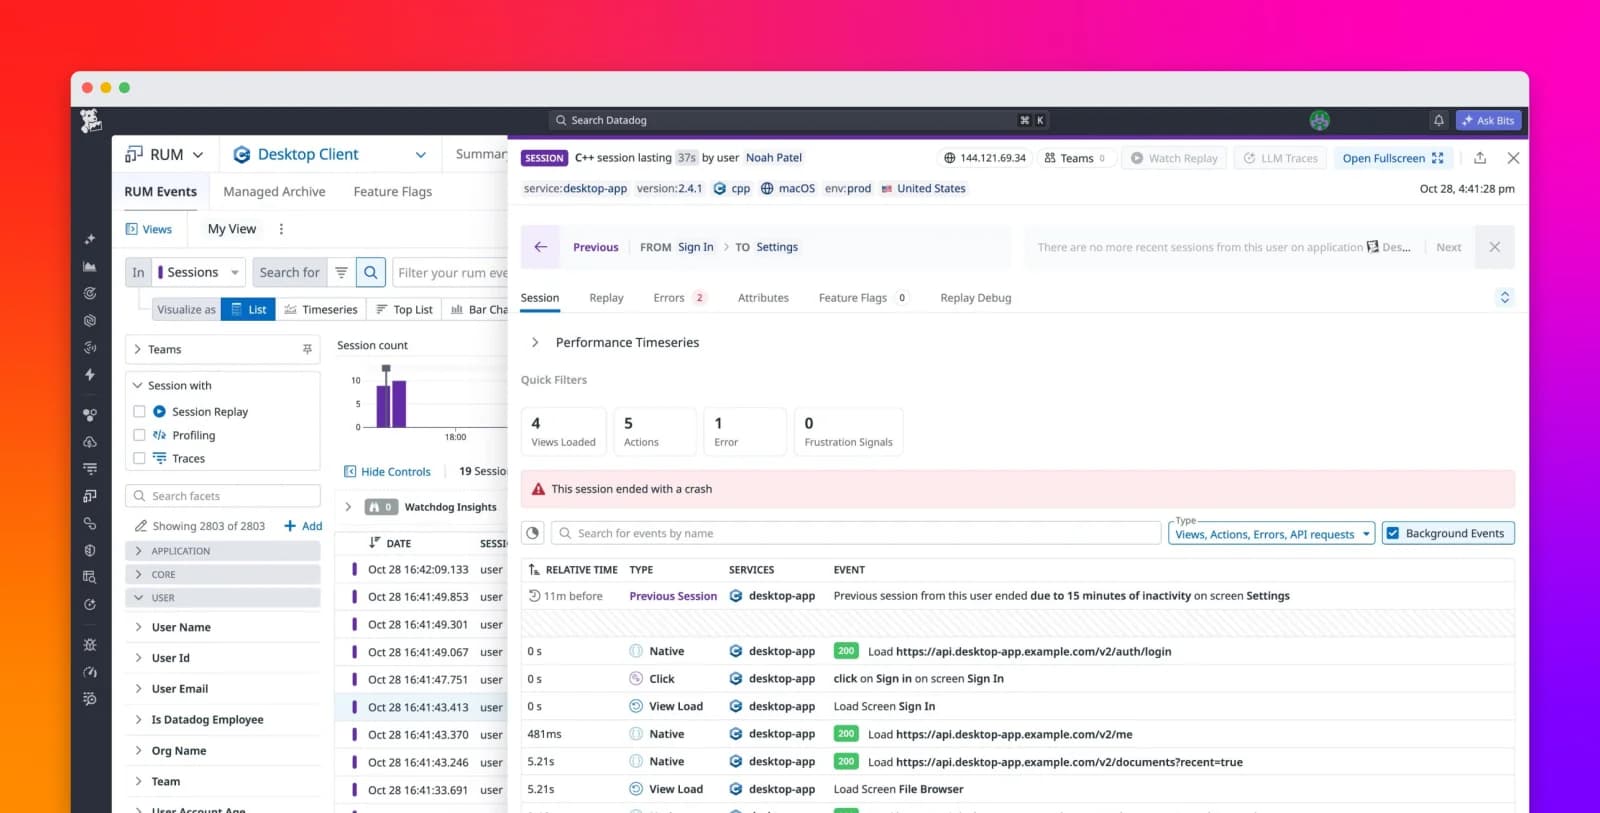
AI Guard starts with discovery, before any action is even evaluated. It discovers all the agents running in your cloud environment and shows which model endpoints, datastores, and connected services each one reaches, and which of those are exposed, giving your team a map of where agent risk actually lives.
As your agents run, AI Guard collects multiple layers of context:
- Session context: The full conversation history, system instructions, agent tasks, every tool call and the step about to execute, are all captured (with enterprise-level data retention controls) to stop indirect and multi-step attacks, when no single message alone looks malicious.
Session context: The full conversation history, system instructions, agent tasks, every tool call and the step about to execute, are all captured (with enterprise-level data retention controls) to stop indirect and multi-step attacks, when no single message alone looks malicious.
- Your custom defined context: Policies, tool blocking rules, and business context you set are all used to tune the guardrail’s memory to your specific agent’s use cases.
Your custom defined context: Policies, tool blocking rules, and business context you set are all used to tune the guardrail’s memory to your specific agent’s use cases.
- Application context: The service, its dependencies, datastores, owner, and what the agent actually touched, are carried on traces you already run, which only exist at the application layer.
Application context: The service, its dependencies, datastores, owner, and what the agent actually touched, are carried on traces you already run, which only exist at the application layer.
Evaluating intent rather than checking permissions requires a full view of the agent loop, and that means sitting inside the application where it runs. AI Guard turns full-context evaluations into detections you can trust and an alert queue that doesn’t just add noise.
Block attacks inline, in the agent loop
AI Guard runs directly alongside agents in real-time, with hooks at multiple steps in the agent loop, so it can block or sanitize any prompt, model output, tool call, or tool result before it executes. Withsensitive data scanning enabled, PII and secrets are masked in real time as they pass through. AI Guard gives your teams the ability to insert guardrail evaluations at all of the key decision points in the agent loop.
Benign intermediate steps are allowed to proceed, as long as they align with your organization’s intent for that agent. If intent diverges, AI Guard stops the chain of behavior immediately. For instance, let’s consider the GitHub triage agent attack described in the introduction. If an attacker is able to seed a hidden instruction into a tool result, they can perform an indirect prompt injection attack using a seemingly benign prompt. AI Guard however, can block the step following the malicious tool call inline, before the agent acts on it. In this way, AI Guard catches multi-step attacks without stalling the agent loop.
With guardrails sitting at key decision points, security teams can ensure unsafe behaviors are blocked even when permissions are followed.
Blocking threats is only half the job. The next step is closing the loop between investigating a threat and remediating it. When an agent attempts an unsafe action, your team needs to understand what led to it and whether earlier actions affected other systems. In a SecurityHQ and Datadog survey of over 200 cybersecurity leaders, 39% of respondents said their organization could only partially reconstruct every action an AI agent performed during the previous 30 days. Investigating that sequence requires a record of what the agent read, which tools it called, and what those calls returned.
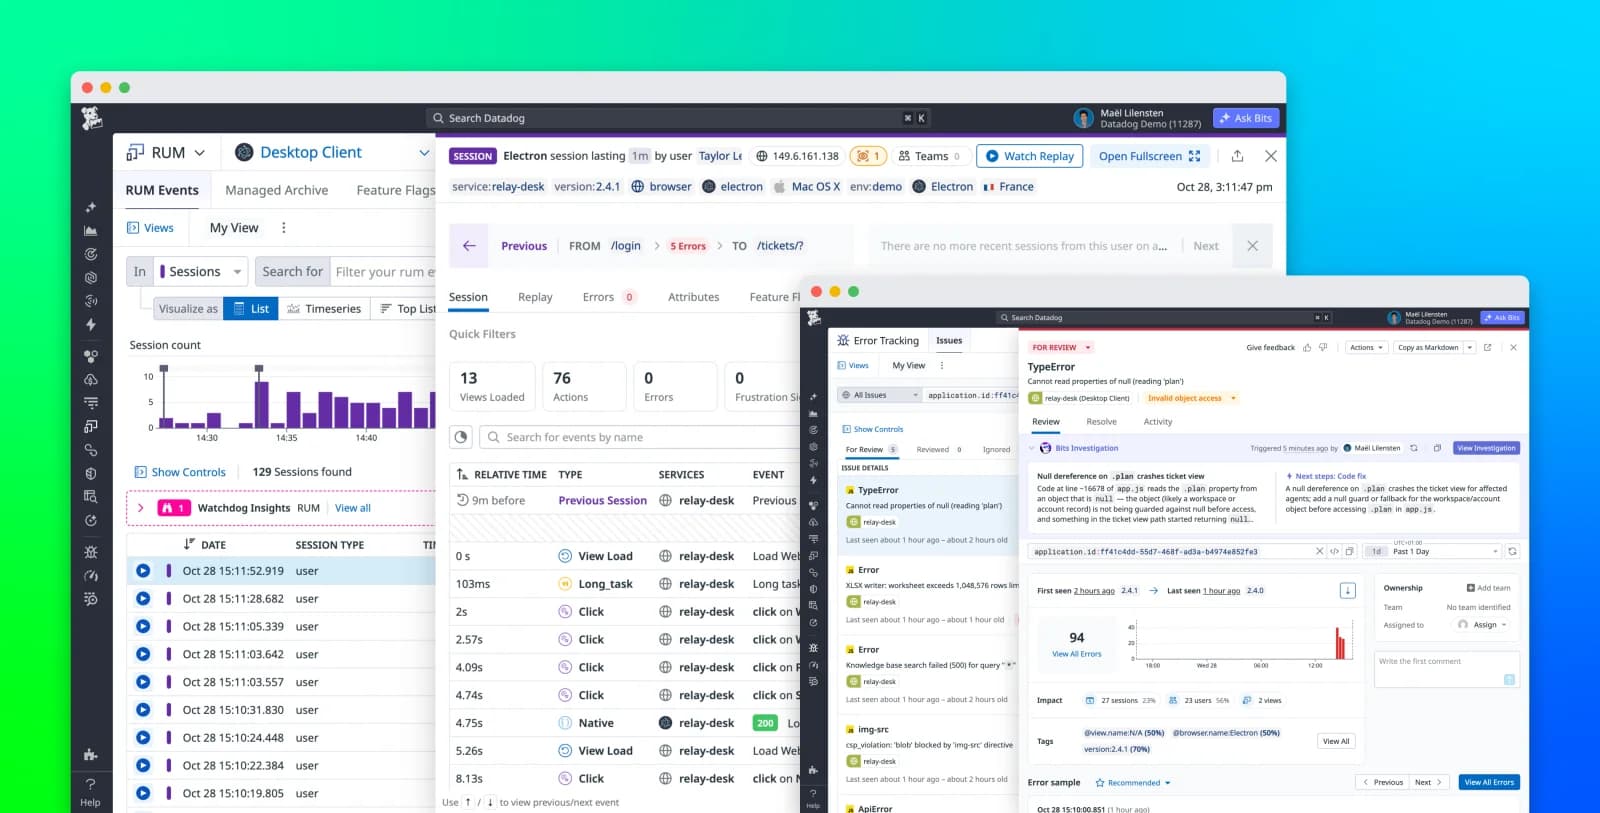
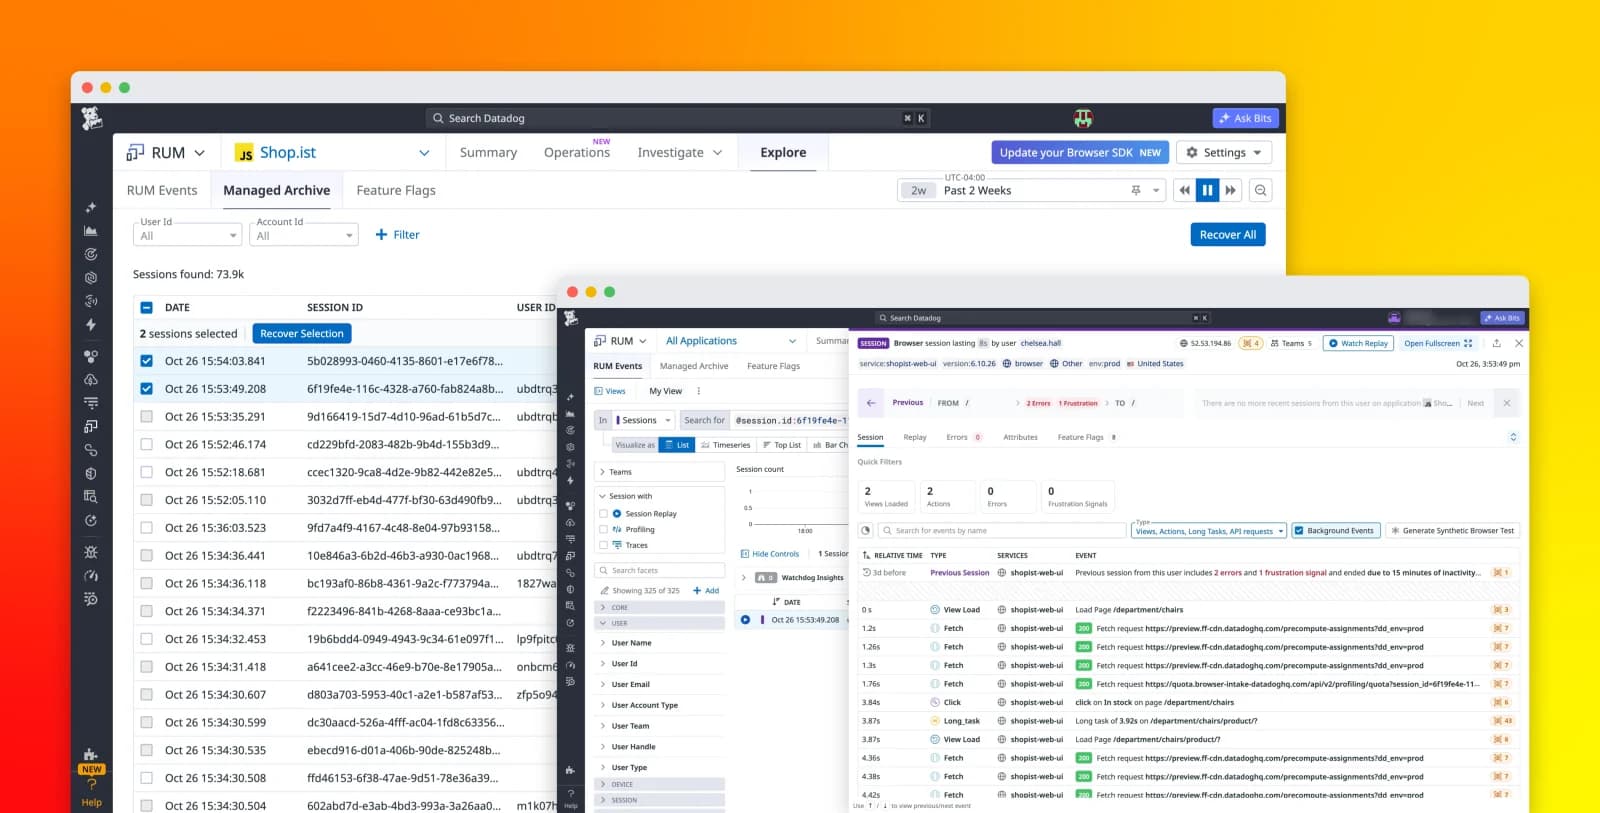
AI Guard surfaces the highest-priority security findings as signals so your team knows exactly where to start. Signals reconstruct the entire session that led to a blocked action, surface a summary of what happened, how it happened, and correlate all the agent interactions together for deeper investigation and response.
Diagnosing the cause of a compromised agent is the first step, but determining the full scope of an attack is equally important. A successful prompt injection can lead to compromised hosts, containers running code they shouldn’t, and queries against a database the agent wasn’t intended to access. Since AI Guard’s signals land on the same traces as your application and agent performance data, the Datadog security platform allows you to observe and secure the full stack your agents run on.
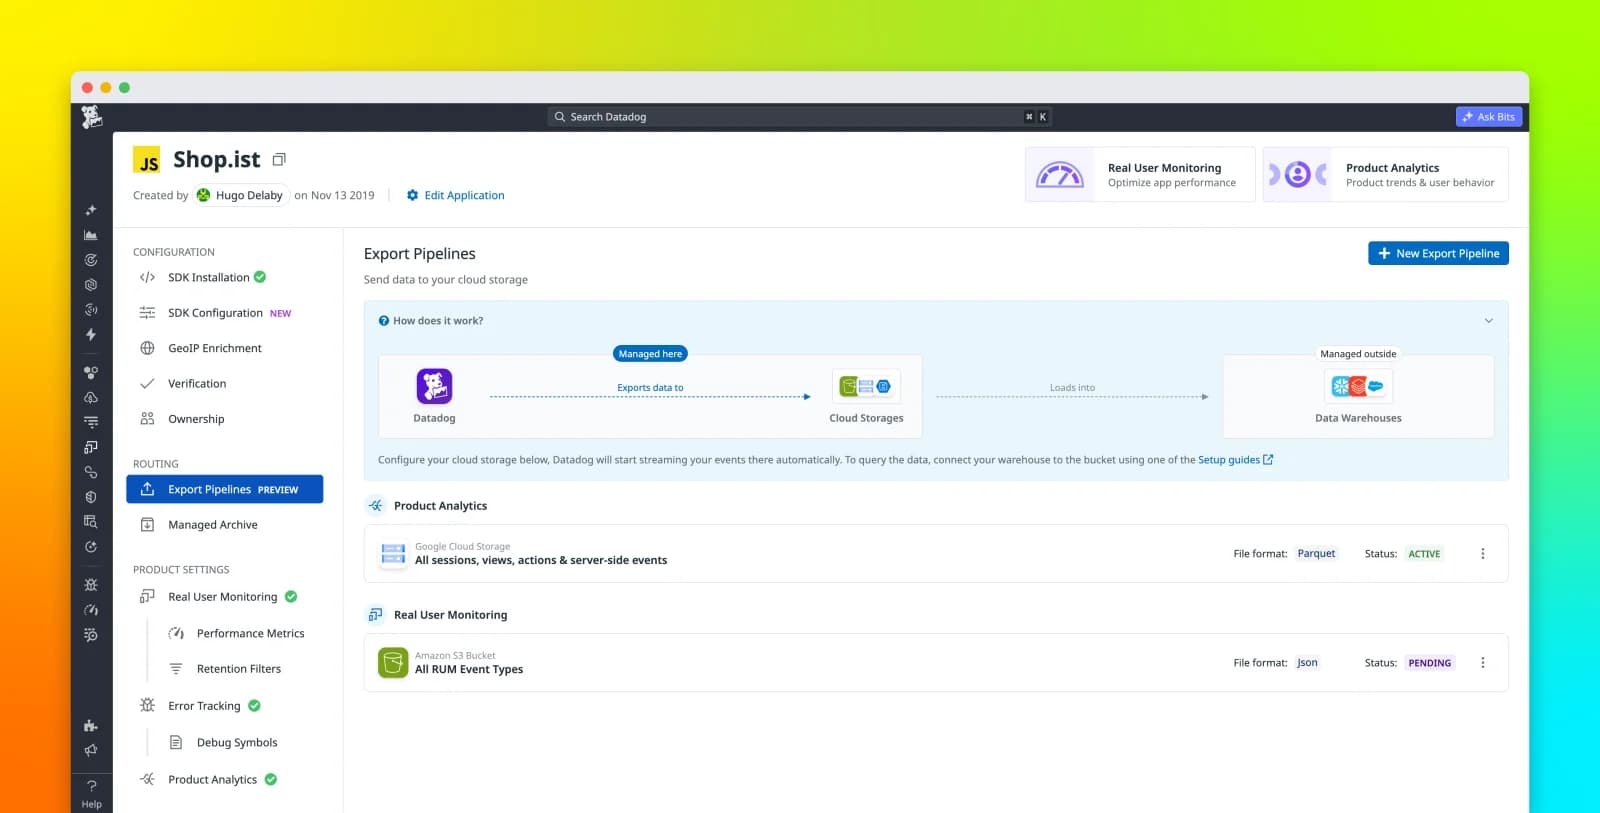
Finally, your system needs to provide ways to act that secure your environment from further compromise. AI Guard enables you to block offending users or IPs, open security cases, or trigger remediation workflows directly from a triggered signal. You can also push a case to Jira or your SIEM and handle it in your security teams’ existing systems.
Implement guardrails where engineers already work
Agents are owned by the engineers who build them, so controls that live outside the development workflow tend to stay unadopted. Because AI Guard lives in application teams’ tracing and monitoring systems, it gives engineers access to security enforcement where they already work. An engineer can turn on inline evaluation for their own agent without filing a ticket or standing up a proxy, and a security team can set the policy those evaluations enforce without knowing each agent’s internals.
AI Guard provides trace context for every evaluation, so your engineers aren’t left piecing together compromised data in logs after the request is already completed. In that same survey, 40% of respondents said that an AI agent making a decision without anyone knowing was their greatest concern. Visibility into what an agent reads and does gives your team a way to examine decisions that might otherwise go unnoticed. In this way, AI Guard bridges the gap between security engineering and development.
Engineers are already working within Datadog, making AI Guard an extension of their existing workflow, not a net new tool. On services already running the Datadog tracer, this enforcement can be turned on with one click. You can also hook AI Guard into yourown AI gateway for a single integration point that covers every agent that routes through it.
Scale AI agents without scaling risk
As agents rapidly iterate and expand in scope, models become more intelligent and more privileged, and attackers swiftly develop new strategies, agentic security systems need to keep pace, which is why we’re building AI Guard to self-harden and learn from your environment’s history. AI Guard’s detection is tuned to your agents and your policies, analyzes each action against behavioral norms, and redacts PII and secrets in each agent interaction.
The goal of this system is to create a closed loop where runtime security controls proactively detect and neutralize active threats across your agent loops, service dependencies, and infrastructure. Because AI Guard uses Datadog’s wealth of observability and security technology and context, AI Guard allows you to unify runtime security controls with application, infrastructure, and agent performance controls. This way, you can protect your agents, your infrastructure, and the customers that used them with a single platform.
AI Guard is now generally available. For more information about getting started, see the documentation. Or if you’re brand new to Datadog,