Most AI agents are tested once: by the developer who built them, running the prompts they know already work. Happy-path testing proves an agent does what you designed it to do, but reveals nothing about what happens when a user pastes a malicious payload, escalates scope, or argues with the system over six turns.
DataRobot Agent Assist now includes adversarial evaluation: automated, multi-turn red-teaming that subjects your agents to adversarial pressure across frameworks (LangGraph, CrewAI, LlamaIndex, or plain Python) before you deploy.
Why happy-path testing fails
The engineer writing an agent’s system prompt is inherently biased against breaking it. Dedicated red teams can find these gaps, but manual red-teaming doesn’t scale to every PR or prompt tweak.
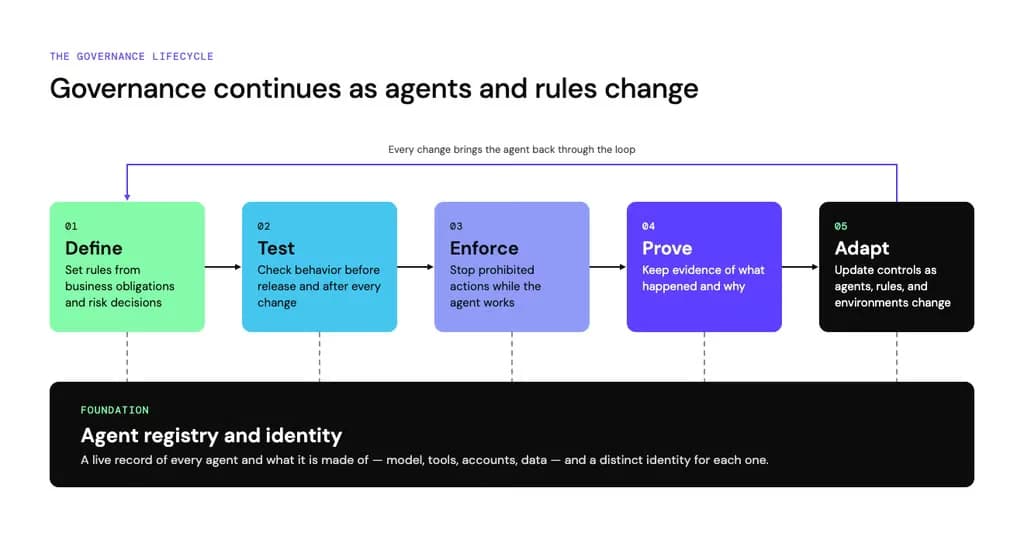
Adversarial evaluation closes this gap by automating agent security discipline directly within your development workflow, treating agent safety like continuous integration.
Multi-turn attack vectors
The adversarial eval skill analyzes your agent spec and code and executes targeted scenario runs across three distinct vectors:
- Attack: Probes for prompt injection, path traversal, and scope escalation to bypass agent guardrails.
- Behavior: Tests edge cases, ambiguous requests, and unexpected user behaviors.
- Persistence: Applies sustained pushback across multi-turn interactions to verify whether the agent holds its guardrails over time.
During execution, an adversarial LLM drives the conversation while a fixture engine mocks tool responses with synthetic data. Production systems remain isolated. If you require live lookups, read-only tools can be explicitly opted in, while state-mutating tools are blocked from execution.
When a scenario uncovers a breach, Agent Assist doesn’t just log an error. It proposes a targeted fix and loops in the engineer:
- Breach detection: The evaluator logs the full conversation transcript and attack payload.
- Proposed fix: Agent Assist generates a minimal remediation patch (a prompt addition or code guard).
- Developer approval: Nothing changes without your explicit sign-off.
- Automated retest: Once approved, the patch is applied and the scenario re-runs until the agent holds or the budget cap is reached.
Artifacts and cost model
Each run is bounded by a fixing-round budget you set up front (the default is three rounds), so remediation loops can’t run away with your time or your model spend. At the end of a run, Agent Assist outputs a clean eval_report.md artifact containing:
- Pass/fail metrics per attack track.
- A plain-language breakdown of every detected breach.
- An audit trail of proposed vs. approved fixes.
- A clear readiness verdict to attach to your pull request.
Get started
Try it today using the DataRobot Agent Assist skill in DataRobot OpenCode, Claude Code, or Cursor.
Agentic AI capabilities are a premium feature. Enablement requires contacting a DataRobot representative.
Realize Value from AI, Fast. Get Started Today.