Dev48
Language
  • About
  • Services
  • Industries
  • Technologies
  • Articles
  • Contacts
Book a call
    Home/Articles/Production ready distributed inference with ray serve
Dev48
info@dev48.org+375 29 320-40-96WhatsApp@isky_by

© 2026 · All rights reserved.

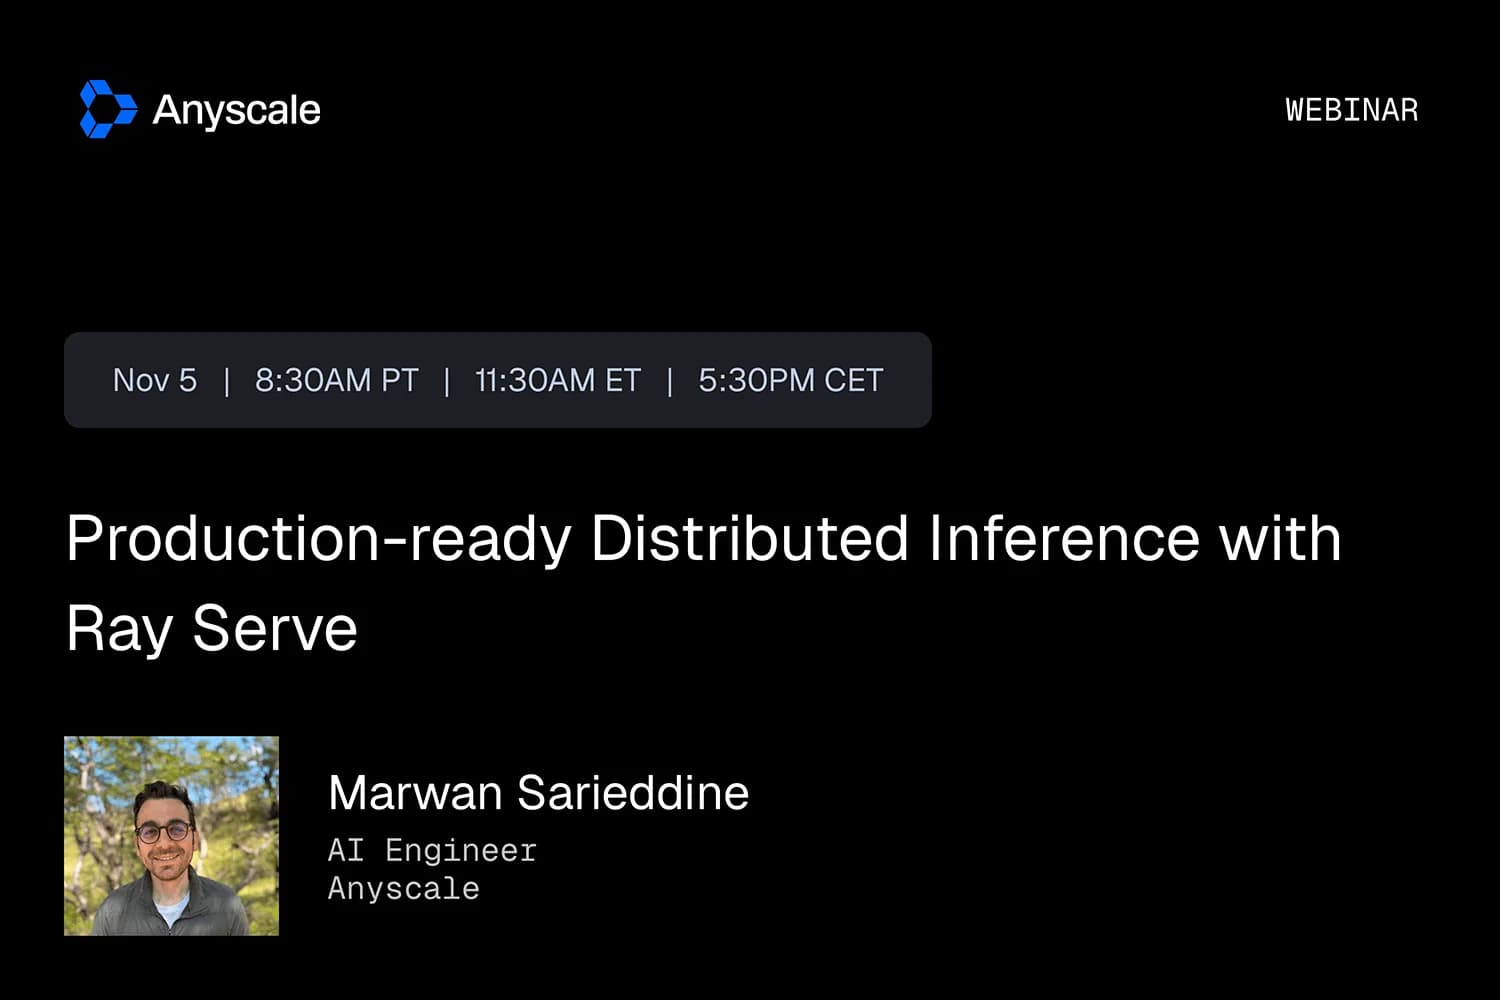
Production-ready Distributed Inference with Ray Serve

Source: Anyscale•November 6, 2026 at 06:10 PM

Production-ready Distributed Inference with Ray Serve

Scale AI inference to production with Ray Serve: LLM serving, autoscaling, vLLM/SGLang, KV-cache optimization, MoE parallelism, and cost comparisons.

Design scalable distributed inference systems for production AI applications, from classic ML models to large language models. Learn how Ray Serve delivers high-throughput, low-latency serving, and how to evaluate the performance tradeoffs in autoscaling, batching, routing, and inference-engine optimization.

Topics include:

  • Building Ray Serve applications with deployments, composition, and load-aware request routing

Building Ray Serve applications with deployments, composition, and load-aware request routing

  • Deploying and scaling LLM endpoints with Ray Serve LLM on engines like vLLM and SGLang

Deploying and scaling LLM endpoints with Ray Serve LLM on engines like vLLM and SGLang

  • Optimizing the inference engine with the KV cache, paged attention, prefix caching, and continuous batching

Optimizing the inference engine with the KV cache, paged attention, prefix caching, and continuous batching

  • Scaling frontier models with KV-cache-aware routing, prefill/decode disaggregation, and wide expert parallelism for mixture-of-experts (MoE) models

Scaling frontier models with KV-cache-aware routing, prefill/decode disaggregation, and wide expert parallelism for mixture-of-experts (MoE) models

  • Deploying Custom LLMs on Anyscale and Integrating Them with Agentic Platforms (Claude Code, Cursor, Codex)

Deploying Custom LLMs on Anyscale and Integrating Them with Agentic Platforms (Claude Code, Cursor, Codex)

  • Comparing costs across self-hosted GPUs, subscriptions, and token-based API billing.

Comparing costs across self-hosted GPUs, subscriptions, and token-based API billing.

← All articles

What this article says

More in Software Development

All →
Microsoft plans to use fewer neoclouds as AI buildout shows signs of strainПресса
Microsoft

Microsoft plans to use fewer neoclouds as AI buildout shows signs of strain

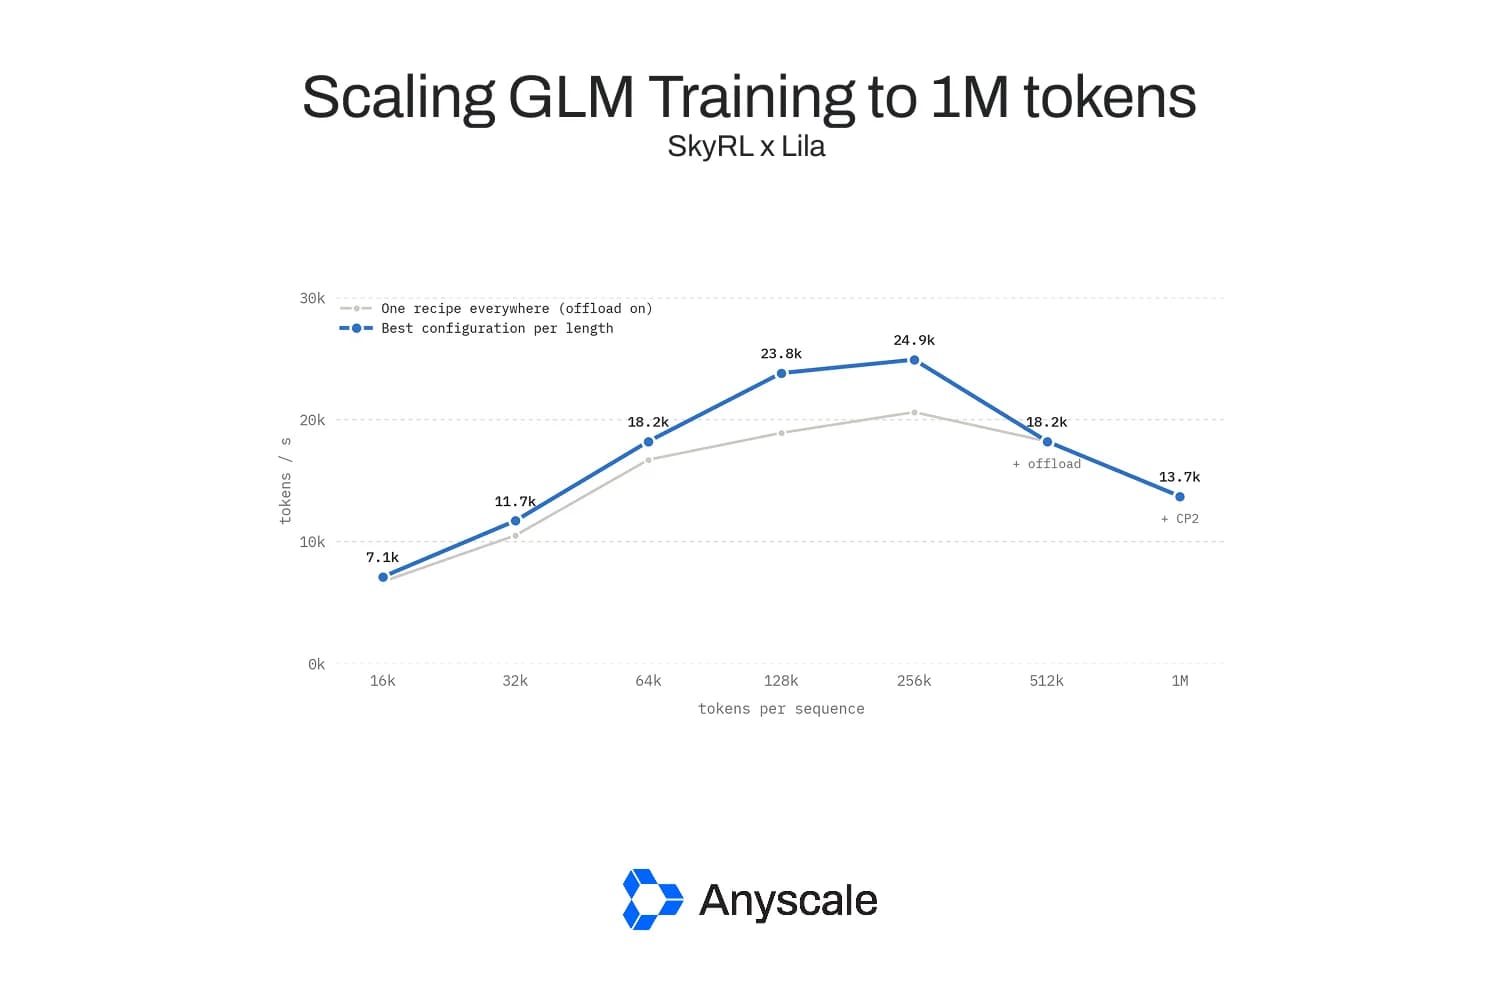
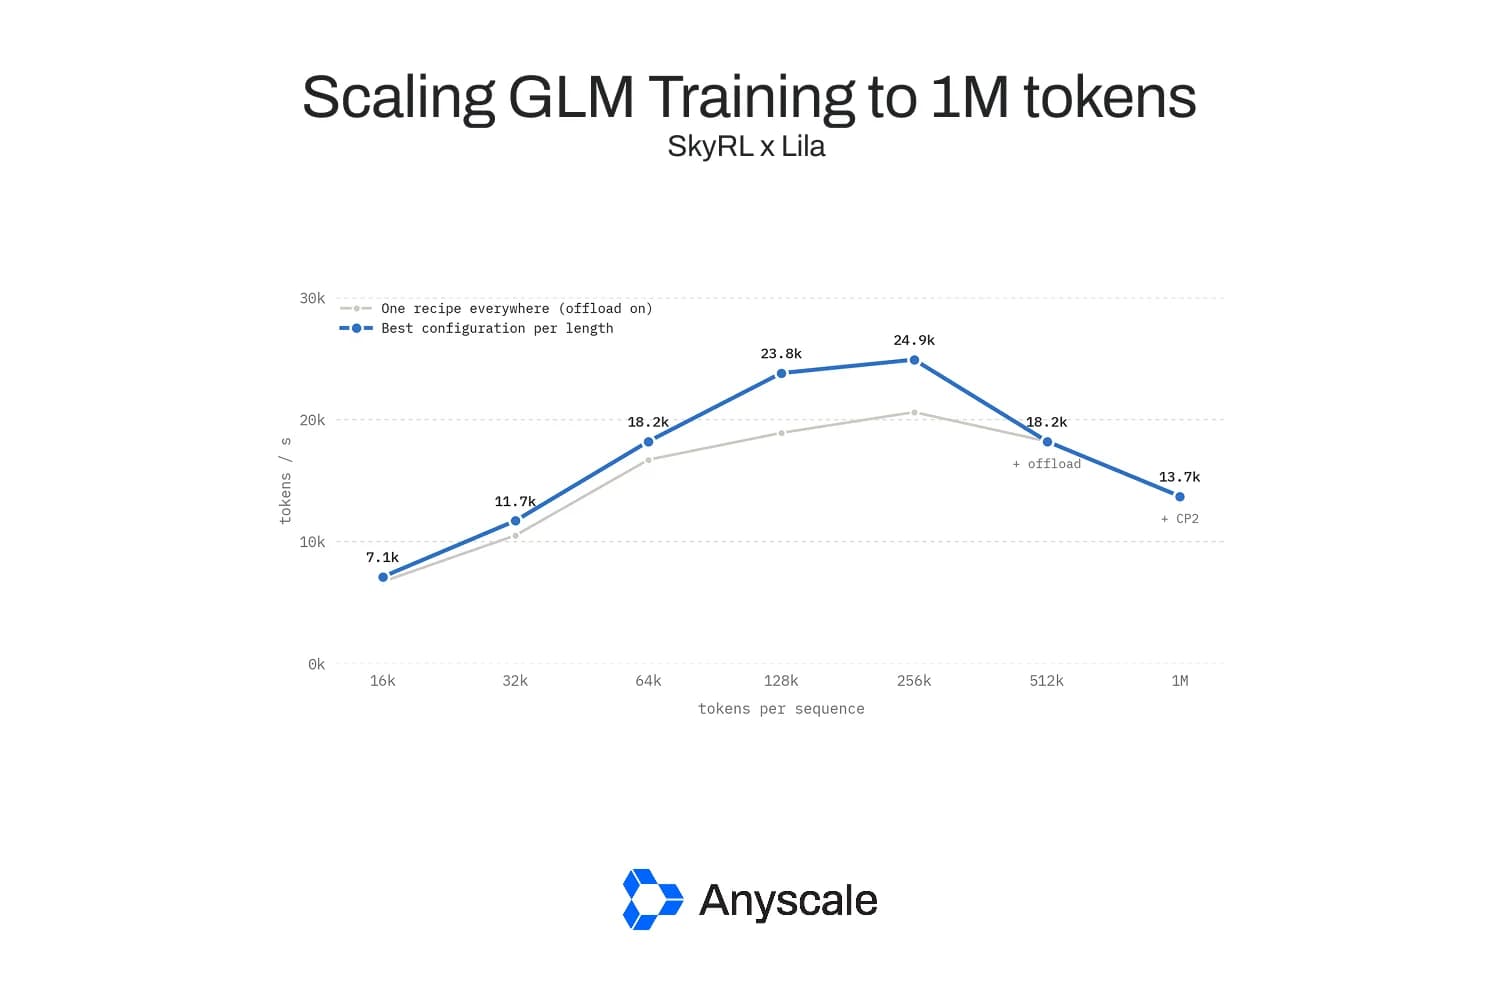
How Lila Sciences and Anyscale Scaled GLM-5.3-Flash Training to 1M tokens
Anyscale

How Lila Sciences and Anyscale Scaled GLM-5.3-Flash Training to 1M tokens

Anyscale on Azure: Build and deploy AI at scale in your own tenant
Anyscale

Anyscale on Azure: Build and deploy AI at scale in your own tenant

Shopify Editions Fall ’26: What It Means for Inventory, Orders, and Fulfillment
Ordoro

Shopify Editions Fall ’26: What It Means for Inventory, Orders, and Fulfillment

Protect your profit margins by designing discounts that pay for themselves
Woocommerce

Protect your profit margins by designing discounts that pay for themselves

CBP Rule on Foreign Importers of Record: What to Know
Flexport

CBP Rule on Foreign Importers of Record: What to Know

More from Anyscale

How Lila Sciences and Anyscale Scaled GLM-5.3-Flash Training to 1M tokens
Anyscale

How Lila Sciences and Anyscale Scaled GLM-5.3-Flash Training to 1M tokens

Anyscale on Azure: Build and deploy AI at scale in your own tenant
Anyscale

Anyscale on Azure: Build and deploy AI at scale in your own tenant

How Lila Sciences and Anyscale Scaled GLM-5.3-Flash Training to 1M tokens
Anyscale

How Lila Sciences and Anyscale Scaled GLM-5.3-Flash Training to 1M tokens

KubeRay in production: best practices from the field
Anyscale

KubeRay in production: best practices from the field

Announcing the Special Interest Group (SIG) for Ray on Accelerators
Anyscale

Announcing the Special Interest Group (SIG) for Ray on Accelerators

Announcing Ray support for PyTorch on Google TPUs
Anyscale

Announcing Ray support for PyTorch on Google TPUs