Enterprise AI coding powered by AMD, Supermicro, and Spectro Cloud - delivering up to 75% lower TCO
AI is becoming part of everyday software development—from generating code and modernizing applications to automating tests and reviewing pull requests. As usage expands, enterprises face a practical question: how do they extend these productivity gains across their engineering teams while controlling costs and protecting proprietary code?
Frontier models offer powerful capabilities, but relying on them for every task can make costs difficult to predict. Longer context windows, repeated agent interactions, and growing adoption increase token consumption. Organizations also need clear policies governing when source code, prompts, and other sensitive information can be sent to external services.
Moving more inference on premises offers a way forward. Yet assembling servers, GPUs, inference software, models, and operational controls can be challenging and time consuming.
Following the success of the AMD Instinct Coder 325, the AMD Instinct Coder 355 brings together AMD, Supermicro, and Spectro Cloud to address all of these challenges with a turnkey enterprise AI assisted coding platform. The solution enables everyday coding workloads to run on premises and allows frontier services only when justified and is within enterprise data policies.
A complete platform for on premises AI coding
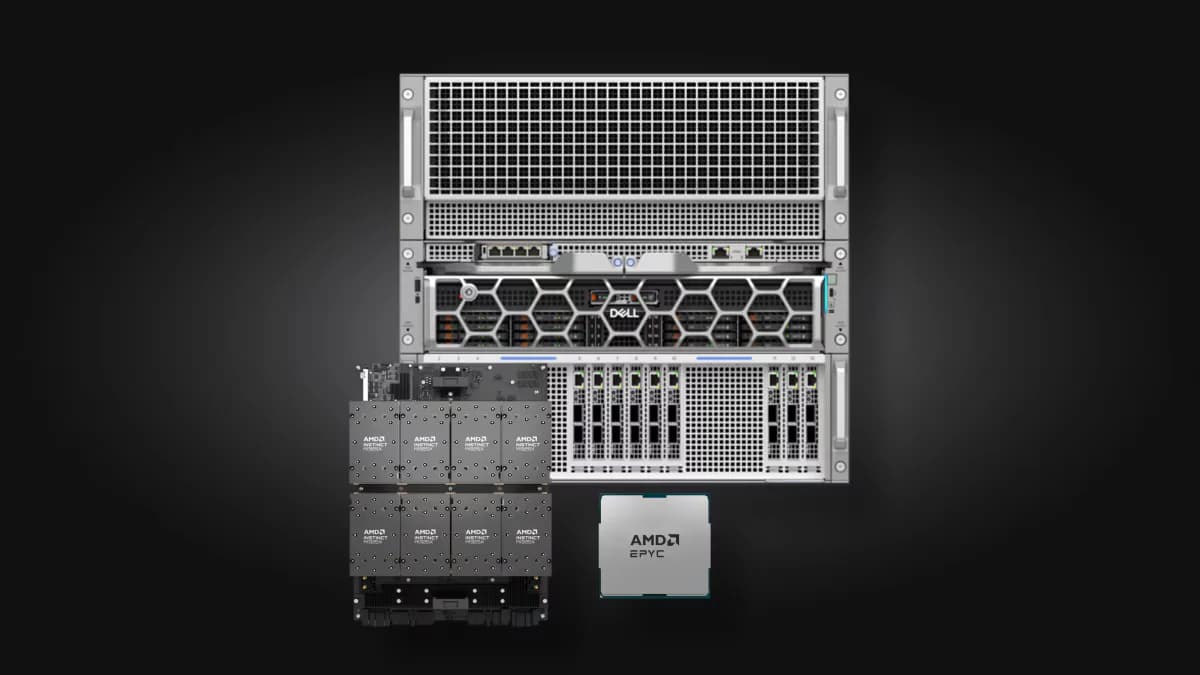
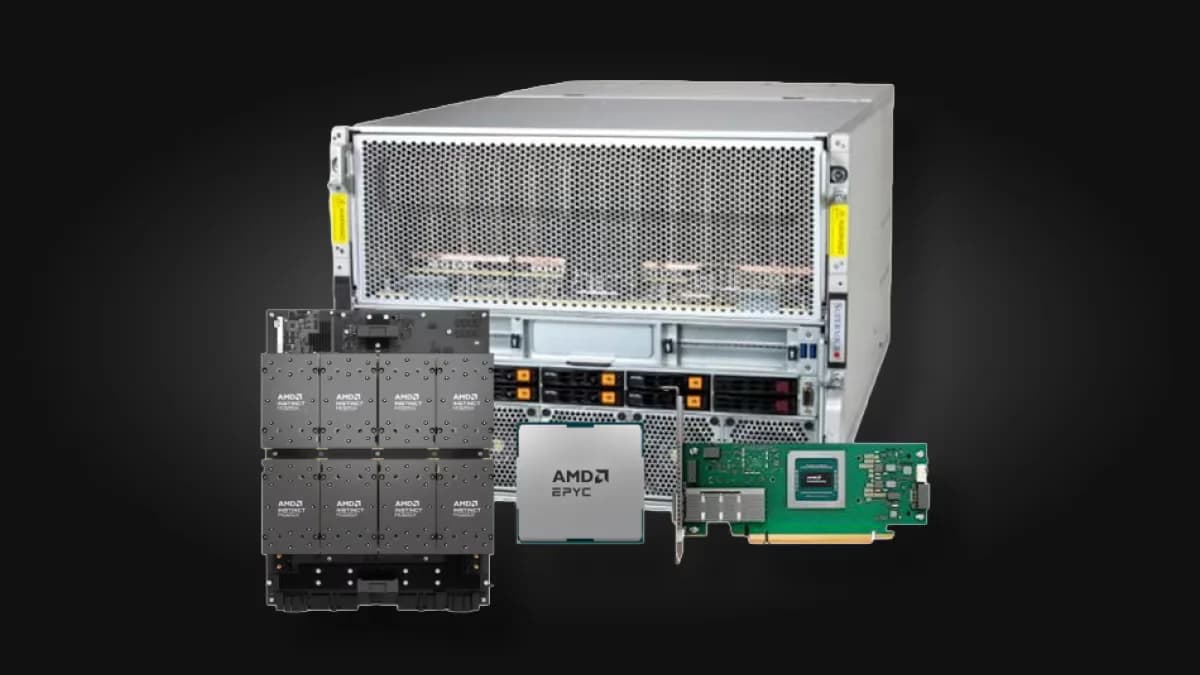
The solution combines Supermicro servers powered by AMD EPYC™ processors, AMD Instinct™ MI355X GPUs, and AMD Pensando™ Networking along with the GLM 5.3 model, and Spectro Cloud PaletteAI Inference Launchpad software.
AMD provides the compute foundation for local inference. Supermicro brings enterprise server infrastructure and hardware support options. Spectro Cloud integrates deployment, operations, and governance to help IT teams deliver AI coding as an internal service.
Together, these capabilities provide a turnkey inference stack, giving engineering teams access to AI assistance while helping IT retain control over infrastructure, usage, cost, and data.
Run local by default, use frontier only when justified
Every coding request does not require a frontier model. Code generation, test creation, documentation, and routine code review can be candidates for local inference, based on the selected model and the organization’s quality requirements.
PaletteAI Inference Launchpad provides intelligent routing that directs requests to local models by default and permits approved frontier services when task requirements justify them and IT policy allows. Platform teams define routing policies, including which workloads are eligible to leave the on-premises environment.
This gives enterprises a practical way to balance capability and cost. Teams can use local models for suitable workloads while retaining access to frontier capabilities for more demanding tasks if needed. Sensitive workloads can remain local under enterprise policy; requests routed externally send their associated content to the selected service and must meet the organization’s data-handling requirements.
Make AI coding costs easier to control
Moving suitable workloads on premises reduces reliance on metered frontier APIs and shifts more inference spending to infrastructure that enterprises can plan and manage. Frontier spending can then be reserved for requests where the expected benefit warrants it.
Usage metering, quotas, and operational visibility help administrators understand demand and govern consumption. Rather than treating AI coding as an open-ended expense, enterprises can manage it as a shared service with defined capacity, access policies, and budgets.
The economics depend on utilization, model choice, workload characteristics, operating costs, and the share of requests routed externally. Evaluating these factors against actual developer usage helps organizations size the platform and assess potential savings.
Protect code and preserve choice
For workloads processed locally, source code, prompts, and model context remain within the enterprise environment. Access controls and usage policies help teams govern who can use the service and how it is consumed.
Open models and standard API integration also give organizations flexibility as their needs evolve. Teams can evaluate new local models, adjust routing policies, and connect approved external services without making one frontier provider the default destination for every request.
Developers can connect supported coding tools to the platform, allowing organizations to introduce local inference within familiar workflows. Tool compatibility and available features depend on the validated model, endpoint, and client configuration.
Scale developer productivity with greater control
AMD Instinct Coder 355 gives enterprises a practical foundation for expanding AI-assisted development with greater control over cost, data, and operations. AMD compute, Supermicro infrastructure, and Spectro Cloud management bring the core components together in an integrated platform.
Run suitable workloads on premises. Use frontier models when the task warrants them and policy allows. Give developers the AI capabilities they need while keeping infrastructure and spending aligned with enterprise priorities.
Contact your AMD, Supermicro, or Spectro Cloud representative to discuss the right configuration for your development teams.
Solution details
Supermicro AS-A126GS-TNMR server
- 2 x AMD EPYC™ 9575F, 64 cores, 3.3GHz CPUs
- 8 x AMD Instinct™ MI355X AC 288GB HBM3e, UBB8
- 3TB (24 x 128GB) DDR5 RDIMM 6400 ECC
- 2 x 960GB NVMe PCIe® Gen4 V6 M.2
- 8 x 7.68TB PCIe Gen5 TLC U.2 SSD
- 2 x AMD Pensando™ Pollara 400 HHHL PCIe NIC, 400GbE
- 6 x 5250W redundant (3+3 configuration) titanium-level high-efficiency power supplies
Spectro Cloud PaletteAI Inference Launchpad
- Full-Stack AI lifecycle management
- Enterprise governance at scale
- Intelligent local-first model routing, frontier when justified
- Full visibility and control of AI usage and cost
- Local: GLM-5.3
- Frontier: Anthropic Claude, OpenAI GPT, Google Gemini
- Claude Code, Cursor, Visual Studio Code
- Comprehensive full stack software support from Spectro Cloud
- 3 yr next business day (NBD) on site from Supermicro for hardware
- Supports up to 85 developers per node, (50 concurrent)
- Up to 98% of Frontier model benchmark performance