Key takeaways
- Amazon's TorchNeuron runs existing PyTorch code on Trainium with no rewrite.
- TorchNeuron will be open-sourced at the PyTorch Conference on October 20.
- Startups and enterprises in robotics, video, world models, self-driving cars, speech, drug discovery, LLMs, and finance are already building on it.
Today, 85% of AI researchers and developers write their code in PyTorch. Until now, the hardware that code could run on was far more limited than the code itself, and expanding to new chips meant rewriting and revalidating work that took months to perfect.
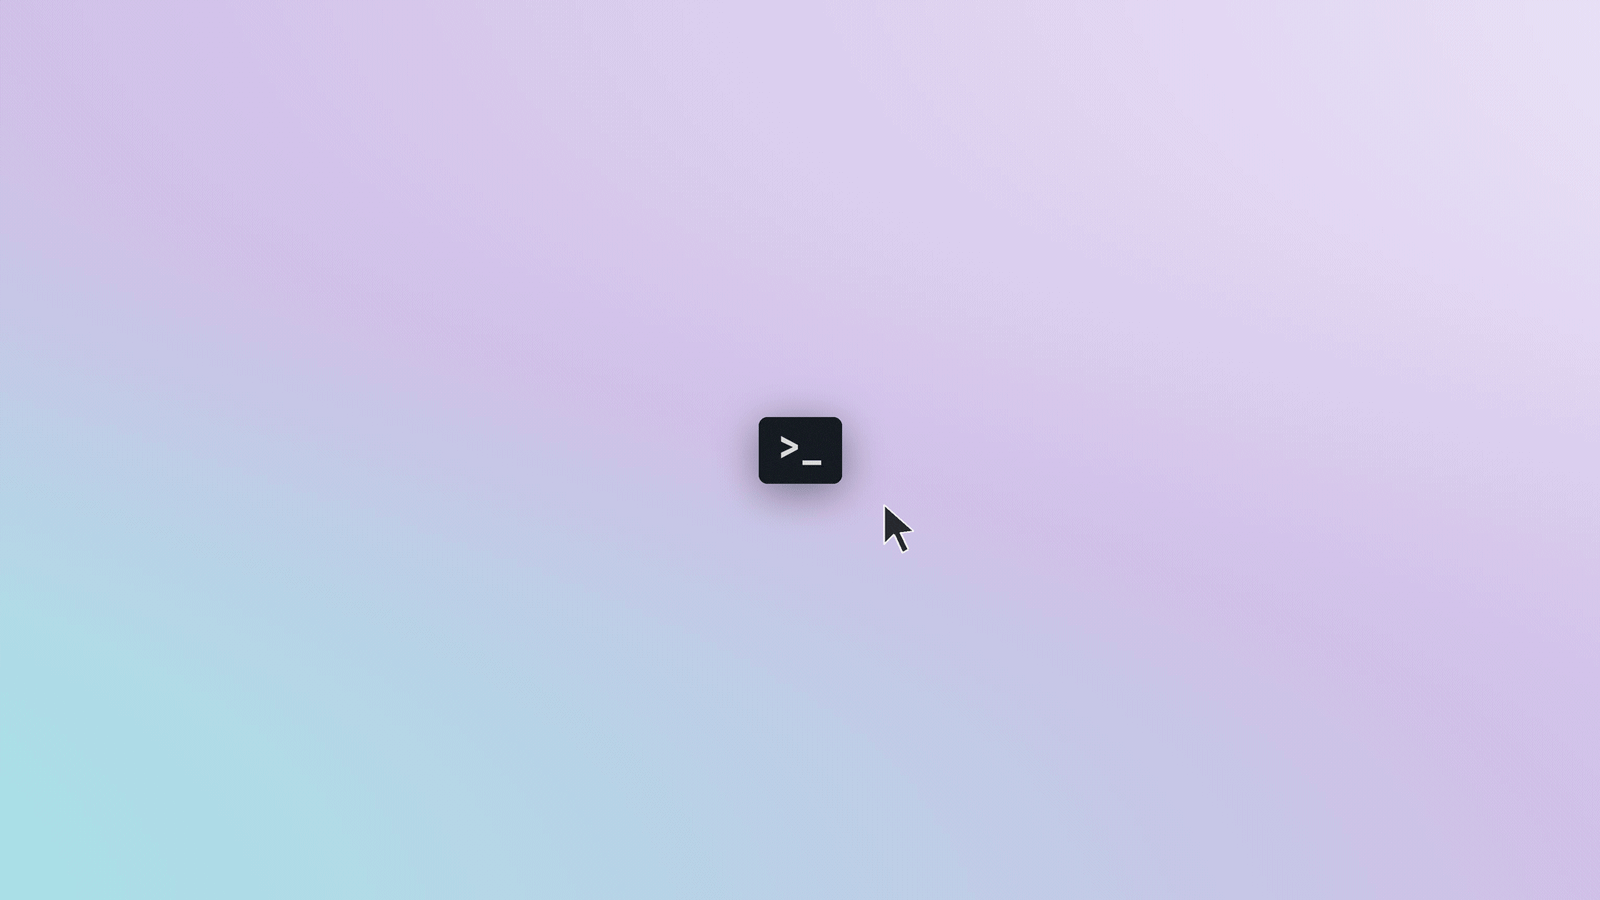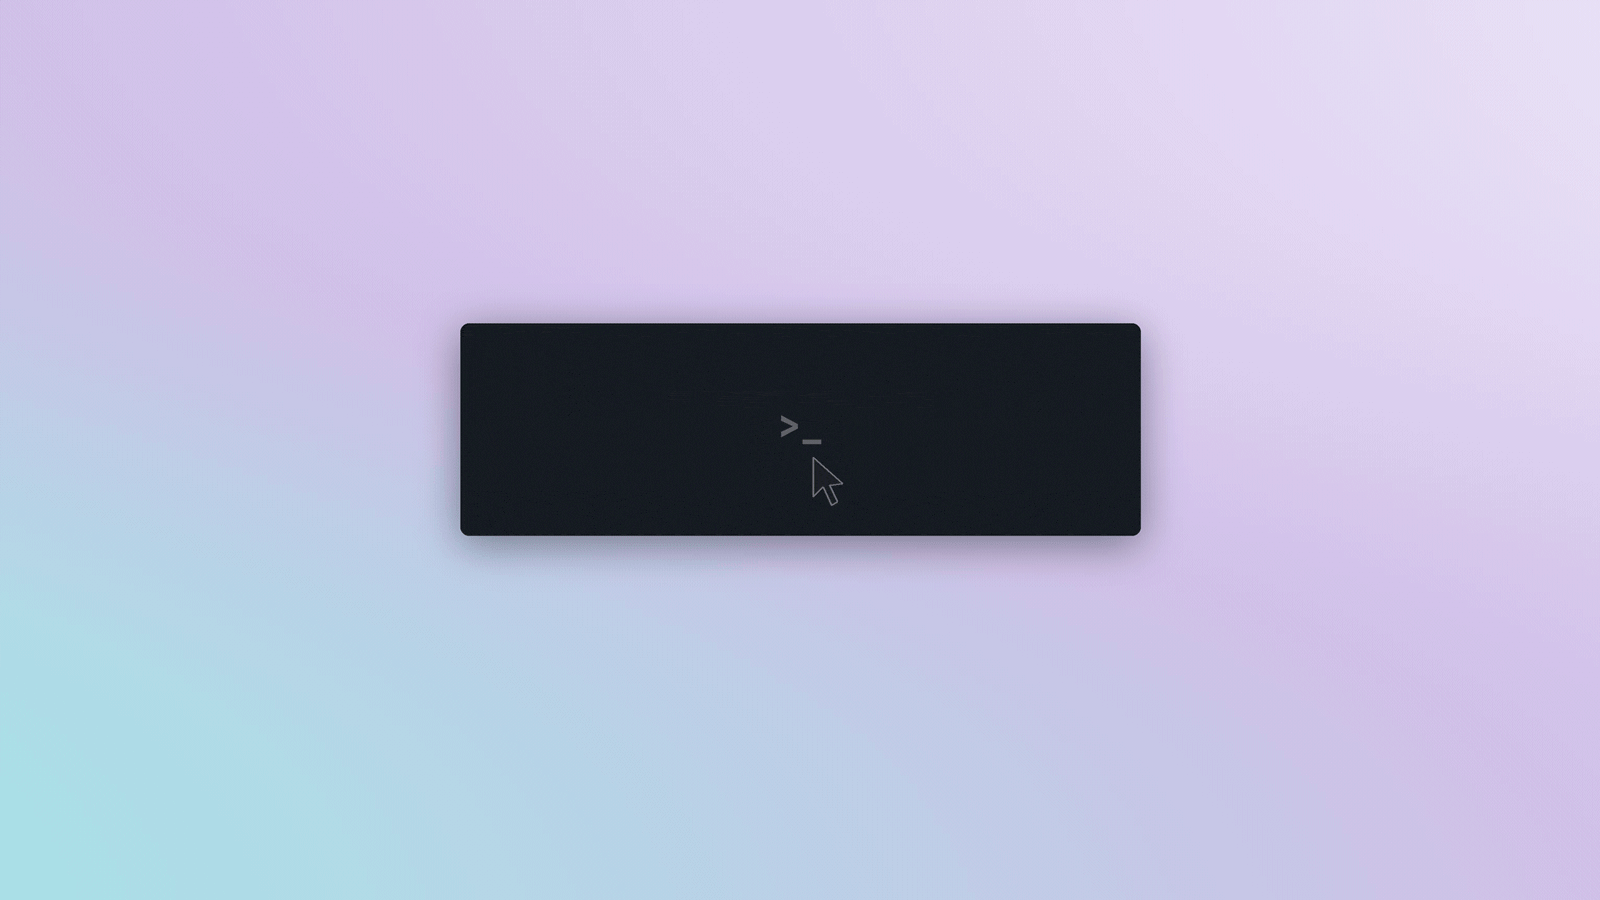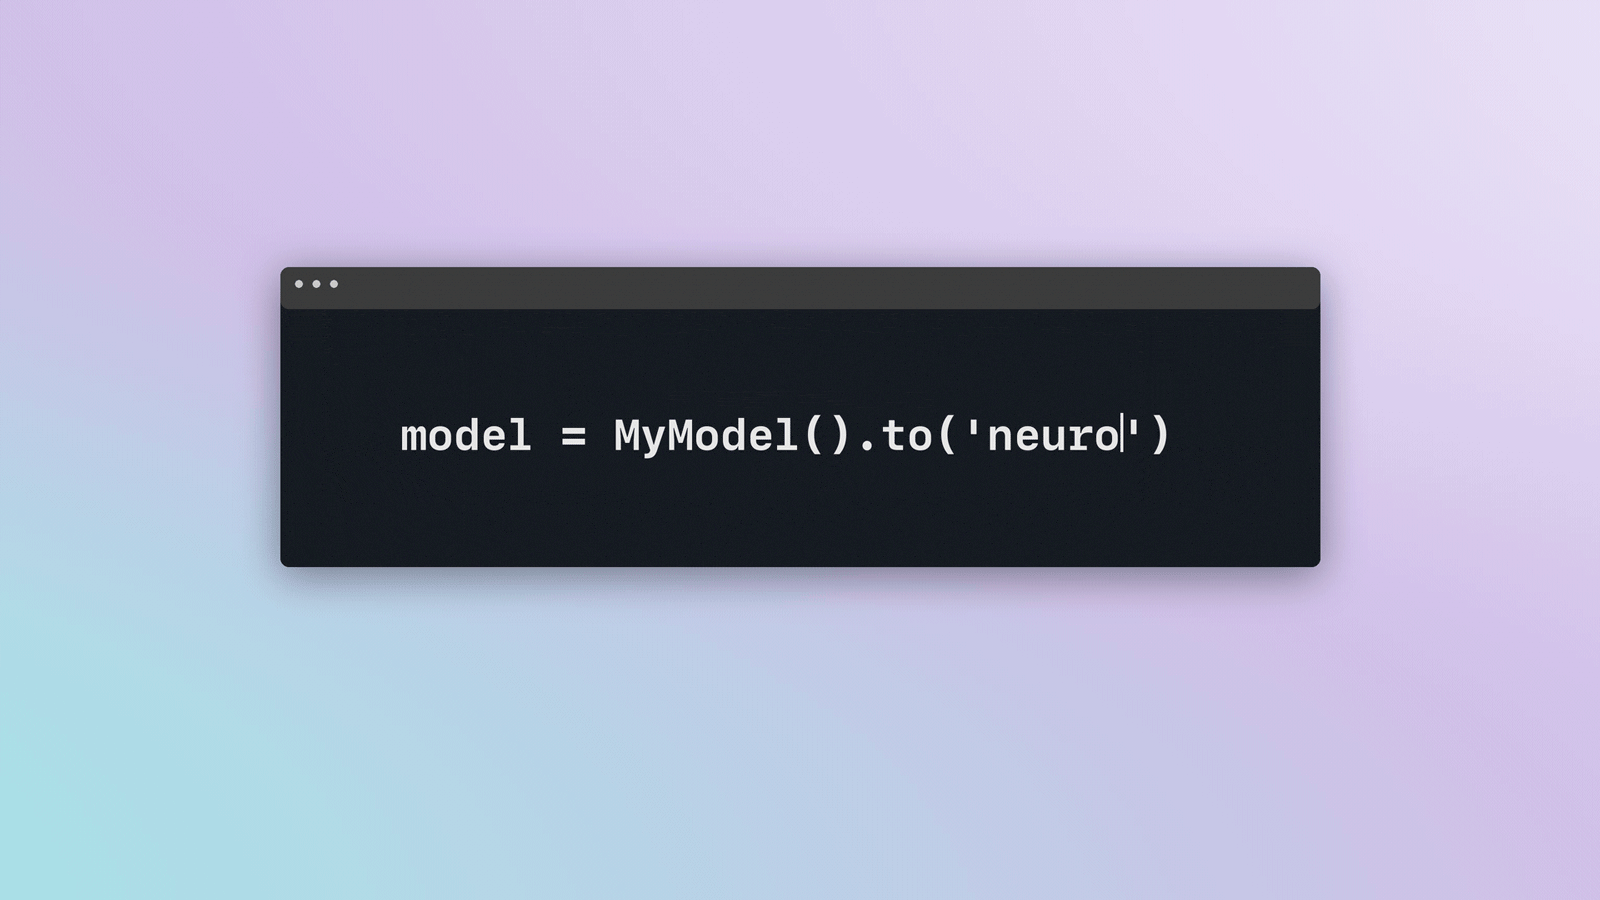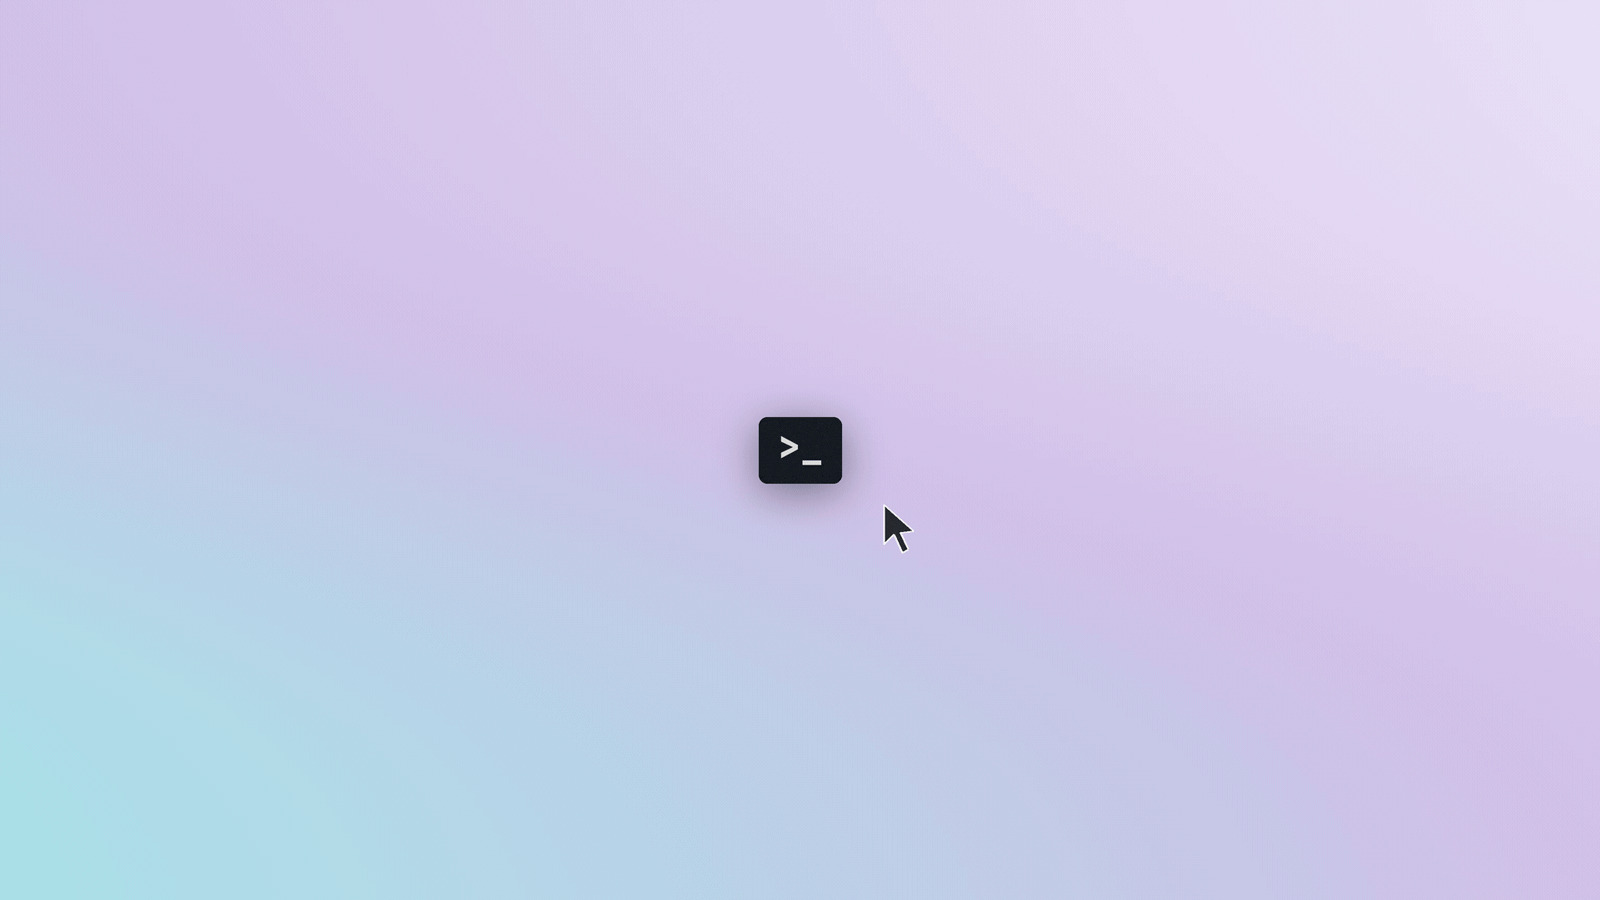
Amazon is now closing that gap. With TorchNeuron, the PyTorch code developers already write runs natively on Amazon's AWS Trainium chips, with a single configuration change and no rewrite. TorchNeuron will be released under an open-source license at the PyTorch Conference North America on October 20.
What does “no code change” actually mean?
Think of your AI code as a car you've spent years fine-tuning. The engine, the suspension—every part working together. A new, more affordable engine comes along with serious horsepower, but installing it would mean tearing down the car and rebuilding it piece by piece. TorchNeuron lets you swap in the new engine without taking the car apart.
In a side-by-side demonstration, Amazon engineers ran the same AI training script on a conventional chip and on Trainium. The only difference was a setting that told the code which chip to use. Results showed that the AI model learned the same things at the same rate.
For developers, this is significant. PyTorch already has a built-in way for new hardware to register itself. TorchNeuron plugs into that standard mechanism, meaning the tools developers already use to test, debug, and scale their AI models all work on Trainium without modification.
Why TorchNeuron matters for developers and for the industry
The real cost of AI goes beyond the price of a chip. For many companies, especially startups, the most expensive line item is engineering time. Every week a developer spends adapting software for new hardware is a week not spent improving the product. For small teams with limited resources, that trade-off can contribute to whether a company succeeds or fails.
And it’s not just startups. For large enterprises running massive AI fleets, the ability to use the same hardware for both training and inference is a game changer. During off-peak hours, capacity that served inference workloads can shift seamlessly to training jobs, getting more value from the same hardware instead of leaving specialized hardware idle.
By reducing the friction of adopting new hardware, TorchNeuron introduces something the AI industry has largely lacked: meaningful choice. When developers can move between chips without penalty, chipmakers have to earn developers' business, and developers benefit from lower costs and faster iteration.
From voice AI to drug discovery: who's already building on TorchNeuron
TorchNeuron's early adopters span a wide range of AI applications. From real-time voice to molecular design, they share a common thread: they moved to Trainium without rewriting their code.
Cartesia is building intelligence that learns from and interacts with the world the way humans do, starting with conversation. With PyTorch native support on Trainium, Cartesia ran its standard inference pipeline with minimal changes to its PyTorch code. The applications extend into healthcare, too. The Lieber Institute for Brain Development, the largest research institute dedicated to developing new medical interventions for major neuropsychiatric conditions like schizophrenia, uses biological, chemical, and language AI models across drug target and drug discovery. Molecular dynamics simulations are powerful but extremely computationally expensive, and an emerging generation of AI tools offers the potential to accelerate or replace them. TorchNeuron allows the Lieber Institute to explore these strategies on Trainium, from initial model exploration through optimizing performance for bottlenecks.
Opening up the chips ecosystem
Amazon's approach extends beyond its own hardware. The company is contributing changes upstream to PyTorch itself, working with the PyTorch community to remove code that ties the framework to specific chips. The goal is to make PyTorch more hardware-agnostic for the entire developer community, not just Trainium users.
To maintain quality, Amazon tests TorchNeuron against hundreds of thousands of AI models on every build, so issues are caught before any customer workload runs.
Hugging Face has enabled native Trainium support directly in its popular AI development tools, allowing developers to work on Trainium natively without requiring any Amazon-specific code.
TorchNeuron integrates with TorchTitan, PyTorch's native distributed training framework, giving developers a standard path for scaling model training across Trainium instances using Fully Sharded Data Parallelism (FSDP)—the same tools and patterns they use on any other PyTorch device.
For developers who want to go deeper, TorchNeuron offers tools for scaling training across multiple chips and writing custom low-level code for maximum performance. Amazon has also made a major open-source contribution to vLLM, a popular open-source tool for speeding up inference, and open-sourced its complete set of performance kernels, giving developers a starting point when building their own.
What's next
TorchNeuron supports Trainium2 and Trainium3. It will be released as open-source under the Apache 2.0 license at PyTorch Conference North America on October 20.
TorchNeuron is the latest chapter in Amazon’s decade-long investment in custom silicon. Since acquiring chip design company Annapurna Labs in 2015, Amazon has built four chip families from the ground up, each designed for a specific cloud workload. With TorchNeuron, the company is now making that hardware accessible to any developer who writes in PyTorch.